
Technology
Breaking News
TinyFish Breaks Down Agentic Search Architecture for Production AI Agents
TinyFish published two engineering research articles on agentic search. One defines a 7-phase production architecture with evidence contracts and bounded retries. The other explains why its deep research system dropped a separate planner and per-query subagents.
Google Cloud Launches Agent Compute Engine: A MicroVM per AI Agent
Google Cloud announced Agent Compute Engine, a compute service that gives every AI agent its own hardware-isolated microVM with no credentials inside. It already runs Gemini agents and enters preview in the coming months.
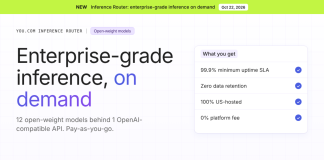
You.com Launches Inference Router: 12 Open-Weight Models With 99.9% Uptime SLA
You.com launched Inference Router, an OpenAI-compatible API for 12 open-weight models with a 99.9% uptime SLA, zero data retention, 100% US hosting, server-side web search and no platform fee.
Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms...
Liquid AI released RIPL, a real-time inference engine for its LFM models. On one B200, LFM2.5-1.2B on RIPL showed 14.4 to 28.4x lower p95 latency than Qwen3.5-0.8B on vLLM.
Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0
Gradium has open-sourced Phonon, a family of on-device text-to-speech models. The English Phonon 31m ships under Apache 2.0, fits in 64.5 MB, and starts speaking in about 7 ms on a laptop CPU.
Cohere Releases Rerank 5 With Passage-Level Context Focus and Calibrated Scores
Cohere Rerank 5 ships in Pro and Fast tiers with a 32K context window, Context Focus passage extraction and calibrated relevance scores. Pro scores 82.2 on BRIGHT and costs $0.05 per 1M tokens.
A Developer’s Guide to OmniParseBench: Leaderboard Benchmarks and OCR Testing
Explore how to audit and rebuild Datalab's OmniParseBench, test parser ranking certainty with document-level bootstrapping, and evaluate Tesseract and Indra OCR performance on a custom sample.
IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and...
IBM released Granite Speech 5.0 2B, an Apache 2.0 speech recognition and translation model. It ranks #2 on the Open ASR Leaderboard with 5.68% average English WER, alongside updated Turbo CTC and 4.1 2B Plus models.
Perplexity and NVIDIA Researchers Introduce JOLT: a Joint Teacher-Student Reinforcement Learning...
Perplexity and NVIDIA introduced JOLT, a post-training method that trains one model as both teacher and student. On MATH it matched GRPO’s accuracy with 6.5x fewer processed training tokens.
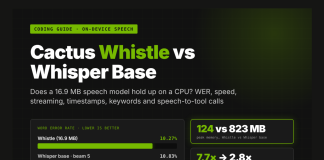
A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech...
Explore a comprehensive coding guide benchmarking Cactus Compute's 16.9 MB speech model against Whisper base. Learn about word error rates, CPU speed, streaming latency, and speech-to-tool integration.
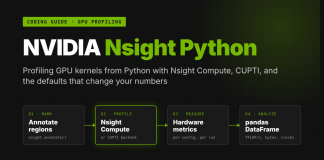
NVIDIA Nsight Python Tutorial: How to Profile GPU Kernels
Discover NVIDIA Nsight Python, an open-source interface that allows developers to profile GPU kernels, analyze hardware metrics, evaluate cache and clock controls, and measure kernel fusion directly from Python code.
Recursive Releases Flint, an Open-Weight 40B MoE Local Coding Model for...
Recursive has released Flint, an Apache 2.0 local coding model with 40B total and 2.5B active parameters. It reports 74.2% on SWE-bench Verified and 125+ tokens per second on an M4 Pro MacBook Pro.
Vercel Open-Sources durable-harness for Crash-Proof Coding Agents
Vercel released durable-harness, an open-source package that logs every model and tool call so Pi, OpenCode, Claude Code and Codex sessions resume after crashes, timeouts and redeploys on Vercel, Postgres or a laptop.
Mistral AI Releases Voxtral 3: Speech-to-Text, TTS and a Voice Agent...
Mistral AI released Voxtral 3, a family of 3 transcription models, 1 text-to-speech model and a LiveKit-based voice agent SDK. Voxtral Small Transcribe 3 scores 2.1% AA-WER, ranking #3 on Artificial Analysis.
Google Cloud Ships llm-d 1.0 With Cache-Aware Routing for TPU and...
Google, Red Hat and IBM released llm-d 1.0, an open-source Kubernetes-native stack for distributed LLM inference. It adds multi-tenant flow control, zero-downtime upgrades and agent-aware routing across vLLM, SGLang, TPUs and GPUs.
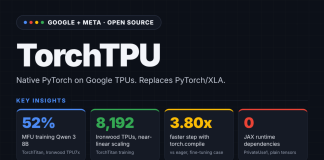
Google Open-Sources TorchTPU, a Native PyTorch Backend for Cloud TPUs
Google and Meta open-sourced TorchTPU, a native PyTorch backend for Cloud TPUs. It runs eager by default, compiles through torch.compile and XLA, and replaces PyTorch/XLA for new workloads.
DeepSeek Open-Sources DeepInfer, the Inference Framework Behind DeepSeek-V4.1-Flash
DeepSeek has open-sourced DeepInfer, the Apache 2.0 inference framework that serves DeepSeek-V4.1-Flash in production. It targets NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, and ships offline inference only.
Exa 3.0 Search API Tops Perplexity, Brave and Parallel on 8...
Exa 3.0 is a search API upgrade from Exa. It adds a larger embedding model, Exa Lite at $4 per 1,000 requests, and Dynamic Highlights, and leads 8 benchmarks Exa ran itself.
Cloudflare Releases Clairic, a System One Extraction Model on Workers AI
Cloudflare has previewed Clairic, a System One extraction model on Workers AI that returns typed values with confidence scores in one forward pass. It costs $0.10 per million input tokens and charges nothing for output.
Inception Releases Mercury 3 Diffusion LLM at 1,068 Tokens per Second
Inception released Mercury 3, a diffusion LLM it says runs at 1,068 tokens per second with a 1M-token context. On Inception’s own table it leads GPT-6 Luna and Claude Haiku 5.5 on 8 of 12 benchmarks.
Meet Drex Max: Nace AI’s Multimodal Decision Model for Computer-Use Agents...
Nace AI released Drex Max, a multimodal decision model that reads text and screenshots and returns calibrated probabilities. Nace reports 67.59 on Decision Index 0.3.2 at $0.06 per 1M input tokens.
MiniMax Just Launched M3.1 Flash: 428B MoE Agentic Model at $0.15/M...
MiniMax has released M3.1 Flash, a 428B-parameter MoE model with about 23B active parameters and a 1M-token context. API pricing is $0.15/$0.60 per 1M tokens, with weights due October 23
NVIDIA Open Sources Run:ai Under Apache 2.0 for Kubernetes GPU Orchestration
NVIDIA has released the full Run:ai GPU orchestration platform as open source under Apache 2.0. The release includes KAI Scheduler, CUDA 13.4 GPU fractioning, quota management, and a local Kind dev environment.
Mistral AI Releases Timestral: A 209M Forecasting Model Family That Outperforms...
Mistral released Timestral, a time series foundation model family from 5M to 209M parameters. The 209M model leads GIFT-Eval, TIME and fev-bench among zero-shot models and runs on CPU.
TinyFish Makes Search Free: What It Really Costs an AI Agent...
An AI agent that reads the web pays 2 kinds of cost. The first is the retrieval charge: what a search or fetch API...
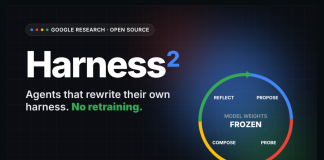
Google Open-Sources Harness2, a Recursive Agent Harnessing Framework
Google Research released Harness2, an Apache-2.0 framework that rewrites an agent's harness at test time. One refinement step lifted GLM-5 by 11.5 points on WorkBuddy-Bench with no weight updates.
How to Make Zero-Training Tabular Predictions with NVIDIA Structured Data Models
In this tutorial, we implement Structured Data Models, NVIDIA's new library that puts several pretrained foundation models for tables behind one PyTorch interface, and...
Meet Voxel51 3.0: A Unified Multimodal Data Platform for Physical AI
Voxel51 3.0 merges search, curation, annotation and evaluation of multimodal sensor data into one platform for physical AI teams. It adds Voxel51 Agent with 45+ MCP tools, dataset versioning, and a free self-service tier.
Meet Kyutai REKI: The 2.4B VLA Model Bringing Efficient Memory to...
Kyutai, with Inria and École des Ponts, has released REKI, a 2.4B vision-language-action model (VLA) for robot manipulation. The REKI vision-language-action model is pretrained...
DeepSeek Just Released V4.1-Flash-1017, Scores 77.0 on DeepSWE, Opens Search API
DeepSeek has just released DeepSeek-V4.1-Flash-1017, a new checkpoint of its V4.1-Flash model. It is live on the DeepSeek website, app and API. DeepSeek claims...
20 Jev Alternatives: The Decision Models Taking On TypeSafe in 2026
TypeSafe launched Jev on September 15, 2026. It is a decision model, not a chatbot. You define the allowed answers, and Jev returns a...
StepFun Releases Step 5 Preview Open Weights: 600B MoE, 27B Active,...
StepFun has released Step 5 Preview as open weights. FP8 and BF16 checkpoints are live on Hugging Face and ModelScope. Step 5 Preview is...
Perplexity Open-Sources SPACE, a Firecracker MicroVM Sandbox for AI Agents
Perplexity has open-sourced SPACE, the sandbox platform behind every task in Perplexity Computer. The Perplexity SPACE sandbox gives each agent task its own Firecracker...
Liquid AI Releases d1-ultra: A Multimodal Decision Model That Scores 65...
Liquid AI released d1-ultra, a text and image decision model that returns calibrated probabilities in 1 forward pass. It scores 65 on the Artificial Analysis Decision Index and costs $0.042 per million input tokens.
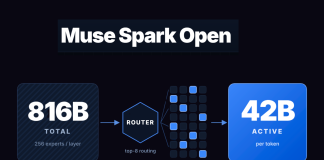
Meta Releases Muse Spark Open: 816B Open-Weight MoE With 1M Context
Meta released Muse Spark Open, an 816B-parameter open-weight MoE model with 42B active parameters and a 1M-token context. It leads open models on MCP-Atlas and runs on 2 M5 Ultra Mac Studios.
NVIDIA Releases Nemotron 3.5 Super VL, a 120B Open Multimodal Agent...
NVIDIA released Nemotron 3.5 Super VL, an open 120B-parameter multimodal MoE model with 12B active parameters, 1M-token context and NVFP4 weights that run on 1 DGX Spark, plus 2 Bolt edge models.
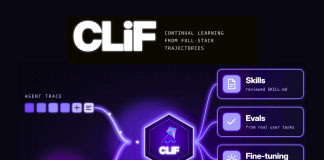
CopilotKit Releases CLiF: A Continual Learning Platform That Turns Agent Traces...
Introduction
Teams shipping AI agents at scale keep running into the same pattern. Even agents built on top-tier models like Fable and Astra struggle to...
openKylin Outlines Its Vision for Reimagining Linux in the AI Era...
At Open Source Summit Europe 2026, openKylin outlined its vision for transitioning from resource management to intent management in the AI era. The community introduced KART, a unified AI runtime, alongside core desktop features in openKylin 3.0 like the AI Assistant, Global Intelligent Search, and Intelligent Space
TypeSafe AI Releases Jev 1.14 With Images, Box Type and 262k...
TypeSafe AI released Jev 1.14 under the jev-preview alias. The System One model adds experimental image input, a Box bounding-box type and an opt-in 262k-token context, at $0.042 per million input tokens.
Meet Grok Voice 3.0: SpaceXAI Voice Agent Model Ranks #1 on...
SpaceXAI just released Grok Voice 3.0. Grok Voice 3.0 is a SpaceXAI speech-to-speech model that listens, reasons, calls tools and speaks. It now ranks...
Datalab Releases OmniParseBench: An Open OCR Benchmark With 16,288 Pass/Fail Tests...
Datalab released OmniParseBench, an open OCR benchmark with 16,288 yes/no tests on 2,937 pages in 92 languages. Every score is a pass rate you can slice by tag, script or language.
Fish Audio Releases Drama 3, a 35B Open-Weight MoE Text-to-Speech Model
Fish Audio released Drama 3, a 35B mixture-of-experts text-to-speech model with about 3B active parameters. It takes plain-language direction, covers 83 languages and ships open weights under a revenue-capped community license.
9 Best AI Gateways in 2026: Bifrost, Portkey, LiteLLM, Kong and...
Marktechpost ranks the 9 best AI gateways for 2026. We compare Bifrost, Portkey, LiteLLM, Kong, TrueFoundry, Cloudflare, Vercel, OpenRouter and Orq.ai on latency, pricing, licensing, governance and deployment.
Liquid AI Releases LFM2.5-24B-A2B: A 2B-Active MoE for On-Device Agents
Liquid AI released LFM2.5-24B-A2B, an open-weight 24B Mixture-of-Experts reasoning model with 2B active parameters. It targets local agents, scoring 48.09 on LiveClaw and decoding 184 tokens/s on an Apple M5 Max.
Meta Launches Muse Wonder and Muse Wonder Full: Benchmarks, Pricing and...
Meta released Muse Wonder and Muse Wonder Full, 1M-context agent models. Muse Wonder costs $4/$20 per million tokens on Meta Model API. Wonder Full, on Muse Code plans, leads DeepSWE and SWE-Marathon.
How to Use Meta’s Rebalancer for Task Placement & Optimization
In this comprehensive coding tutorial, we explore Meta's Rebalancer assignment solver using its C++ core and Python bindings. Learn how to build datacenters, manage task placements across racks, handle constraints and goal priorities, and compare local search against the exact HiGHS solver using published benchmarks.
Z.ai GLM-Legal Beats Claude Fable 5 and Kimi K3 on Harvey...
Z.ai’s GLM-Legal is a legal AI model built on GLM-5.3-Flash. It scores 19.2% all-pass on Harvey’s Legal Agent Benchmark, nearly 3x its base, at $0.15 per test. Access is by application.
Alibaba Qwen Introduces QwenGyre: Elastic Reinforcement Learning RL for XLong-Horizon Agents
Alibaba's Qwen team has introduced QwenGyre, an elastic reinforcement learning RL framework for extreme-long-horizon agent training. QwenGyre is an online reinforcement learning system from...
Top 12 AI Live Translation Tools in 2026: Latency, Languages, Pricing
We checked 12 AI live translation tools, including Palabra.ai, Google Live Translate, DeepL Voice, Teams Interpreter and Wordly, against official pages for languages, latency, platforms and pricing.
TII Releases Falcon-ASR: 1.6B Arabic Speech Model Hits 20.92% WER
TII has released Falcon-ASR, a 1.6B speech recognition model for Arabic with an Emirati focus. It reports 20.92% average WER on 6 Arabic test sets, but weights and an API are not yet available.
Meet Cloudflare Clef-omni: A 30B-A3B Multimodal Decision Model for Audio, Video,...
Cloudflare released Clef-omni, an Apache-2.0 multimodal decision model built on Qwen3-Omni-30B-A3B. It scores text, images, audio and video in one call for $0.15 per million input tokens, while Clef-flash drops to $0.038.
What is Decision 3.0? vLLM Semantic Router’s New Open Decision Models
vLLM Semantic Router released Decision 3.0, 5 Apache-2.0 multimodal decision models from 0.8B to 27B. They answer choice, yes/no and score questions about text and images in one call, without generating text.
OrcaRouter Releases OrcaCyber Zero 1.5 Cybersecurity Model With 1M Context
OrcaRouter released OrcaCyber Zero 1.5, a gated cybersecurity model with a 1M-token context window. It reports 100% on Cybench and 95.8% on an evaluable CVE-Bench subset, priced at $3.00 / $7.50 per 1M tokens.
Sakana AI’s LLM Peer Review System Catches 73% of Core-Claim Errors
Sakana AI’s TMLR paper introduces Multi-Layered Review, a 3-agent Claude-based reviewer, and a 1,164-error Contradiction Benchmark. MLR caught 73.43% of core-claim errors, versus 14.81% for the best prior system.
Microsoft AI Releases Microsoft-Decision-1: A Qwen3.5-9B Decision-Scoring Model
Microsoft has released Microsoft-Decision-1, a decision model for routing, classification, verification and agent control. Microsoft-Decision-1 is a decision-scoring model that returns a calibrated probability...
Nace AI Open-Sources Drex 1.5: A 9B Decision Model That Scores...
Nace.AI has open-sourced Drex 1.5, a 9B decision model that returns a probability for every option in 1 forward pass. It scores 58.08 on Decision Index 0.3.1 and reads up to 128K tokens.
Alibaba Qwen Releases Qwen-Image-2.1-Turbo, an 8-Step 7B Image Model
Alibaba's Qwen team has released Qwen-Image-2.1-Turbo, an accelerated checkpoint of its open-weight Qwen-Image-2.1 model. It generates and edits images in 8 denoising steps instead...
OpenAI Decisions API Hits Public Beta With 10x Faster Typed Answers
OpenAI’s Decisions API is now in public beta on GPT-6 Luna. It returns typed probabilities, choices and scores about 10x faster than the Responses API, billing $0.10 per 1M input tokens with no output charges.
Meet the Underdog Saluki 27B: A 2-bit Qwen3.8-27B That Beats the...
Underdog Saluki 27B is a 7.89 GB, 2-bit GGUF of Qwen3.8-27B under Apache 2.0. It beats the 54 GB original on tool calling but gives up ground on competition math and reasoning.
Google Cloud Launches Gemini Agent, One Universal Agent for Enterprise Work
Google Cloud has introduced the Google Cloud Gemini agent, a single agent for enterprise work. The Gemini agent is a cloud-hosted agent from Google...
JetBrains Releases Mellum2.1: A 12B MoE Open Model for Coding Agents
JetBrains released Mellum2.1, an Apache 2.0, 12B mixture-of-experts thinking model with 2.5B active parameters. RL in real repositories lifted its SWE-bench Verified score from 2.0 to 47.0.
Architect Launches Liquid Inference, a Real-Time Auction for LLM Inference
Architect Financial Technologies has launched Liquid Inference, an LLM router that runs a live auction for every request. Liquid Inference is an LLM inference...
NVIDIA PivotOPD Teaches Multi-Turn AI Agents to Recover From Pivotal Mistakes
NVIDIA researchers introduced PivotOPD, an on-policy distillation method that trains multi-turn LLM agents to avoid early pivotal mistakes and recover from them, posting the best average against 13 baselines on 3 agent benchmarks.
Perplexity AI Releases pplx-embed-v2-late: A 0.6B Edge Model and a 9B...
Perplexity's pplx-embed-v2-late comes in 2 sizes: a 0.6B model built to run on edge devices, and a 9B model for building high-quality indexes. Its best score is 92.4% on MADQA, and its weakest is 61.2% on ViDoRe v3 Markdown. Both are MIT-licensed and ready to self-host.
What Happens When a Trusted Model Repo Changes? Unsloth Studio Re-Checks...
Unsloth's October 6 security overview explains how Studio checks code, weights, packages and tools before anything runs. Custom model code is scanned and approval is bound to its fingerprint. Flagged weight files are blocked in the load path, package-content findings fail CI, and tools run in probed OS sandboxes. Here is what each checkpoint decides, and what it does not cover.
Anthropic Releases Claude Haiku 5.5: A Small Model With 1M Context...
Anthropic's Claude Haiku 5.5 starts at $0.10 per million input tokens, keeps 1M context, scores 72.4% on OSWorld.
Liquid AI Releases Open-Weight d1-3B and d1-omni-600M: Multimodal Decision Models With...
Liquid AI has released Open d1, two open-weight multimodal models in its d1 decision model family. d1-3B reads text and images. d1-omni-600M reads text...
Meta AI Open-Sources Rebalancer: A C++ Assignment Solver That Runs About...
Meta has open-sourced Rebalancer, the C++ and Python library it has used for over 9 years to place shards, servers and traffic. It handles about 40 million assignment problems a day, using local search or MIP solvers like Gurobi, FICO Xpress and HiGHS. It is pip-installable under Apache 2.0.
A Developer’s Guide to Laya: Zero-Shot Decisions and Calibration
Explore a comprehensive coding guide to Laya, the open-source zero-shot decision engine. Learn how to implement typed decisions, fit custom temperatures, and build reliable abstention gates using real-world CLINC150 banking data.
Google DeepMind Releases EmbeddingGemma 2, a 740M Open Multimodal Embedding Model...
Google DeepMind's EmbeddingGemma 2 maps 5 input types into one 768d space and ships today under Apache 2.0.
Mistral AI Releases Mistral Large 4 (Le Chonk): A 1.05T Parameter...
Mistral AI has released Mistral Large 4, nicknamed Le Chonk, as a public preview. It is a 1.05 trillion parameter Mixture of Experts model with 49 billion active parameters, native image input, and a 1 million token context window, trained on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's own European datacenters. The API is live now; open weights ship end of October 2026.
Reka Releases Rho-1: A 19B Omni-Reasoning Model That Understands, Generates Video...
Reka has released Rho-1, a 19B omni-reasoning model trained from scratch. One network reads and generates text, images, video and robot actions over a shared KV cache. A distilled variant returns a 5.3-second clip in about a second. It is a research preview with no public weights yet.
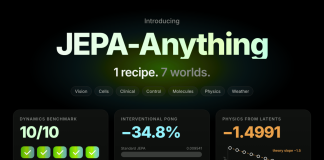
Beyond Domain-Specific World Models: JEPA-Anything Uses 1 Recipe for 7 Fields
JEPA-Anything splits a JEPA's single latent target into 4 orthogonal factors, each with its own predictor. Tested across 7 domains, it beat matched JEPA baselines on all 10 dynamics tasks and cut Interventional Pong intervention error by 34.8%.
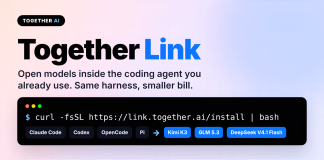
Meet Together Link: A Free CLI That Runs Open Models Like...
Together AI has released Together Link, a free, MIT-licensed CLI that connects Claude Code, Codex, OpenCode, Pi, and the Claude and ChatGPT desktop apps to open models like Kimi K3 and GLM 5.3. One install command sets it up, and an Auto router picks a model for each session. Together claims savings of over 50%.
Building a Streaming Robotics Learning Pipeline Using NVIDIA Cosmos3-DROID
Discover how to construct an end-to-end streaming robotics learning pipeline using the NVIDIA Cosmos3-DROID dataset without local downloads, leveraging byte-range Parquet reads, behavior cloning, and temporal ensembling.
Reflection AI Introduces Beam: A 501B Open-Weight MoE Model With 23B...
Reflection AI has introduced Beam, its first open-weight model. It is a 501B sparse Mixture-of-Experts model with 23B active parameters, built for coding and agentic work. Reflection says it matches GLM-5.2 on reasoning with 3 to 4x less inference compute. Apache 2.0 weights are due later in October 2026.
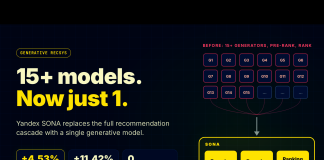
Yandex Introduces Sona: A Single Generative Recommender That Replaces Entire Recommendation...
One transformer ran candidate generation and ranking in Yandex Music's A/B test without hand-engineered features, lifting likes 11.42%.
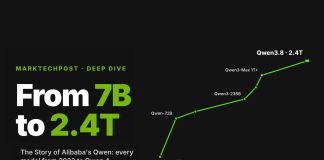
The Story of Qwen: Alibaba’s AI Models From 7B to 2.4T
Alibaba's Qwen went from an invite-only chatbot in April 2023 to a 2.4-trillion-parameter open-weight model in August 2026. This is the full story, release by release: every major model, its key feature, and how its license changed. Each claim links to its source.
Can an Open Model Do Security Research? Cantina’s apex-flash-1 Solves 40...
Cantina Security, with Yeta Labs, has released apex-flash-1, an open-weights model trained specifically for vulnerability research. It is a reinforcement learning fine-tune of Z.ai's...
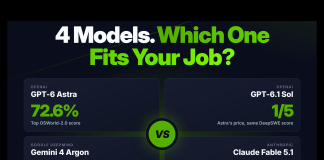
GPT-6 Astra vs GPT-6.1 Sol vs Gemini 4 Argon vs Claude...
Astra leads computer use, Argon leads legal and finance work, and Sol wins on price for coding agents.
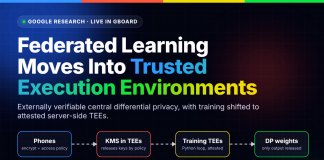
Google Research Moves Federated Learning Into TEEs: Gboard Now Trains With...
Google Research has unveiled a federated learning system that moves gradient computation from phones into attested server-side TEEs. Access policies are published to Sigstore's Rekor log and the binaries are reproducibly buildable, so central differential privacy can be checked externally. Gboard already uses it for English and Japanese next-word prediction.
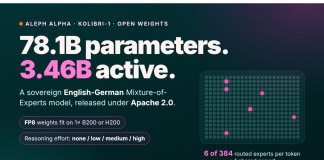
Aleph Alpha Releases Kolibri: A 78.1B Open-Weight English-German MoE Model With...
Aleph Alpha has released Kolibri, a 78.1B-parameter English-German Mixture-of-Experts model that activates only 3.46B parameters per token. It has a 1M-token context and per-request reasoning effort, and its Apache 2.0 FP8 weights run on a single B200 or H200.
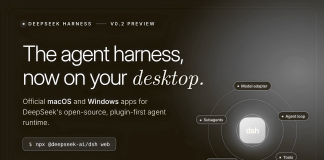
DeepSeek Harness v0.2 Brings Official Desktop Apps to Its Open-Source Agent...
DeepSeek has released official macOS and Windows desktop apps for DeepSeek Harness v0.2, its MIT-licensed agent harness. The preview adds a plugin manager, file and code-change review, and scheduled Automation Tasks. It also supports non-DeepSeek models through OpenAI-compatible endpoints.
Meta, OpenAI and Uber Just Taught AI Agents to Talk First....
TL;DR: Meta's Muse, OpenAI's Dots and Uber's driver assistant share one bet: the agent speaks first. That moves the hard problem from what to...
IBM Brings Bob to Self-Hosted and Air-Gapped Environments: Agentic Software Development...
IBM has made a self-hosted deployment of IBM Bob, its agentic software development platform, generally available. Enterprises can now run Bob on premises, in private or sovereign clouds, and in air-gapped networks. They bring their own model: NVIDIA Nemotron or Poolside Laguna for full isolation, or Claude, Gemini or GPT models through hybrid setups. Optional Premium Packages extend Bob to Java, IBM i and IBM Z modernization.
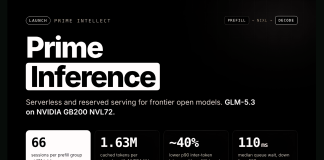
Prime Intellect Launches Prime Inference: Serverless and Reserved Serving for Frontier...
Prime Intellect has launched Prime Inference, an OpenAI-compatible platform for serving frontier open models on NVIDIA Blackwell. Its GLM-5.3 deployment uses Dynamo, vLLM and NVFP4 KV compression to serve 66 sessions per prefill group at 101 tok/s per user.
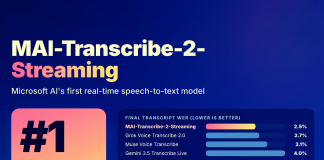
Microsoft AI Releases MAI-Transcribe-2-Streaming: #1 Real-Time Speech-to-Text Model on Artificial Analysis
Microsoft AI has released MAI-Transcribe-2-Streaming, its first real-time speech-to-text model. It ranks #1 of 38 models on Artificial Analysis AA-WER Streaming. It scores 2.5% WER at 0.13s on final transcripts and 2.5% at 0.12s on first partials. It covers 60 languages with continuous language detection and costs $0.54 per hour during the introductory period. It is available now in public preview on Microsoft Foundry.
Decision AI Models Explained: TypeSafe Jev vs Fastino GLiDE, GLiNER2.5-Decide and...
Decision AI models answer typed questions with calibrated probabilities instead of generated text. TypeSafe's Jev costs $0.042 per million input tokens and returns responses in 70 to 500 milliseconds. We break down how it works and its benchmarks, then compare it with Fastino's GLiDE, GLiNER2.5-Decide and 4 open-source rivals.
NVIDIA Announces DGX Spark 64GB: A 1-PetaFLOP Grace Blackwell Desktop for...
NVIDIA announced a new 64GB configuration of DGX Spark — from Acer, ASUS, Dell, Gigabyte, HP and MSI — its GB10-powered desktop AI system....
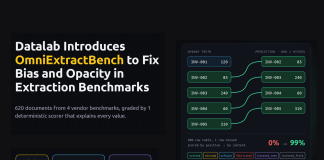
Datalab Introduces OmniExtractBench to Fix Bias and Opacity in Extraction Benchmarks
Content-based row matching, 6 per-value verdicts and a null rule make OmniExtractBench an extraction benchmark anyone can audit.
AWS Strands Labs Releases Strands Decider 2B: An Open Source Decision...
AWS's Strands Agents team released Strands Decider 2B, an Apache-2.0 decision model built on Qwen3.5-2B-Base. It returns choices, yes/no probabilities and scores with calibrated confidence in one forward pass, never text. It runs at a 115 ms median on an RTX 3090 and scores 0.723 on the JevBench public set, which makes it a fast local option for routing, tool selection and guardrails in AI agents.
Cloudflare Releases Clef and Clef-flash: Open-Weight Decision Models That Return Typed...
Cloudflare has released Clef (27B) and Clef-flash (9B), open-weight decision models that return typed probabilities instead of text. They are Jev-API compatible, accept images, and run on Workers AI at 209.3 ms and 38.8 ms median latency.
A Coding Guide to Google Research’s Kauldron: Configs That Are Plain...
In this comprehensive coding guide, we explore Google Research's Kauldron—a JAX training library optimized for research velocity and modularity. Learn how konfig turns experiments into plain dictionaries, kontext wires components via string paths, and ktyping enforces runtime shape checks.
Cohere Releases Embed 5: How It Compares to Voyage 4 Large,...
Cohere has released Embed 5, a new embedding model family. It targets enterprise search, RAG, and agentic retrieval. The model family ships in 2...
NVIDIA Releases Kumo Tabular: Open Tabular Foundation Models That Predict New...
NVIDIA has released Kumo Tabular, a new family of tabular foundation models (TFMs) for classification and regression. If you have followed TabPFN or TabICL,...
Perplexity Releases pplx-embed-v2-context-9b-preview: A Contextual Embedding Model That Retrieves Answers and...
Perplexity Research and turbopuffer have released pplx-embed-v2-context-9b-preview, a contextual embedding model for RAG pipelines. Each chunk is embedded with the full document in view....
Google DeepMind Unveils Gemini 4 Argon with 1M Output Tokens for...
Gemini 4 Argon tops GPT-6 Astra and Claude Opus 5.5 on most benchmarks, but access remains gated today.
OpenAI Releases GPT-6.1 Sol: Near-Astra Coding and Computer Use at One-Fifth...
OpenAI released GPT-6.1 Sol on September 29, 2026, an upgrade to GPT-6 Sol. It reaches near-Astra results on agentic coding, computer use and professional work at one-fifth of Astra's token prices. It costs $2 input and $10 output per million tokens, and cached input drops to $0.10. It is available now through the OpenAI API, ChatGPT Work and Codex.
Perplexity Introduces Photon: A Rust-Based Retrieval Engine That Cuts p99 Latency...
Perplexity has released Photon, an in-house retrieval and ranking engine written in Rust. It replaces an open-source engine Perplexity had forked for its AI-native...
NVIDIA Researchers Introduce Physis-Lang: Self-Evolving Physical Language That Lifts Cosmos 3...
Video world models can render convincing clips that still break physics. Butter spreads like paint. Balls pass through walls. A team from NVIDIA, MIT...