
Sound
Breaking News

Tencent AI Open Sources Covo-Audio: A 7B Speech Language Model and...
Tencent AI Lab has released Covo-Audio, a 7B-parameter end-to-end Large Audio Language Model (LALM). The model is designed to unify speech processing and language...
Google AI Releases WAXAL: A Multilingual African Speech Dataset for Training...
Speech technology still has a data distribution problem. Automatic Speech Recognition (ASR) and Text-to-Speech (TTS) systems have improved rapidly for high-resource languages, but many...
Fish Audio Releases Fish Audio S2: A New Generation of Expressive...
The landscape of Text-to-Speech (TTS) is moving away from modular pipelines toward integrated Large Audio Models (LAMs). Fish Audio’s release of S2-Pro, the flagship...

Qwen Researchers Release Qwen3-TTS: an Open Multilingual TTS Suite with Real-Time...
Alibaba Cloud’s Qwen team has open-sourced Qwen3-TTS, a family of multilingual text-to-speech models that target three core tasks in one stack, voice clone, voice...

Microsoft Releases VibeVoice-ASR: A Unified Speech-to-Text Model Designed to Handle 60-Minute...
Microsoft has released VibeVoice-ASR as part of the VibeVoice family of open source frontier voice AI models. VibeVoice-ASR is described as a unified speech-to-text...

FlashLabs Researchers Release Chroma 1.0: A 4B Real Time Speech Dialogue...
Chroma 1.0 is a real time speech to speech dialogue model that takes audio as input and returns audio as output while preserving the...

Inworld AI Releases TTS-1.5 For Realtime, Production Grade Voice Agents
Inworld AI has introduced Inworld TTS-1.5, an upgrade to its TTS-1 family that targets realtime voice agents with strict constraints on latency, quality, and...

How to Design a Fully Streaming Voice Agent with End-to-End Latency...
In this tutorial, we build an end-to-end streaming voice agent that mirrors how modern low-latency conversational systems operate in real time. We simulate the...

NVIDIA Releases PersonaPlex-7B-v1: A Real-Time Speech-to-Speech Model Designed for Natural and...
NVIDIA Researchers released PersonaPlex-7B-v1, a full duplex speech to speech conversational model that targets natural voice interactions with precise persona control.
From ASR→LLM→TTS to a...
Google Researchers Release Magenta RealTime: An Open-Weight Model for Real-Time AI...
Google's Magenta team has introduced Magenta RealTime (Magenta RT), an open-weight, real-time music generation model that brings unprecedented interactivity to generative audio. Licensed under...

Omni-R1: Advancing Audio Question Answering with Text-Driven Reinforcement Learning and Auto-Generated...
Recent developments have shown that RL can significantly enhance the reasoning abilities of LLMs. Building on this progress, the study aims to improve Audio...
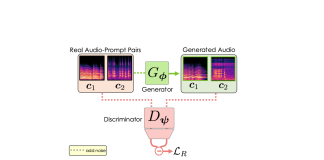
Stability AI Introduces Adversarial Relativistic-Contrastive (ARC) Post-Training and Stable Audio Open...
Text-to-audio generation has emerged as a transformative approach for synthesizing sound directly from textual prompts, offering practical use in music production, gaming, and virtual...
Rime Introduces Arcana and Rimecaster (Open Source): Practical Voice AI Tools...
The field of Voice AI is evolving toward more representative and adaptable systems. While many existing models have been trained on carefully curated, studio-recorded...
NVIDIA AI Introduces Audio-SDS: A Unified Diffusion-Based Framework for Prompt-Guided Audio...
Audio diffusion models have achieved high-quality speech, music, and Foley sound synthesis, yet they predominantly excel at sample generation rather than parameter optimization. Tasks...

The WAVLab Team Releases of VERSA: A Comprehensive and Versatile Evaluation Toolkit...
AI models have made remarkable strides in generating speech, music, and other forms of audio content, expanding possibilities across communication, entertainment, and human-computer interaction....

Transforming Speech Generation: How the Emilia Dataset Revolutionizes Multilingual Natural Voice...
Speech generation technology has advanced considerably in recent years, yet there remain significant challenges. Traditional text-to-speech systems often rely on datasets derived from audiobooks....

Google AI Introduces ZeroBAS: A Neural Method to Synthesize Binaural Audio...
Humans possess an extraordinary ability to localize sound sources and interpret their environment using auditory cues, a phenomenon termed spatial hearing. This capability enables...

Redefining Single-Channel Speech Enhancement: The xLSTM-SENet Approach
Speech processing systems often struggle to deliver clear audio in noisy environments. This challenge impacts applications such as hearing aids, automatic speech recognition (ASR),...

This AI Paper from NVIDIA and SUTD Singapore Introduces TANGOFLUX and...
Text-to-audio generation has transformed how audio content is created, automating processes that traditionally required significant expertise and time. This technology enables the conversion of...

Alibaba AI Research Releases CosyVoice 2: An Improved Streaming Speech Synthesis...
Speech synthesis technology has made notable strides, yet challenges remain in delivering real-time, natural-sounding audio. Common obstacles include latency, pronunciation accuracy, and speaker consistency—issues...

This AI Paper Introduces BEST-STD (Spoken Term Detection): A Novel Bidirectional...
Spoken term detection (STD) is a critical area in speech processing, enabling the identification of specific phrases or terms in large audio archives. This...

NVIDIA AI Unveils Fugatto: A 2.5 Billion Parameter Audio Model that...
Creating, editing, and transforming music and sounds present both technical and creative challenges. Current AI models often struggle with versatility, specializing in narrow tasks...

MOS-Bench: A Comprehensive Collection of Datasets for Training and Evaluating Subjective...
A critical challenge in Subjective Speech Quality Assessment (SSQA) is enabling models to generalize across diverse and unseen speech domains. General SSQA models evaluate...
Multi-Scale Neural Audio Codec (SNAC): An Wxtension of Residual Vector Quantization...
Neural audio compression has emerged as a critical challenge in digital signal processing, particularly in achieving efficient audio representation while preserving quality. Traditional audio...
Researchers from UCSD and Adobe Introduce Presto!: An AI Approach to...
Text-to-Audio (TTA) and Text-to-Music (TTM) generation have seen significant advancements in recent years, driven by audio-domain diffusion models. These models have demonstrated superior audio...
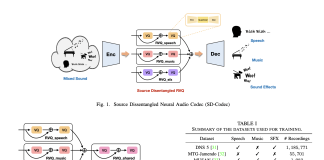
Source-Disentangled Neural Audio Codec (SD-Codec): A Novel AI Approach that Combines...
Neural audio codecs have completely changed how audio is compressed and handled, by converting continuous audio signals into discrete tokens. This technique uses generative...
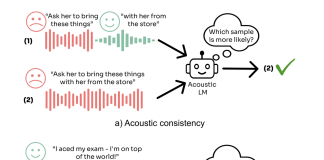
How Well Can AI Models Capture the Sound of Emotion? This...
A major challenge in the field of Speech-Language Models (SLMs) is the lack of comprehensive evaluation metrics that go beyond basic textual content modeling....
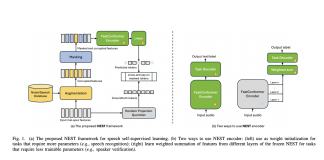
This AI Paper by NVIDIA Introduces NEST: A Fast and Efficient...
Speech processing focuses on developing systems to analyze, interpret, and generate human speech. These technologies encompass a range of applications, such as automatic speech...
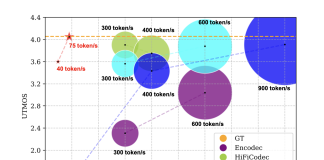
WavTokenizer: A Breakthrough Acoustic Codec Model Redefining Audio Compression
Large-scale language models have made significant progress in generative tasks involving multiple-speaker speech synthesis, music generation, and audio generation. The integration of speech modality...
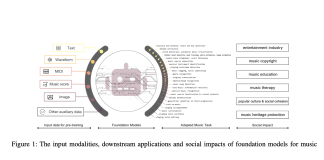
This AI Paper Introduces MARBLE: A Comprehensive Benchmark for Music Information...
Music information retrieval (MIR) has become increasingly vital as the digitalization of music has exploded. MIR involves the development of algorithms that can analyze...
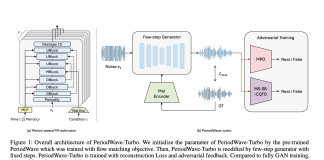
Breaking Barriers in Audio Quality: Introducing PeriodWave-Turbo for Efficient Waveform Synthesis
Achieving high-fidelity waveform generation in audio synthesis is a significant challenge, particularly due to the slow inference times associated with traditional models like Conditional...
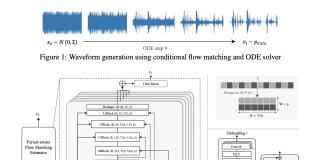
PeriodWave: A Novel Universal Waveform Generation Model
High-fidelity waveform generation, particularly in text-to-speech (TTS) and audio generation applications, involves several critical challenges. Accurately generating natural-sounding audio remains a primary issue, essential...
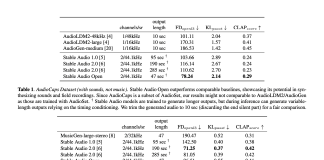
Stability AI Open-Sources Stable Audio Open: An Audio Generation Model with...
In the field of Artificial Intelligence, open, generative models stand out as a cornerstone for progress. These models are vital for advancing research and...
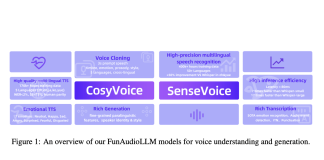
FunAudioLLM: A Multi-Model Framework for Natural, Multilingual, and Emotionally Expressive Voice...
Voice interaction technology has significantly evolved with the advancements in artificial intelligence (AI). The field focuses on enhancing natural communication between humans and machines,...
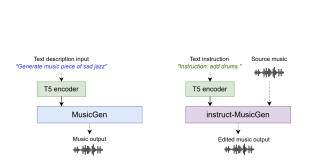
Instruct-MusicGen: A Novel Artificial Intelligence AI Approach to Text-to-Music Editing that...
Researchers from C4DM, Queen Mary University of London, Sony AI, and Music X Lab, MBZUAI, have introduced Instruct-MusicGen to address the challenge of text-to-music...
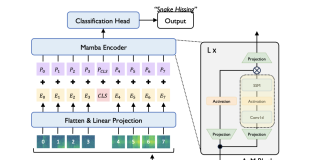
Taming Long Audio Sequences: Audio Mamba Achieves Transformer-Level Performance Without Self-Attention
Audio classification has evolved significantly with the adoption of deep learning models. Initially dominated by Convolutional Neural Networks (CNNs), this field has shifted towards...
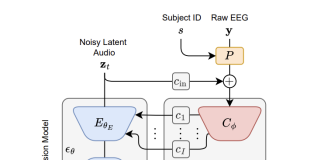
This AI Paper Discusses How Latent Diffusion Models Improve Music Decoding...
Brain-computer interfaces (BCIs) focus on creating direct communication pathways between the brain and external devices. This technology has applications in medical, entertainment, and communication...
MuPT: A Series of Pre-Trained AI Models for Symbolic Music Generation...
In the ever-expanding landscape of artificial intelligence, Large Language Models (LLMs) have emerged as versatile tools, making significant strides across various domains. As they...
Tango 2: The New Frontier in Text-to-Audio Synthesis and Its Superior...
With the introduction of some brilliant generative Artificial intelligence models, such as ChatGPT, GEMINI, and BARD, the demand for AI-generated content is rising in...
Researchers at Tsinghua University Propose SPMamba: A Novel AI Architecture Rooted...
Navigating through the intricate landscape of speech separation, researchers have continually sought to refine the clarity and intelligibility of audio in bustling environments. This...
This AI Paper from China Introduces ChatMusician: An Open-Source LLM that...
The intersection of AI and the arts, especially music, has become an important field of study due to its deep implications for human creativity....
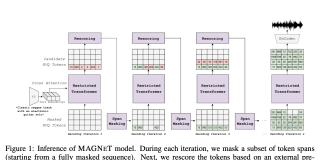
Meta AI Introduces MAGNET: The First Pure Non-Autoregressive Method for Text-Conditioned...
Recent advancements in self-supervised representation learning, sequence modeling, and audio synthesis have significantly enhanced the performance of conditional audio generation. The prevailing approach involves...
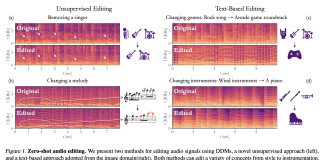
Technion Researchers Revolutionize Audio Editing: Unleashing Creativity with Zero-Shot Techniques and...
Advancements in creative media generation, with audio editing at the forefront of this technological renaissance. The innovative use of Large Language Models (LLMs) for...
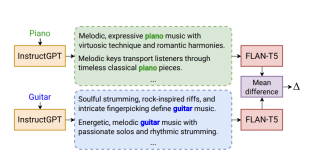
MusicMagus: Harnessing Diffusion Models for Zero-Shot Text-to-Music Editing
Music generation has long been a fascinating domain, blending creativity with technology to produce compositions that resonate with human emotions. The process involves generating...
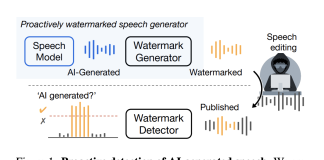
Meta AI Introduces AudioSeal: The First Audio Watermarking Technique Designed Specifically...
In the past decade or so, Artificial Intelligence (AI) has made significant strides and is now part of automation pipelines in various applications. New...
Experience the Magic of Stable Audio by Stability AI: Where Text...
In the rapidly evolving field of audio synthesis, a new frontier has been crossed with the development of Stable Audio, a state-of-the-art generative model....
Enhanced Audio Generation through Scalable Technology
Technological advancements have been pivotal in transcending the boundaries of what's achievable in the domain of audio generation, especially in high-fidelity audio synthesis. As...
This AI Paper from Apple Proposes Acoustic Model Fusion to Drastically...
Significant improvements have been made in enhancing the accuracy and efficiency of Automatic Speech Recognition (ASR) systems. The recent research delves into integrating an...
Meet DiffMoog: A Differentiable Modular Synthesizer with a Comprehensive Set of...
Synthesizers, electronic instruments producing diverse sounds, are integral to music genres. Traditional sound design involves intricate parameter adjustments, demanding expertise. Neural networks aid by...
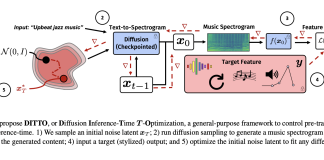
This AI Paper from Adobe and UCSD Presents DITTO: A General-Purpose...
A key challenge in text-to-music generation using diffusion models is controlling pre-trained text-to-music diffusion models at inference time. While effective, these models can only...
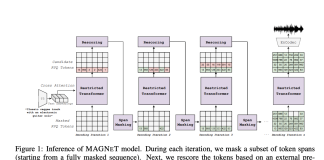
MAGNeT: A Masked Generative Sequence AI Modeling Method that Operates Directly...
In audio technology, researchers have made significant strides in developing models for audio generation. However, the challenge lies in creating models that can efficiently...
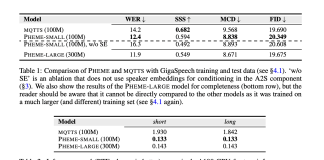
Meet PHEME: PolyAI’s Advanced Transformer-Based TTS System for Efficient and Conversational...
In recent years, there has been remarkable progress in speech generation, achieving one-shot generation capability virtually indistinguishable from real human voice. The demand for...
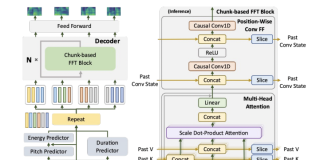
This AI Paper from NVIDIA Unveils ‘Incremental FastPitch’: Revolutionizing Real-Time Speech...
Parallel Text-to-Speech (TTS) models are commonly used for on-the-fly speech synthesis, providing enhanced control and faster synthesis than traditional auto-regressive models. Despite their advantages,...
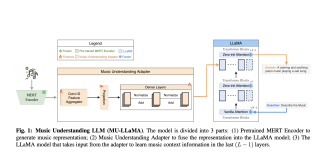
Can a Single Model Revolutionize Music Understanding and Generation? This Paper...
The necessity for large-scale music datasets with natural language captions is a difficulty for text-to-music production, which this research addresses. Although closed-source captioned datasets...
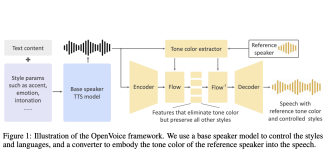
MyShell Open-Sources OpenVoice: An Instant Voice Cloning AI Library that Takes...
There are two challenges in voice cloning: 1) Flexible Voice Style Control- Many Instant Voice Cloning (IVC) approaches cannot manipulate voice styles after cloning...
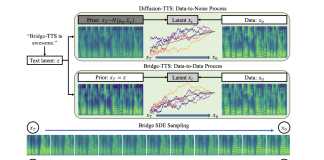
How Do Schrodinger Bridges Beat Diffusion Models On Text-To-Speech (TTS) Synthesis?
With the growing number of advancements in Artificial Intelligence, the fields of Natural Language Processing, Natural Language Generation, and Computer Vision have gained massive...
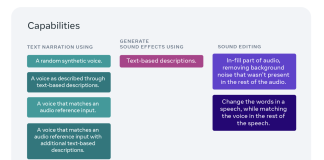
Meet Audiobox: A New Meta AI’s Foundation Research Model for Audio...
Audio plays an important role in the field of media and entertainment. It influences everything from movies and podcasts to audiobooks and video games....
Google AI Proposes Easy End-to-End Diffusion-based Text to Speech E3-TTS: A...
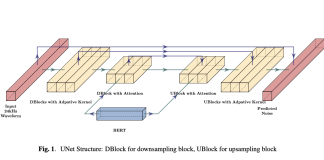
In machine learning, a diffusion model is a generative model commonly used for image and audio generation tasks. The diffusion model uses a diffusion...
Can One AI Model Master All Audio Tasks? Meet UniAudio: A...
A key aspect of generative AI is audio generation. In recent years, the popularity of generative AI has led to increasingly diverse and emerging...
Meet AudioSR: A Plug & Play and One-for-All AI Solution for...
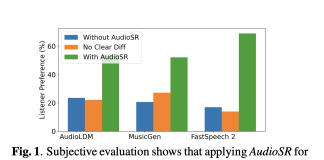
A key challenge in the field of digital audio processing is audio super-resolution. It aims to enhance the quality of audio signals by anticipating...
Microsoft Researchers Unveil PromptTTS 2: Revolutionizing Text-to-Speech with Enhanced Voice Variability...
The intelligibility and naturalness of synthesized speech have improved due to recent developments in text-to-speech systems. Large-scale TTS systems have been created for multi-speaker...
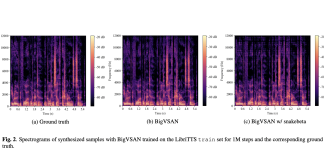
Researchers from Sony Propose BigVSAN: Revolutionizing Audio Quality with Slicing Adversarial...
The development of neural networks and their constantly increasing popularity have led to substantial improvements in speech synthesis technologies. The majority of speech synthesis...
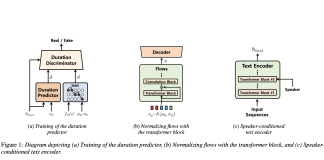
Researchers from South Korea Propose VITS2: A Breakthrough in Single-Stage Text-to-Speech...
The paper introduces VITS2, a single-stage text-to-speech model that synthesizes more natural speech by improving various aspects of previous models. The model addresses issues...
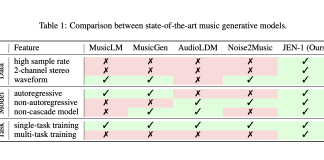
Meet JEN-1: A Universal AI Framework that Combines Bi-Directional and Uni-Directional...
Music, often hailed as the universal language of humanity by Henry Wadsworth Longfellow, carries within it the essence of harmony, melody, and rhythm, weaving...
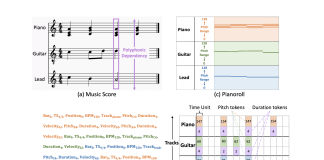
Meet GETMusic: A Unified Representation and Diffusion Framework that can Generate...
In recent years, Significant progress has been made in music generation using Machine Learning models. However, there are still challenges in achieving efficiency and...
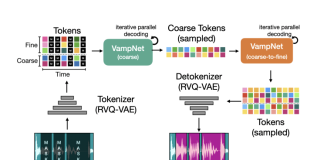
Meet VampNet: A Masked Acoustic Token Modeling Approach to Music Synthesis,...
Significant improvements in the autoregressive creation of speech and music have recently been made due to discrete acoustic token modeling developments. For effective picture...
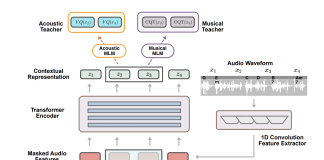
This AI Paper Proposes A Self-Supervised Music Understanding Model Called MERT...
Self-supervised learning is being prominently used in Artificial Intelligence to develop intelligent systems. The transformer models like BERT and T5 have recently got popular...