
Embedding Model
Breaking News
A Developer’s Guide to OmniParseBench: Leaderboard Benchmarks and OCR Testing
Explore how to audit and rebuild Datalab's OmniParseBench, test parser ranking certainty with document-level bootstrapping, and evaluate Tesseract and Indra OCR performance on a custom sample.
NVIDIA Open Sources Run:ai Under Apache 2.0 for Kubernetes GPU Orchestration
NVIDIA has released the full Run:ai GPU orchestration platform as open source under Apache 2.0. The release includes KAI Scheduler, CUDA 13.4 GPU fractioning, quota management, and a local Kind dev environment.
Meet Kyutai REKI: The 2.4B VLA Model Bringing Efficient Memory to...
Kyutai, with Inria and École des Ponts, has released REKI, a 2.4B vision-language-action model (VLA) for robot manipulation. The REKI vision-language-action model is pretrained...
Datalab Releases OmniParseBench: An Open OCR Benchmark With 16,288 Pass/Fail Tests...
Datalab released OmniParseBench, an open OCR benchmark with 16,288 yes/no tests on 2,937 pages in 92 languages. Every score is a pass rate you can slice by tag, script or language.
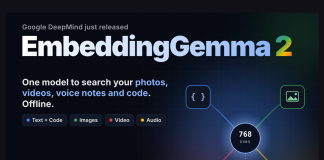
Google DeepMind Releases EmbeddingGemma 2, a 740M Open Multimodal Embedding Model...
Google DeepMind's EmbeddingGemma 2 maps 5 input types into one 768d space and ships today under Apache 2.0.
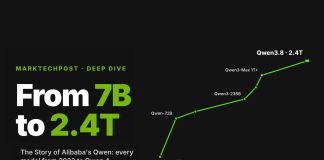
The Story of Qwen: Alibaba’s AI Models From 7B to 2.4T
Alibaba's Qwen went from an invite-only chatbot in April 2023 to a 2.4-trillion-parameter open-weight model in August 2026. This is the full story, release by release: every major model, its key feature, and how its license changed. Each claim links to its source.
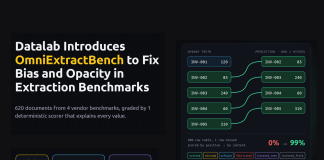
Datalab Introduces OmniExtractBench to Fix Bias and Opacity in Extraction Benchmarks
Content-based row matching, 6 per-value verdicts and a null rule make OmniExtractBench an extraction benchmark anyone can audit.
AWS Strands Labs Releases Strands Decider 2B: An Open Source Decision...
AWS's Strands Agents team released Strands Decider 2B, an Apache-2.0 decision model built on Qwen3.5-2B-Base. It returns choices, yes/no probabilities and scores with calibrated confidence in one forward pass, never text. It runs at a 115 ms median on an RTX 3090 and scores 0.723 on the JevBench public set, which makes it a fast local option for routing, tool selection and guardrails in AI agents.
Cloudflare Releases Clef and Clef-flash: Open-Weight Decision Models That Return Typed...
Cloudflare has released Clef (27B) and Clef-flash (9B), open-weight decision models that return typed probabilities instead of text. They are Jev-API compatible, accept images, and run on Workers AI at 209.3 ms and 38.8 ms median latency.
Cohere Releases Embed 5: How It Compares to Voyage 4 Large,...
Cohere has released Embed 5, a new embedding model family. It targets enterprise search, RAG, and agentic retrieval. The model family ships in 2...
Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes
Nebius and NVIDIA are running the 2026 Physical AI Awards for startups with products in the field. Five category winners each get $150,000 in compute credits, joint promotion, executive mentorship, and seats at an executive dinner. Applications close October 25.
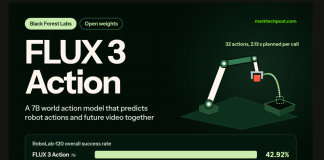
Black Forest Labs Releases FLUX 3 Action: A 7B Open-Weights World...
Black Forest Labs (BFL), the lab behind the FLUX image models, has released FLUX 3 Action. It is a 7B open-weights World Action Model...
Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model
Linkup Research has released SPARSEUP, an open-source sparse embedding model built on a 149M-parameter ModernBERT backbone. It scores 56.4 nDCG@10 on BEIR-13, which Linkup calls the best result it knows of for a public sparse encoder under 150M parameters. The model uses a logit shift, top-12 expansion per token and case folding to keep its vectors sparse. With the Seismic index, it reaches over 97% recall in about 380 microseconds per query, and it ships under Apache 2.0.

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts...
We look at r-1, the document parsing model Reducto released on September 1, 2026. We walk through how it folds OCR, layout detection, tables, formatting and grounding into one full page pass, replacing the multi stage agentic pipeline it ships alongside. We break down the two numbers that matter for a migration decision: a reported 20% error reduction and a flat 1 cent per page rate against the legacy 3 to 6 cents.
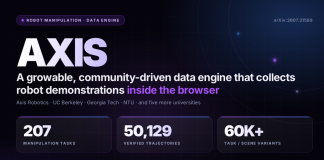
Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot...
Robot datasets have grown far slower than the models trained on them, mostly because collection stays locked to lab hardware. AXIS moves demonstration collection into a web browser and pushes everything expensive to backend GPUs. The result is 207 tasks and 50,129 verified Franka trajectories, and continual pretraining that lifts π0.5 from 83.9 to 88.8 on LIBERO-Plus while a volume-matched RoboCasa365 control reaches only 57.5.
Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That...
Cohere has released Parse (parse-v5.0), a 2.3B-parameter vision language model that converts PDFs, slides and images into Markdown with HTML tables, bounding boxes and image descriptions. It runs at $1.50 per 1,000 pages through the API, or on dedicated Model Vault instances from $2,500 a month. Cohere reports a ParseBench score of 79.2, ahead of Mistral OCR 4, Azure Document Intelligence and Databricks AI Parse — but that figure averages three of the benchmark's five dimensions and drops charts and visual grounding entirely.

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks...
Harvey's first post-trained model nearly doubles LAB task completion, but only one benchmark number survives independent verification today

Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million...
Dyna Robotics has released Dyna-2, a world-action model pre-trained on more than one million hours of egocentric human video. The technical report establishes three results: a scaling law on human data to 1M hours, the first transfer of that law to unseen robot data, and evidence that video co-training drives cross-embodiment generalization.

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with...
NVIDIA's open 30B MoE targets the agent execution layer, with Switchyard routing each step to the cheapest capable model.
NVIDIA Releases Alpamayo 2 Super: A 34B Open Vision-Language-Action Model for...
NVIDIA released Alpamayo 2 Super, a 34B vision-language-action model for autonomous driving, under OpenMDW-1.1 — a permissive license covering fine-tuning, derivatives and commercial redistribution. It pairs a 32B Cosmos 3 Super Reasoner backbone with a 2.3B diffusion action decoder, scores 79.2 on LingoQA, and emits trajectories, Chain-of-Causation traces, meta-actions, auto-labels and grounded VQA from a single pass.
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG...
Marktechpost AI has released Token Saver, an open-source MCP extension for Claude Desktop that uses local Hybrid RAG to slash PDF token consumption by up to 99% while ensuring absolute document privacy.

Meet Open Dreamer: A JAX/Flax Reproduction of the Dreamer 4 World...
A small group of AI researchers (Francesco Sacco, Diego Martí, and Edward Hu) have released Open Dreamer, an open implementation of the Dreamer 4...

Best Local LLMs You Can Run on a Single 24GB GPU...
A single 24GB GPU is the practical floor for serious local inference. This guide compares six open-weight models that fit one card at Q4_K_M. It covers Qwen3.6, Gemma 4, Mistral Small, gpt-oss-20b, and DeepSeek-R1-Distill. Each entry lists VRAM fit, licensing, and the job it does best.
NVIDIA AI Releases Nemotron 3 Embed: An Open Embedding Collection Whose...
NVIDIA released Nemotron 3 Embed on July 15 and 16, 2026. The collection has three open checkpoints: Nemotron-3-Embed-8B-BF16, Nemotron-3-Embed-1B-BF16, and Nemotron-3-Embed-1B-NVFP4. The 8B ranks #1 on RTEB at 78.46 average NDCG@10. The 1B came from ModelOpt NAS pruning plus COS+MSE distillation from the 8B teacher. NVFP4 retains 99%+ of BF16 retrieval accuracy at up to 2x Blackwell throughput. All three run 32,768-token inputs under OpenMDW-1.1.
Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for...
Ant Group's Robbyant has released LingBot-VLA 2.0, an Apache-2.0 vision-language-action model for cross-embodiment robot manipulation. The 6B checkpoint is pretrained on roughly 60,000 hours of data, spanning 50,000 hours of robot trajectories across 20 robot configurations and 10,000 hours of egocentric human video. It maps every embodiment into a single 55-dimensional canonical action space, covering arms, dexterous hands, waists, heads, and mobile bases. A token-level, auxiliary-loss-free Mixture-of-Experts action expert scales capacity without adding a load-balancing loss. Dual-query distillation from LingBot-Depth and DINO-Video adds geometric and temporal supervision for future-aware control. On the GM-100 generalist benchmark it outperforms π0.5 and LingBot-VLA-1.0 on both evaluated platforms.

Liquid AI Introduces LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M: Dense Bi-Encoder and Late-Interaction Models...
Liquid AI's LFM2.5 Retrievers combine a dense bi-encoder and ColBERT late-interaction model for multilingual search on edge devices.
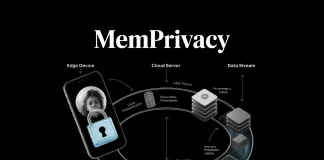
Meet MemPrivacy: An Edge-Cloud Framework that Uses Local Reversible Pseudonymization to...
As LLM-powered agents move from research to production, one design tension is becoming harder to ignore: the more useful cloud-hosted memory becomes, the more...
IBM Releases Granite 4.0 3B Vision: A New Vision Language Model...
IBM has announced the release of Granite 4.0 3B Vision, a vision-language model (VLM) engineered specifically for enterprise-grade document data extraction. Departing from the...

Microsoft AI Releases Harrier-OSS-v1: A New Family of Multilingual Embedding Models...
Microsoft has announced the release of Harrier-OSS-v1, a family of three multilingual text embedding models designed to provide high-quality semantic representations across a wide...

Google AI Introduces Gemini Embedding 2: A Multimodal Embedding Model that...
Google expanded its Gemini model family with the release of Gemini Embedding 2. This second-generation model succeeds the text-only gemini-embedding-001 and is designed specifically...

Liquid AI’s New LFM2-24B-A2B Hybrid Architecture Blends Attention with Convolutions to...
The generative AI race has long been a game of 'bigger is better.' But as the industry hits the limits of power consumption and...

IBM AI Research Releases Two English Granite Embedding Models, Both Based...
IBM has quietly built a strong presence in the open-source AI ecosystem, and its latest release shows why it shouldn’t be overlooked. The company...

Building a Context-Aware Multi-Agent AI System Using Nomic Embeddings and Gemini...
In this tutorial, we walk through the complete implementation of an advanced AI agent system powered by Nomic Embeddings and Google's Gemini. We design...

Nomic Open Sources State-of-the-Art Multimodal Embedding Model
Nomic has announced the release of "Nomic Embed Multimodal," a groundbreaking embedding model that achieves state-of-the-art performance on visual document retrieval tasks. The new...