
Dataset
Breaking News

Google DeepMind Releases AlphaGenome Atlas With Precomputed Molecular Effect Predictions and...
DeepMind's AlphaGenome Atlas maps every single-letter change in the human genome with 1 impact score per variant.
Adaption Labs Introduces ‘Invent a Dataset’: Training Data Generated From a...
Adaption Labs has released Invent a Dataset, which generates a structured, training-ready dataset from a description of the behavior you want a model to learn. There is no seed corpus, no schema design, and no labeling guide. A single datasets.invent call sets domains, row count, output format, and language expansion, and the rows download as JSONL, JSON, CSV, or Parquet. The dataset ID then passes straight into AutoScientist, closing an intent-to-trained-model loop.

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the...
Feyn Labs has released SQRL, a family of text-to-SQL models that inspect a database with read-only probes before committing to a query. The flagship SQRL-35B-A3B reports 70.6% execution accuracy on BIRD Dev, edging Claude Opus 4.6, and distills into self-hostable 4B and 9B checkpoints.

A Coding Hands-On on FineWeb for Streaming, Filtering, Deduplication, Tokenization, and...
In this tutorial, we explore the FineWeb dataset through an advanced hands-on workflow. We stream a manageable sample of the dataset without downloading the...
A Coding Implementation on Spatial Graph Neural Networks for Urban Function...
We build an end-to-end spatial graph learning pipeline using city2graph. We collect urban POI and street network data from OpenStreetMap, with a synthetic fallback for reliability. We engineer spatial features, construct several proximity graph families, and compare how each represents the same urban environment. We then build heterogeneous and homogeneous graphs, convert them to PyTorch Geometric, and train a GraphSAGE model to predict POI categories from spatial structure.

How to Build an Advanced, Interactive Exploratory Data Analysis Workflow Using...
In this tutorial, we demonstrate how to move beyond static, code-heavy charts and build a genuinely interactive exploratory data analysis workflow directly using PyGWalker....

Alibaba Open-Sources Zvec: An Embedded Vector Database Bringing SQLite-like Simplicity and...
Alibaba Tongyi Lab research team released 'Zvec', an open source, in-process vector database that targets edge and on-device retrieval workloads. It is positioned as...

Google Colab Integrates KaggleHub for One Click Access to Kaggle Datasets,...
Google is closing an old gap between Kaggle and Colab. Colab now has a built in Data Explorer that lets you search Kaggle datasets,...
Hugging Face Open-Sourced FineVision: A New Multimodal Dataset with 24 Million Samples...
Hugging Face has just released FineVision, an open multimodal dataset designed to set a new standard for Vision-Language Models (VLMs). With 17.3 million images,...

UC San Diego Researchers Introduced Dex1B: A Billion-Scale Dataset for Dexterous...
Challenges in Dexterous Hand Manipulation Data Collection
Creating large-scale data for dexterous hand manipulation remains a major challenge in robotics. Although hands offer greater flexibility...

Prime Intellect Releases SYNTHETIC-1: An Open-Source Dataset Consisting of 1.4M Curated...
In artificial intelligence and machine learning, high-quality datasets play a crucial role in developing accurate and reliable models. However, collecting extensive, verified data—particularly in...

Meet FineFineWeb: An Open-Sourced Automatic Classification System for Fine-Grained Web Data
Multimodal Art Projection (M-A-P) researchers have introduced FineFineWeb, a large open-source automatic classification system for fine-grained web data. The project decomposes the deduplicated Fineweb...
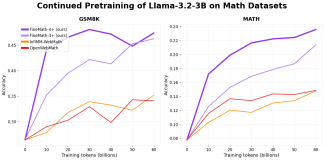
Hugging Face Releases FineMath: The Ultimate Open Math Pre-Training Dataset with...
For education research, access to high-quality educational resources is critical for learners and educators. Often perceived as one of the most challenging subjects, mathematics...

CloudFerro and ESA Φ-lab Launch the First Global Embeddings Dataset for...
CloudFerro and European Space Agency (ESA) Φ-lab have introduced the first global embeddings dataset for Earth observations, a significant development in geospatial data analysis....

Researchers at Stanford Introduce UniTox: A Unified Dataset of 2,418 FDA-Approved...
Drug-induced toxicity is a major challenge in drug development, contributing significantly to the failure of clinical trials. While efficacy issues account for most failures,...

VisOnlyQA: A New Dataset for Evaluating the Visual Perception of LVLMs...
Large Vision Language Models (LVLMs) have demonstrated significant advancements across various challenging multi-modal tasks over the past few years. Their ability to interpret visual...

Hugging Face Releases FineWeb2: 8TB of Compressed Text Data with Almost...
The field of natural language processing (NLP) has grown rapidly in recent years, creating a pressing need for better datasets to train large language...