
Technology
Breaking News

Edge0 Releases Audio8-TTS-Realistic, a 0.6B Voice Cloning TTS Model
Edge0 released Audio8-TTS-Realistic, a 0.6B open-weight zero-shot voice cloning TTS model under Apache 2.0. It supports 23 languages and adds a final GRPO stage driven by a learned realism critic.

Baseten Releases joey-1, a 2B Decision Model at $0.01 per 1M...
Baseten has released joey-1, a 2B open-weight decision model that returns calibrated probabilities instead of text. It runs at 20 ms P50 latency and costs $0.01 per million input tokens.

Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x...
Prime Intellect released Prime Mega MoE, a backward pass for DeepSeek’s fused Mega MoE kernel. It makes the kernel trainable and speeds Qwen3 MoE training steps by up to 34% in prime-rl.

Infini-AI-Lab Releases Hermit, an Open-Source Harness Adapter Framework for AI Agents
Infini-AI-Lab released Hermit, an Apache-2.0 harness adapter framework that trains an external layer of instructions, skills, memory and tools from task feedback, leaving the agent’s model and harness unchanged.

Block Unveils Dessa, a Full-Duplex Speech Model Trained Only on Speech
Block’s AI lab released Dessa, a full-duplex speech-to-speech model trained only on human conversation audio. It runs locally on a MacBook Pro M4 Max, but Block has published no size, benchmarks or weights.

AssemblyAI Ships AssemblyAI-TTS-1: A $15 per 1M Character Text-to-Speech API for...
AssemblyAI has released AssemblyAI-TTS-1, its first text-to-speech model for voice agents. It costs $15 per 1M characters, offers unlimited concurrency without a contract, and supports 6 languages at launch.

NVIDIA Releases Nemotron 3.5 Transcribe: An Open 30B MoE Model for...
NVIDIA released Nemotron 3.5 Transcribe, an open-weights speech LLM with 4.3B active parameters. It transcribes 40 languages, adds speaker labels and word timestamps, and posts a 4.71% mean WER on the English Open ASR Leaderboard.

Google DeepMind Introduces Gemini 4 Carbon, Its Top Model for Cyber...
Google DeepMind introduced Gemini 4 Carbon, a frontier model that scores 59 on the Artificial Analysis Intelligence Index and 88.2% on SEC-bench Pro. Access starts with vetted cyber defenders, at $2/$10 per million tokens.

MiniMax Open-Sources MCode Stack: 15 Agent Skills Its Coding Team Uses...
MiniMax has open-sourced MCode Stack, an MIT-licensed repo of 17 SKILL.md skills and 5 checklists that its MiniMax Code team uses daily for code review, subagent splits, context budgets and long-running commands.

Polymathic AI and Princeton Researchers Release FlashMap, a Flow Map Drafter...
FlashMap is a speculative decoding drafter from Polymathic AI, Princeton and USC ISI researchers. It drafts 16 tokens jointly in one pass and reaches up to 6.14x lossless speedup on Qwen3-8B.

Meet Google DeepMind’s Genie 4: Real-Time World Model With Native Audio
Google DeepMind released Genie 4 as a research preview. The real-time world model adds native audio, live dialogue and text steering, with Gemini 3.8 Flash planning events inside the simulation loop.

Meet LEANN: An Open-Source Vector Index that Shrinks a 60M-Chunk RAG...
UC Berkeley’s LEANN vector index stores a pruned graph and recomputes embeddings at query time. It matches HNSW accuracy at 90% recall using 4 GB instead of 188 GB, at the cost of seconds-level search.

Liquid AI Releases LFM3: 6 Open-Weight 2B-Class Multimodal Models
Liquid AI released LFM3, 6 open-weight 2B-class models for text, vision, audio, omni and decisions. LFM3-1.7B uses a tri-hybrid backbone, a 256K context window and fits in about 1 GB at 4-bit.

Mirendil Launches Fern 0.1, Its First Model, With 10M-Token Context
Mirendil released Fern 0.1, its first model, pretrained from scratch with a 10M-token context window. It targets agentic AI R&D work, scores 100% on RULER single needle at 10M, but trails frontier models on agentic coding.

vLLM Semantic Router Releases d3-ultra: A 27B Open Multimodal Decision Model
vLLM Semantic Router released d3-ultra, a 27B open-weight multimodal decision model. It reads text, images and video once, then returns probabilities for every answer, scoring 87.2 on the team’s SR-Text test.

Baidu Open-Sources Unlimited OCR 2 for Hundred-Page Document Parsing
Baidu has released Unlimited OCR 2, an MIT-licensed 3B OCR model that parses hundred-page documents in one request. Its SR-SWA attention keeps per-step decoding cost nearly flat, scoring 77.1 on MarathonDocBench

OpenAI Launches GPT-6.1 Terra, Halving GPT-6.1 Sol’s API Price for Agent...
OpenAI released GPT-6.1 Terra, a fast computer-use and vision model priced at $1/$5 per million tokens. It matches GPT-6 Astra’s medium-effort Agents’ Last Exam score at $0.29 per task versus $4.82.

Nace AI Releases Drex for Search for AI Agents: 92.05% on...
Nace AI has released Drex for Search, bringing its Drex decision models to document search for AI agents. Nace reports 92.05% on BrowseComp-Plus with 12.6 search calls, and fewer agent turns on OfficeQA Pro.

Tsinghua AI Open-Sources AKV, a Cache Engineering Server for LLM Agents...
Tsinghua researchers released AKV, an SGLang-based serving system for cache engineering. LLM agents drop and reposition KV cache instead of summarizing history, cutting average cost 27.7% across 4 agent benchmarks.

Nanbeige Releases Nanbeige4.3-33B, a 33B Open Agentic Coding Model
Nanbeige LLM Lab released Nanbeige4.3-33B, a 33B dense Apache 2.0 model with 512K context. It reports 80.9 on Terminal-Bench 2.1 and will teach the upcoming Nanbeige4.3-3B.

Hugging Face Releases Carbon-X, a 14B Open DNA Language Model that...
Hugging Face released Carbon-X, an open 14.8B DNA language model built on Qwen3-14B. It reads raw DNA in chat, answers in English, and averages 66.7% across 5 DNA benchmarks under Apache 2.0.

Researchers from Stanford and UC Berkeley Introduce TokenGate: Token-Gated Attention Makes...
Stanford and UC Berkeley researchers released TokenGate, a drop-in learned token pruning module for LLMs. It cuts long-context prefill time-to-first-token by 1.4x to 11.3x and peak memory by 1.5x to 3.4x without accuracy loss.

Anthropic Launches OSS Scanner, a Free AI Vulnerability Scanner
Anthropic has launched OSS Scanner, a free, opt-in vulnerability scanner for critical open-source projects. The Anthropic OSS Scanner runs the company's strongest models, including...

Microsoft Open-Sources Agensh: A Multi-Agent Harness for 1,024 Agents
Microsoft Research open-sourced Agensh, a multi-agent harness with no central orchestrator. Self-organizing workers share a Git repo, chat and a findings board, scaling from 1 to 1,024 agents on ProgramBench under a 6-hour budget.

Cognition Open-Sources an Agent Plugin that Helps Secure Systems against Recent...
Cognition released the Devin Vulnerability Fixes plugin, 3 MIT-licensed agent skills that inventory, patch and test PHP, Node.js and self-managed GitLab deployments hit by this week’s critical RCE flaws, then open 1 PR per repo.

How to Run Underdog Saluki 27B: 2-Bit Qwen3.8-27B Tool-Calling Guide
Explore a complete coding guide comparing Underdog Saluki 27B with ISTA's GSQ-RCO quantization, examining GGUF headers, memory usage, and BFCL tool-calling performance in stock llama.cpp

Meet Anthropic’s sandbox-runtime: OS-Level Sandboxing for AI Agents, No Containers
Anthropic sandbox-runtime (srt) is the open-source, OS-level sandbox behind Claude Code. It restricts file and network access for agents, MCP servers and CLI tools with Seatbelt on macOS and bubblewrap on Linux, no containers needed.

NVIDIA Releases Nemotron 3.5 Bolt E4B 4GB: An Open Small Language...
NVIDIA released Nemotron 3.5 Bolt E4B 4GB, an open small language model post-trained from Gemma 4 E4B for local voice assistants, game characters and robots, targeting about 4GB of VRAM on RTX and Jetson.

Kyutai CADRE: Video Autoencoders That Cut World Model Lag Below 230...
Kyutai released CADRE, a family of 7 open causal diffusion video autoencoders for interactive world models. World models built on CADRE run at 20 fps on 1 H100 and react in under 230 ms.

Moonshot AI Releases Kimi K3.1 Pro: A 2.8T Total/104B Active Params...
Moonshot AI released Kimi K3.1 Pro, a 2.8T-parameter, 104B-active MoE model with 1M-token context. It scores 65.7% on Terminal-Bench 4.0, costs $2/$10 per million tokens, and open weights arrive by Nov 4, 2026.
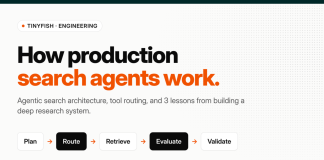
TinyFish Breaks Down Agentic Search Architecture for Production AI Agents
TinyFish published two engineering research articles on agentic search. One defines a 7-phase production architecture with evidence contracts and bounded retries. The other explains why its deep research system dropped a separate planner and per-query subagents.
Google Cloud Launches Agent Compute Engine: A MicroVM per AI Agent
Google Cloud announced Agent Compute Engine, a compute service that gives every AI agent its own hardware-isolated microVM with no credentials inside. It already runs Gemini agents and enters preview in the coming months.
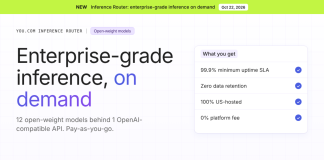
You.com Launches Inference Router: 12 Open-Weight Models With 99.9% Uptime SLA
You.com launched Inference Router, an OpenAI-compatible API for 12 open-weight models with a 99.9% uptime SLA, zero data retention, 100% US hosting, server-side web search and no platform fee.
Liquid AI Launches RIPL, a Real-Time Inference Engine for Sub-50 ms...
Liquid AI released RIPL, a real-time inference engine for its LFM models. On one B200, LFM2.5-1.2B on RIPL showed 14.4 to 28.4x lower p95 latency than Qwen3.5-0.8B on vLLM.
Gradium Open-Sources Phonon, a 31M-Parameter On-Device TTS Model Under Apache 2.0
Gradium has open-sourced Phonon, a family of on-device text-to-speech models. The English Phonon 31m ships under Apache 2.0, fits in 64.5 MB, and starts speaking in about 7 ms on a laptop CPU.
Cohere Releases Rerank 5 With Passage-Level Context Focus and Calibrated Scores
Cohere Rerank 5 ships in Pro and Fast tiers with a 32K context window, Context Focus passage extraction and calibrated relevance scores. Pro scores 82.2 on BRIGHT and costs $0.05 per 1M tokens.
A Developer’s Guide to OmniParseBench: Leaderboard Benchmarks and OCR Testing
Explore how to audit and rebuild Datalab's OmniParseBench, test parser ranking certainty with document-level bootstrapping, and evaluate Tesseract and Indra OCR performance on a custom sample.
IBM AI Releases Granite Speech 5.0 2B for Multilingual Transcription and...
IBM released Granite Speech 5.0 2B, an Apache 2.0 speech recognition and translation model. It ranks #2 on the Open ASR Leaderboard with 5.68% average English WER, alongside updated Turbo CTC and 4.1 2B Plus models.
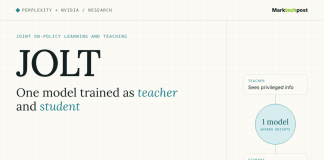
Perplexity and NVIDIA Researchers Introduce JOLT: a Joint Teacher-Student Reinforcement Learning...
Perplexity and NVIDIA introduced JOLT, a post-training method that trains one model as both teacher and student. On MATH it matched GRPO’s accuracy with 6.5x fewer processed training tokens.
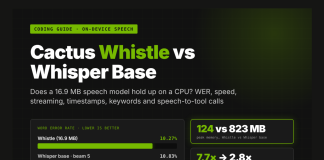
A Coding Guide to Cactus Whistle: Does a 16.9 MB Speech...
Explore a comprehensive coding guide benchmarking Cactus Compute's 16.9 MB speech model against Whisper base. Learn about word error rates, CPU speed, streaming latency, and speech-to-tool integration.
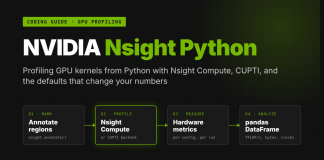
NVIDIA Nsight Python Tutorial: How to Profile GPU Kernels
Discover NVIDIA Nsight Python, an open-source interface that allows developers to profile GPU kernels, analyze hardware metrics, evaluate cache and clock controls, and measure kernel fusion directly from Python code.
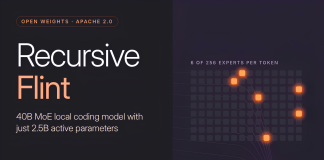
Recursive Releases Flint, an Open-Weight 40B MoE Local Coding Model for...
Recursive has released Flint, an Apache 2.0 local coding model with 40B total and 2.5B active parameters. It reports 74.2% on SWE-bench Verified and 125+ tokens per second on an M4 Pro MacBook Pro.
Vercel Open-Sources durable-harness for Crash-Proof Coding Agents
Vercel released durable-harness, an open-source package that logs every model and tool call so Pi, OpenCode, Claude Code and Codex sessions resume after crashes, timeouts and redeploys on Vercel, Postgres or a laptop.
Mistral AI Releases Voxtral 3: Speech-to-Text, TTS and a Voice Agent...
Mistral AI released Voxtral 3, a family of 3 transcription models, 1 text-to-speech model and a LiveKit-based voice agent SDK. Voxtral Small Transcribe 3 scores 2.1% AA-WER, ranking #3 on Artificial Analysis.
Google Cloud Ships llm-d 1.0 With Cache-Aware Routing for TPU and...
Google, Red Hat and IBM released llm-d 1.0, an open-source Kubernetes-native stack for distributed LLM inference. It adds multi-tenant flow control, zero-downtime upgrades and agent-aware routing across vLLM, SGLang, TPUs and GPUs.
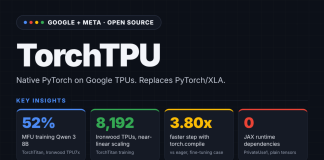
Google Open-Sources TorchTPU, a Native PyTorch Backend for Cloud TPUs
Google and Meta open-sourced TorchTPU, a native PyTorch backend for Cloud TPUs. It runs eager by default, compiles through torch.compile and XLA, and replaces PyTorch/XLA for new workloads.
DeepSeek Open-Sources DeepInfer, the Inference Framework Behind DeepSeek-V4.1-Flash
DeepSeek has open-sourced DeepInfer, the Apache 2.0 inference framework that serves DeepSeek-V4.1-Flash in production. It targets NVIDIA SM100 GPUs and Huawei Ascend 950 NPUs, and ships offline inference only.
Exa 3.0 Search API Tops Perplexity, Brave and Parallel on 8...
Exa 3.0 is a search API upgrade from Exa. It adds a larger embedding model, Exa Lite at $4 per 1,000 requests, and Dynamic Highlights, and leads 8 benchmarks Exa ran itself.
Cloudflare Releases Clairic, a System One Extraction Model on Workers AI
Cloudflare has previewed Clairic, a System One extraction model on Workers AI that returns typed values with confidence scores in one forward pass. It costs $0.10 per million input tokens and charges nothing for output.
Inception Releases Mercury 3 Diffusion LLM at 1,068 Tokens per Second
Inception released Mercury 3, a diffusion LLM it says runs at 1,068 tokens per second with a 1M-token context. On Inception’s own table it leads GPT-6 Luna and Claude Haiku 5.5 on 8 of 12 benchmarks.
Meet Drex Max: Nace AI’s Multimodal Decision Model for Computer-Use Agents...
Nace AI released Drex Max, a multimodal decision model that reads text and screenshots and returns calibrated probabilities. Nace reports 67.59 on Decision Index 0.3.2 at $0.06 per 1M input tokens.
MiniMax Just Launched M3.1 Flash: 428B MoE Agentic Model at $0.15/M...
MiniMax has released M3.1 Flash, a 428B-parameter MoE model with about 23B active parameters and a 1M-token context. API pricing is $0.15/$0.60 per 1M tokens, with weights due October 23
NVIDIA Open Sources Run:ai Under Apache 2.0 for Kubernetes GPU Orchestration
NVIDIA has released the full Run:ai GPU orchestration platform as open source under Apache 2.0. The release includes KAI Scheduler, CUDA 13.4 GPU fractioning, quota management, and a local Kind dev environment.
Mistral AI Releases Timestral: A 209M Forecasting Model Family That Outperforms...
Mistral released Timestral, a time series foundation model family from 5M to 209M parameters. The 209M model leads GIFT-Eval, TIME and fev-bench among zero-shot models and runs on CPU.
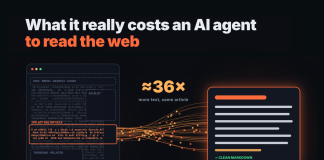
TinyFish Makes Search Free: What It Really Costs an AI Agent...
An AI agent that reads the web pays 2 kinds of cost. The first is the retrieval charge: what a search or fetch API...
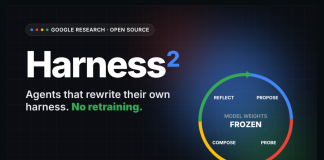
Google Open-Sources Harness2, a Recursive Agent Harnessing Framework
Google Research released Harness2, an Apache-2.0 framework that rewrites an agent's harness at test time. One refinement step lifted GLM-5 by 11.5 points on WorkBuddy-Bench with no weight updates.
How to Make Zero-Training Tabular Predictions with NVIDIA Structured Data Models
In this tutorial, we implement Structured Data Models, NVIDIA's new library that puts several pretrained foundation models for tables behind one PyTorch interface, and...
Meet Voxel51 3.0: A Unified Multimodal Data Platform for Physical AI
Voxel51 3.0 merges search, curation, annotation and evaluation of multimodal sensor data into one platform for physical AI teams. It adds Voxel51 Agent with 45+ MCP tools, dataset versioning, and a free self-service tier.
Meet Kyutai REKI: The 2.4B VLA Model Bringing Efficient Memory to...
Kyutai, with Inria and École des Ponts, has released REKI, a 2.4B vision-language-action model (VLA) for robot manipulation. The REKI vision-language-action model is pretrained...
DeepSeek Just Released V4.1-Flash-1017, Scores 77.0 on DeepSWE, Opens Search API
DeepSeek has just released DeepSeek-V4.1-Flash-1017, a new checkpoint of its V4.1-Flash model. It is live on the DeepSeek website, app and API. DeepSeek claims...
20 Jev Alternatives: The Decision Models Taking On TypeSafe in 2026
TypeSafe launched Jev on September 15, 2026. It is a decision model, not a chatbot. You define the allowed answers, and Jev returns a...
StepFun Releases Step 5 Preview Open Weights: 600B MoE, 27B Active,...
StepFun has released Step 5 Preview as open weights. FP8 and BF16 checkpoints are live on Hugging Face and ModelScope. Step 5 Preview is...
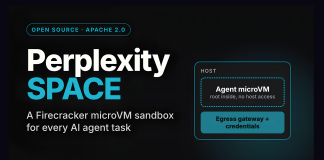
Perplexity Open-Sources SPACE, a Firecracker MicroVM Sandbox for AI Agents
Perplexity has open-sourced SPACE, the sandbox platform behind every task in Perplexity Computer. The Perplexity SPACE sandbox gives each agent task its own Firecracker...
Liquid AI Releases d1-ultra: A Multimodal Decision Model That Scores 65...
Liquid AI released d1-ultra, a text and image decision model that returns calibrated probabilities in 1 forward pass. It scores 65 on the Artificial Analysis Decision Index and costs $0.042 per million input tokens.
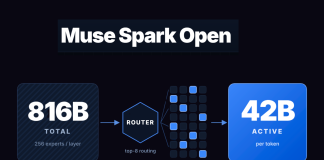
Meta Releases Muse Spark Open: 816B Open-Weight MoE With 1M Context
Meta released Muse Spark Open, an 816B-parameter open-weight MoE model with 42B active parameters and a 1M-token context. It leads open models on MCP-Atlas and runs on 2 M5 Ultra Mac Studios.
NVIDIA Releases Nemotron 3.5 Super VL, a 120B Open Multimodal Agent...
NVIDIA released Nemotron 3.5 Super VL, an open 120B-parameter multimodal MoE model with 12B active parameters, 1M-token context and NVFP4 weights that run on 1 DGX Spark, plus 2 Bolt edge models.
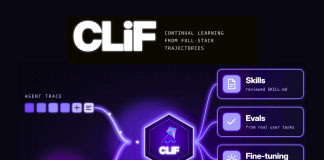
CopilotKit Releases CLiF: A Continual Learning Platform That Turns Agent Traces...
Introduction
Teams shipping AI agents at scale keep running into the same pattern. Even agents built on top-tier models like Fable and Astra struggle to...
openKylin Outlines Its Vision for Reimagining Linux in the AI Era...
At Open Source Summit Europe 2026, openKylin outlined its vision for transitioning from resource management to intent management in the AI era. The community introduced KART, a unified AI runtime, alongside core desktop features in openKylin 3.0 like the AI Assistant, Global Intelligent Search, and Intelligent Space
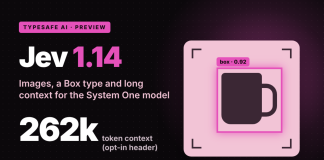
TypeSafe AI Releases Jev 1.14 With Images, Box Type and 262k...
TypeSafe AI released Jev 1.14 under the jev-preview alias. The System One model adds experimental image input, a Box bounding-box type and an opt-in 262k-token context, at $0.042 per million input tokens.
Meet Grok Voice 3.0: SpaceXAI Voice Agent Model Ranks #1 on...
SpaceXAI just released Grok Voice 3.0. Grok Voice 3.0 is a SpaceXAI speech-to-speech model that listens, reasons, calls tools and speaks. It now ranks...
Datalab Releases OmniParseBench: An Open OCR Benchmark With 16,288 Pass/Fail Tests...
Datalab released OmniParseBench, an open OCR benchmark with 16,288 yes/no tests on 2,937 pages in 92 languages. Every score is a pass rate you can slice by tag, script or language.
Fish Audio Releases Drama 3, a 35B Open-Weight MoE Text-to-Speech Model
Fish Audio released Drama 3, a 35B mixture-of-experts text-to-speech model with about 3B active parameters. It takes plain-language direction, covers 83 languages and ships open weights under a revenue-capped community license.
9 Best AI Gateways in 2026: Bifrost, Portkey, LiteLLM, Kong and...
Marktechpost ranks the 9 best AI gateways for 2026. We compare Bifrost, Portkey, LiteLLM, Kong, TrueFoundry, Cloudflare, Vercel, OpenRouter and Orq.ai on latency, pricing, licensing, governance and deployment.
Liquid AI Releases LFM2.5-24B-A2B: A 2B-Active MoE for On-Device Agents
Liquid AI released LFM2.5-24B-A2B, an open-weight 24B Mixture-of-Experts reasoning model with 2B active parameters. It targets local agents, scoring 48.09 on LiveClaw and decoding 184 tokens/s on an Apple M5 Max.
Meta Launches Muse Wonder and Muse Wonder Full: Benchmarks, Pricing and...
Meta released Muse Wonder and Muse Wonder Full, 1M-context agent models. Muse Wonder costs $4/$20 per million tokens on Meta Model API. Wonder Full, on Muse Code plans, leads DeepSWE and SWE-Marathon.
How to Use Meta’s Rebalancer for Task Placement & Optimization
In this comprehensive coding tutorial, we explore Meta's Rebalancer assignment solver using its C++ core and Python bindings. Learn how to build datacenters, manage task placements across racks, handle constraints and goal priorities, and compare local search against the exact HiGHS solver using published benchmarks.
Z.ai GLM-Legal Beats Claude Fable 5 and Kimi K3 on Harvey...
Z.ai’s GLM-Legal is a legal AI model built on GLM-5.3-Flash. It scores 19.2% all-pass on Harvey’s Legal Agent Benchmark, nearly 3x its base, at $0.15 per test. Access is by application.
Alibaba Qwen Introduces QwenGyre: Elastic Reinforcement Learning RL for XLong-Horizon Agents
Alibaba's Qwen team has introduced QwenGyre, an elastic reinforcement learning RL framework for extreme-long-horizon agent training. QwenGyre is an online reinforcement learning system from...
Top 12 AI Live Translation Tools in 2026: Latency, Languages, Pricing
We checked 12 AI live translation tools, including Palabra.ai, Google Live Translate, DeepL Voice, Teams Interpreter and Wordly, against official pages for languages, latency, platforms and pricing.
TII Releases Falcon-ASR: 1.6B Arabic Speech Model Hits 20.92% WER
TII has released Falcon-ASR, a 1.6B speech recognition model for Arabic with an Emirati focus. It reports 20.92% average WER on 6 Arabic test sets, but weights and an API are not yet available.
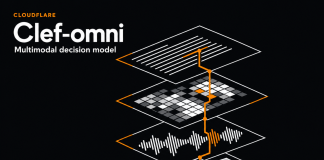
Meet Cloudflare Clef-omni: A 30B-A3B Multimodal Decision Model for Audio, Video,...
Cloudflare released Clef-omni, an Apache-2.0 multimodal decision model built on Qwen3-Omni-30B-A3B. It scores text, images, audio and video in one call for $0.15 per million input tokens, while Clef-flash drops to $0.038.
What is Decision 3.0? vLLM Semantic Router’s New Open Decision Models
vLLM Semantic Router released Decision 3.0, 5 Apache-2.0 multimodal decision models from 0.8B to 27B. They answer choice, yes/no and score questions about text and images in one call, without generating text.
OrcaRouter Releases OrcaCyber Zero 1.5 Cybersecurity Model With 1M Context
OrcaRouter released OrcaCyber Zero 1.5, a gated cybersecurity model with a 1M-token context window. It reports 100% on Cybench and 95.8% on an evaluable CVE-Bench subset, priced at $3.00 / $7.50 per 1M tokens.
Sakana AI’s LLM Peer Review System Catches 73% of Core-Claim Errors
Sakana AI’s TMLR paper introduces Multi-Layered Review, a 3-agent Claude-based reviewer, and a 1,164-error Contradiction Benchmark. MLR caught 73.43% of core-claim errors, versus 14.81% for the best prior system.
Microsoft AI Releases Microsoft-Decision-1: A Qwen3.5-9B Decision-Scoring Model
Microsoft has released Microsoft-Decision-1, a decision model for routing, classification, verification and agent control. Microsoft-Decision-1 is a decision-scoring model that returns a calibrated probability...
Nace AI Open-Sources Drex 1.5: A 9B Decision Model That Scores...
Nace.AI has open-sourced Drex 1.5, a 9B decision model that returns a probability for every option in 1 forward pass. It scores 58.08 on Decision Index 0.3.1 and reads up to 128K tokens.
Alibaba Qwen Releases Qwen-Image-2.1-Turbo, an 8-Step 7B Image Model
Alibaba's Qwen team has released Qwen-Image-2.1-Turbo, an accelerated checkpoint of its open-weight Qwen-Image-2.1 model. It generates and edits images in 8 denoising steps instead...
OpenAI Decisions API Hits Public Beta With 10x Faster Typed Answers
OpenAI’s Decisions API is now in public beta on GPT-6 Luna. It returns typed probabilities, choices and scores about 10x faster than the Responses API, billing $0.10 per 1M input tokens with no output charges.
Meet the Underdog Saluki 27B: A 2-bit Qwen3.8-27B That Beats the...
Underdog Saluki 27B is a 7.89 GB, 2-bit GGUF of Qwen3.8-27B under Apache 2.0. It beats the 54 GB original on tool calling but gives up ground on competition math and reasoning.
Google Cloud Launches Gemini Agent, One Universal Agent for Enterprise Work
Google Cloud has introduced the Google Cloud Gemini agent, a single agent for enterprise work. The Gemini agent is a cloud-hosted agent from Google...
JetBrains Releases Mellum2.1: A 12B MoE Open Model for Coding Agents
JetBrains released Mellum2.1, an Apache 2.0, 12B mixture-of-experts thinking model with 2.5B active parameters. RL in real repositories lifted its SWE-bench Verified score from 2.0 to 47.0.
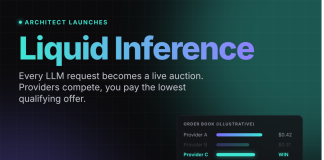
Architect Launches Liquid Inference, a Real-Time Auction for LLM Inference
Architect Financial Technologies has launched Liquid Inference, an LLM router that runs a live auction for every request. Liquid Inference is an LLM inference...
NVIDIA PivotOPD Teaches Multi-Turn AI Agents to Recover From Pivotal Mistakes
NVIDIA researchers introduced PivotOPD, an on-policy distillation method that trains multi-turn LLM agents to avoid early pivotal mistakes and recover from them, posting the best average against 13 baselines on 3 agent benchmarks.
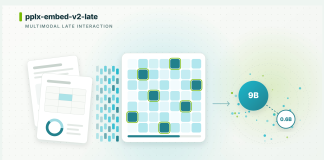
Perplexity AI Releases pplx-embed-v2-late: A 0.6B Edge Model and a 9B...
Perplexity's pplx-embed-v2-late comes in 2 sizes: a 0.6B model built to run on edge devices, and a 9B model for building high-quality indexes. Its best score is 92.4% on MADQA, and its weakest is 61.2% on ViDoRe v3 Markdown. Both are MIT-licensed and ready to self-host.
What Happens When a Trusted Model Repo Changes? Unsloth Studio Re-Checks...
Unsloth's October 6 security overview explains how Studio checks code, weights, packages and tools before anything runs. Custom model code is scanned and approval is bound to its fingerprint. Flagged weight files are blocked in the load path, package-content findings fail CI, and tools run in probed OS sandboxes. Here is what each checkpoint decides, and what it does not cover.
Anthropic Releases Claude Haiku 5.5: A Small Model With 1M Context...
Anthropic's Claude Haiku 5.5 starts at $0.10 per million input tokens, keeps 1M context, scores 72.4% on OSWorld.
Liquid AI Releases Open-Weight d1-3B and d1-omni-600M: Multimodal Decision Models With...
Liquid AI has released Open d1, two open-weight multimodal models in its d1 decision model family. d1-3B reads text and images. d1-omni-600M reads text...
Meta AI Open-Sources Rebalancer: A C++ Assignment Solver That Runs About...
Meta has open-sourced Rebalancer, the C++ and Python library it has used for over 9 years to place shards, servers and traffic. It handles about 40 million assignment problems a day, using local search or MIP solvers like Gurobi, FICO Xpress and HiGHS. It is pip-installable under Apache 2.0.
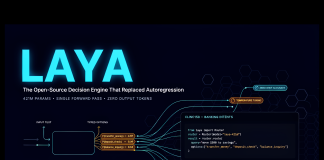
A Developer’s Guide to Laya: Zero-Shot Decisions and Calibration
Explore a comprehensive coding guide to Laya, the open-source zero-shot decision engine. Learn how to implement typed decisions, fit custom temperatures, and build reliable abstention gates using real-world CLINC150 banking data.
Google DeepMind Releases EmbeddingGemma 2, a 740M Open Multimodal Embedding Model...
Google DeepMind's EmbeddingGemma 2 maps 5 input types into one 768d space and ships today under Apache 2.0.