
Comparison
Breaking News
20 Jev Alternatives: The Decision Models Taking On TypeSafe in 2026
TypeSafe launched Jev on September 15, 2026. It is a decision model, not a chatbot. You define the allowed answers, and Jev returns a...
9 Best AI Gateways in 2026: Bifrost, Portkey, LiteLLM, Kong and...
Marktechpost ranks the 9 best AI gateways for 2026. We compare Bifrost, Portkey, LiteLLM, Kong, TrueFoundry, Cloudflare, Vercel, OpenRouter and Orq.ai on latency, pricing, licensing, governance and deployment.
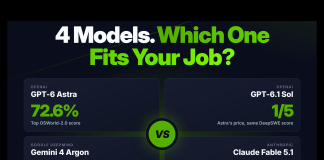
GPT-6 Astra vs GPT-6.1 Sol vs Gemini 4 Argon vs Claude...
Astra leads computer use, Argon leads legal and finance work, and Sol wins on price for coding agents.
Cloudflare Releases Clef and Clef-flash: Open-Weight Decision Models That Return Typed...
Cloudflare has released Clef (27B) and Clef-flash (9B), open-weight decision models that return typed probabilities instead of text. They are Jev-API compatible, accept images, and run on Workers AI at 209.3 ms and 38.8 ms median latency.
Google DeepMind Unveils Gemini 4 Argon with 1M Output Tokens for...
Gemini 4 Argon tops GPT-6 Astra and Claude Opus 5.5 on most benchmarks, but access remains gated today.
GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained...
GGUF, GPTQ, AWQ, EXL2, and EXL3 solve the same problem in different ways. This guide separates file containers from quantization methods. It explains bits per weight, calibration, and hardware fit. Then it shows which format to pick for Macs, consumer GPUs, and production serving.
Agent Harness vs Agent Framework vs MCP: Which Layer Owns the...
A practitioner's map of the 3 layers in a modern agent stack, with verified sources and an overlap analysis.
Lowest-Latency Inference APIs for Voice and Realtime Agents: A Time to...
Voice agents fail on latency long before they fail on intelligence. Time to first token is the metric most teams use to choose an inference API, and it is the right starting point and the wrong stopping point. This benchmark works through every layer of the voice stack — LLM, speech-to-text, text-to-speech, and speech-to-speech — using figures verified against primary sources on August 30, 2026, with each number labeled as independently measured, vendor-published, or vendor-measured on its own product.

GLM-5.3-Flash vs Qwen3.8-Flash-Next: Two Chinese AI Labs Independently Converge on the...
Z.ai and Qwen independently shipped near-identical architectures: 3:1 linear hybrids, compressed indexers, gated residuals, and Muon training.
Best Agent Sandboxes in 2026: Cold Start, Per-Second Pricing, and Network...
Every agent that writes code needs somewhere to run it, and no two vendors quote the same units. This comparison measures burst cold start across E2B, Daytona, Modal, Cloudflare, and Vercel, normalizes per-second rates to cost per 1,000 executions, and maps filesystem persistence, idle billing, and egress policy against primary sources verified August 27, 2026.