
Uncategorized
Breaking News
Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a...
Anthropic has published a new plugin evals workflow for Claude Code. The claude plugin eval command runs a plugin against realistic prompts, grades what...
Cohere Releases North Small Translate: A 218B MoE Translation Model That...
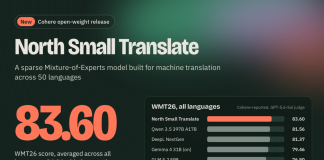
Cohere has released North Small Translate, an open-weight Mixture-of-Experts model built for machine translation across 50 languages. It uses 25B of its 218B parameters per token and scores 83.6 on Cohere's WMT26 evaluation. Weights are free for non-commercial use, with commercial access through Cohere Model Vault or RWS Language Weaver.
Sakana AI Launches Fugu Max and Fugu Ultra v2 for Cheaper,...
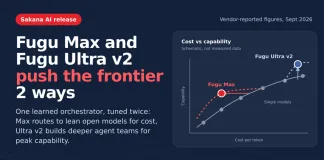
Sakana AI has released Fugu Max and Fugu Ultra v2, 2 models built on the same learned orchestration architecture. Fugu Max routes tasks to lean open and specialized models, including NVIDIA Nemotron, at $2/$6 per 1M tokens. Fugu Ultra v2 targets peak capability, scoring 48.3 on Chartography and 74.3 on DeepSWE.
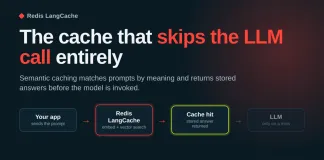
Meet Redis LangCache: A Managed Semantic Cache That Cuts LLM API...
Production LLM applications rarely receive a question nobody has asked before. Support assistants and RAG pipelines field the same intents thousands of times a...
Gradium Launches Voice Design: Write a Prompt, Get a Brand New...
Voice agent teams keep hitting the same wall. The catalog holds 400 voices and the brief asks for the one that is not in...
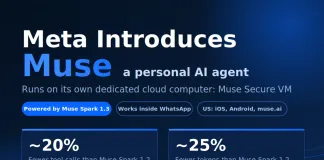
Meta Introduces Muse, a Personal AI Agent That Runs on Its...
Today, Meta has introduced Muse, a personal AI agent that takes actions rather than just answering questions. Muse can send emails, book travel, negotiate...
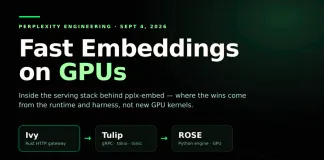
Perplexity Details Its GPU Embedding Stack: How Ivy, Tulip and ROSE...
Retrieval quality in an AI search product is bounded by two things: how good the embedding model is, and how cheaply you can run...
Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver...
WeatherNext 3 ingests live geostationary satellite mosaics, refreshes hourly, and outputs 5 km forecasts across Search, Gemini, Maps.

Anthropic Released Claude Commerce Agents: An Apache-2.0 Blueprint for Shopping and...
Most teams building a shopping assistant or agent rebuild the same scaffolding: an agent loop, a tool layer over the catalog, an approval gate,...
Qwen Developers Open-Sources zg (zvec-grep): A Local-First Search Layer Unifying ripgrep,...
We look at zg (zvec-grep), the local-first search layer that Qwen Developers just open-sourced under Apache 2.0. We explain how it puts ripgrep, BM25, and vector search behind a single interface, so an agent can move from a plain-language description to an exact line span without switching tools. We cover the deliberately small MCP surface, the on-device embedding catalog, and the authorization gate that stands between local content and remote models.
Meta Superintelligence Labs Releases Muse Voice Transcribe: One Real-Time Model for...
Most production voice stacks are three systems stitched together. One model transcribes, a second separates speakers, and a detector decides when the user stopped...

Researchers from Princeton, Ant Group and Stanford Introduce AQuA: A Two-Part...
Quantitative research agents that write their own experiments can corrupt the evidence they later learn from. A leaky feature that scores well gets stored...
OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI...
The OpenClaw Foundation has released v2026.8.1, which the project calls OpenClaw 2.0: 933 contributors, 569 first-timers, and more than 16,000 pull requests, roughly half of every PR ever merged into the repo. Setup now reuses existing subscriptions, API keys and local models. The rebuilt Control UI cut test-harness startup from about 1.6 seconds to 575 ms. Shared cloud sessions add real multiplayer, though the docs are explicit that they are not a security boundary.

Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent...
Google Cloud AI Research, with Washington University in St. Louis and UNC Chapel Hill, has released EnvHarness, an Apache-2.0 layer that turns a static agent benchmark into one that adapts to the policy training on it. It wraps a frozen environment through the standard reset()/step() interface, so tasks and human-built verifiers stay untouched — and an LLM designer, EnvRigger, writes those wrappers automatically against flaws diagnosed in the agent's own rollouts. Across five benchmarks, mined skills gain up to 9.0 points on held-out tasks with 9.8% fewer execution steps.
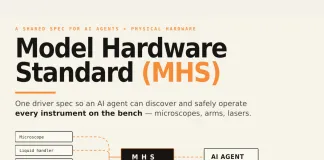
Anthropic Opens a Research Preview of the Model Hardware Standard (MHS):...
Anthropic has opened a research preview of the Model Hardware Standard (MHS), a shared driver specification that lets AI agents discover and safely operate physical devices. Instrument integration that normally takes weeks or months drops to hours: Carnegie Mellon went from raw equipment to a finished dose-response curve in eight, and QuEra's laser relock improved from 58% to 99.3% across 700 trials. MHS is model-agnostic, reachable over MCP, and enforces safety limits in the driver rather than the prompt.
Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent...
Vercel has open-sourced vgpu, the WebGPU library it built to ship the shaders on vercel.com. It treats .wgsl files as importable TypeScript modules, runs the same shader in the browser, in headless Node.js via Dawn, and in a deterministic CI mock, and ships a fullscreen effect in 25 KB gzipped.

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous...
Google Research and UNSW Sydney released GlucoFM, a self-supervised foundation model that splits a CGM trace into a slow physiological stream and a transient event stream instead of encoding it as one sequence. At 0.72M parameters it reached 58.8 task-averaged PR-AUC across 14 cohort–task evaluations, beating a 135M GluFormer and a 385M MOMENT. It remains a research prototype with no regulatory clearance.

Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B...
We look at Qwen3.8-Flash-Next, Alibaba's open-weight multimodal Mixture-of-Experts model and an early preview of the Qwen4 architecture. We break down where the 180B parameters actually sit: a 125B backbone, a 51B N-gram embedding table, and a 4B multi-token prediction module, with only 6B active per token. We walk through the four architectural changes — the Gated DeltaNet and Qwen Sparse Attention hybrid, Gated Residual, N-gram Embedding, and the Muon optimizer. We also cover the benchmark results, the reported 1/9 training cost against Qwen3.7-Plus, and what self-hosting a 172.78 GiB FP8 checkpoint really demands.

What Would Have to Be True for Agentic Coding to Replace...
Four falsifiable conditions for agentic coding replacing juniors, tested against METR, OpenAI, DORA and Stanford primary source evidence

IBM Releases Granite 4.2: Bringing Native Reasoning and Agentic RL to...
IBM has released Granite 4.2, a family of open reasoning language models in 3B, 8B, and 30B sizes, all under Apache 2.0. Every model exposes a thinking / low-effort / non-thinking switch and native tool calling. The 8B and 30B additionally go through an agentic RL block that trains them to edit code, drive a terminal, and run web searches inside real sandboxed environments. The 30B reports 57.00 on SWE-Bench Verified and 29.24 on Terminal-Bench 2.1.

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device...
Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI...

Perplexity Ships Portable Computer on NVIDIA DGX Spark: Local Harness, OS-Enforced...
Perplexity releases Portable Computer, packaging local models, harness, sandbox, and connectors into one system running on NVIDIA DGX Spark.
Generalist AI Releases GEN-1.5: A Robot Foundation Model That Learns New...
Generalist AI has released GEN-1.5, a robot foundation model that learns a new physical task from a single demonstration. Drop 3–12 seconds of sensorimotor...
Best GPU Neoclouds 2026: CoreWeave, Nebius, Lambda, Crusoe, and Groq Ranked...
The five largest GPU neoclouds now run on very different models. CoreWeave and Nebius report to the SEC; Lambda and Crusoe are private and heading toward IPOs; Groq rebuilt itself as an inference cloud after licensing its LPU technology to NVIDIA. This comparison checks each provider's live rate card, Q2 2026 financials, active and contracted gigawatts, anchor contracts, and SemiAnalysis ClusterMAX tier. Nebius posts the lowest H100 rate and the only published B300 price, Lambda has the cheapest B200, Crusoe is the only one with AMD on its card, and CoreWeave commands a 10–15% premium as the sole Platinum-rated provider. Figures verified August 21, 2026.

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2...
FreeToken splits MoE cache misses between PCIe fills and CPU execution using measured bandwidths, unlocking frontier models locally

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both...
Cartesia has released Sonic-3.6, a streaming text-to-speech model built on state space models rather than transformers. It now ranks #1 on both Artificial Analysis speech leaderboards — 1,283 Elo on Provider Voice and 1,123 on Controlled Voice, the board that clones every model onto the same eight reference voices to isolate the synthesis engine. Cartesia states sub-90ms time-to-first-audio. The model is available in beta on Cartesia's own API

MiniMax Releases MiniMax-Music3: An Open-Weights Music Model Generating Complete Five-Minute Songs...
MiniMax released MiniMax-Music3, an open-weights text-to-music model. Given lyrics with section tags and a structured caption, it generates a complete song of up to five minutes in a single pass, as 32 kHz, 16-bit stereo WAV. Here is the architecture, the three serving paths, and the license conditions that matter before you ship.
Meet Needle 2: An Open 45M-Parameter Tool-Calling Model That Ships as...
Cactus Compute released Needle 2, an open 45M-parameter model for tool calling, device use, and structured extraction. The full model is a single 14MB binary that runs a session in about 28MB of RAM. It leads both Seal-Tools splits while targeting hardware with no GPU and no NPU.
Create a Reasoning-Focused LLM: A Practical Guide to Streaming, Curating, and...
This tutorial provides a complete workflow for building a compact, reasoning-focused language model. By streaming the SupraLabs reasoning corpus from Hugging Face, we apply quality filters and curate data for Supervised Fine-Tuning (SFT). Using SmolLM2-135M-Instruct and LoRA, we demonstrate an end-to-end pipeline—from dataset analysis and heuristic cleaning to efficient training and inference—enabling the development of specialized small models without excessive resource requirements

Google AI Just Released Gemini 3.7 Flash: A Coding and Agent...
Google has released Gemini 3.7 Flash, a refinement of Gemini 3.6 Flash with algorithmic improvements to its reasoning core. It handles text, images, audio, and video across a 1M-token context window with 64K-token output, and supports customizable thinking configurations. Coding results move notably: 43.6% on FrontierCode 1.1 Main versus 34.4%, 65.3% on DeepSWE v1.1, and 1588 Elo on WebDev Arena. Document and workflow evals gain more — GDP.pdf goes from 22.0% to 34.0%, AutomationBench from 17.0% to 30.4%. GPT-5.6 Terra still leads on terminal and computer-use agents. The model is API and enterprise only, with no open weights, at an introductory $0.75/$3.75 per 1M tokens through December 31, 2026.
Liquid AI Releases LFM2.5-VL-3B: A 3B Vision-Language Model That Reads Screens,...
Liquid AI released LFM2.5-VL-3B, a 3.1B-parameter vision-language model built for on-device deployment. It averages 80.7 on ScreenSpot-v2 and lifts RefCOCO grounding from 57.1 to 87.9. Function calling is new to the VL line, with ToolSandbox moving from 26.4 to 59.5. The model fits in roughly 3 GB and decodes 228 tokens/s on an Apple M5 Max.
AllenAI Open Instruct Tulu 3 Post-Training with SFT, DPO, RLVR, GRPO,...
Build a custom LLM post-training pipeline using AllenAI’s Open Instruct framework. This comprehensive guide walks through Supervised Fine-Tuning (SFT), Direct Preference Optimization (DPO), and Reinforcement Learning with Verifiable Rewards (GRPO), optimized to run efficiently on 16GB hardware without needing heavy distributed computing infrastructure.

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with...
NVIDIA's open 30B MoE targets the agent execution layer, with Switchyard routing each step to the cheapest capable model.
The Video Production Stack Now Fits on One Desk: LTX-2.5 Launches...
LTX-2.5 brings frontier video generation to local NVIDIA hardware: 6.8-second clips, native multishot, day-one ComfyUI, open weights.
NVIDIA Releases NemotronLabs VoiceChat 11B: An Open Full-Duplex Speech-to-Speech Model with...
NVIDIA releases NemotronLabs VoiceChat 11B, an open full-duplex speech-to-speech model with 448 ms latency and live tool calling.

Top LLM Observability and Evaluation Platforms in 2026: Langfuse, LangSmith, Braintrust,...
A verified 2026 comparison of LLM observability platforms covering tracing depth, evaluation capability, production monitoring, and pricing.
Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety...
Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that frames content moderation as a single yes/no question instead of a fixed harm taxonomy. Operators supply the policy as a plain-language query at inference time and get back a calibrated safety score from one forward pass — no retraining required to re-target the model. Built on Ministral-3-3B-Base-2512 with a Pixtral vision encoder and trained on roughly 54.1M samples, it reports 84.9% average F1 on text safety (matching GPT-OSS-Safeguard-20B), 83.8% on multimodal safety, and 91.3% on Mistral's adaptability benchmark — while fitting in 16GB of VRAM under an Apache 2.0 license.
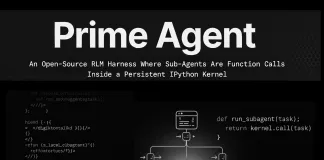
Prime Intellect Releases Prime Agent: An Open-Source RLM Harness Where Sub-Agents...
Prime Intellect has open-sourced Prime Agent, a coding and research harness built on two abstractions: the Recursive Language Model, which turns sub-agent calls into functions inside a persistent IPython kernel, and the Continual Harness, which lets the agent edit its own prompts, skills, memory, and sub-agent specs mid-run. With Opus 5 it reports 95.5% RHAE Best@1 on ARC-AGI-3, above the reported human expert baseline of 95.4%.
NVIDIA Releases Alpamayo 2 Super: A 34B Open Vision-Language-Action Model for...
NVIDIA released Alpamayo 2 Super, a 34B vision-language-action model for autonomous driving, under OpenMDW-1.1 — a permissive license covering fine-tuning, derivatives and commercial redistribution. It pairs a 32B Cosmos 3 Super Reasoner backbone with a 2.3B diffusion action decoder, scores 79.2 on LingoQA, and emits trajectories, Chain-of-Causation traces, meta-actions, auto-labels and grounded VQA from a single pass.

How to Secure AI Agents, MCP Servers, and LLM Apps in...
AI agents, MCP servers, and LLM apps break the core AppSec assumption that applications do what their code says. This guide walks through a practical see-fix-protect framework: a five-layer agentic AI attack surface map, a 12-point misconfiguration checklist, an evidence-based triage matrix, runtime guardrails, and system prompt hardening — plus a maturity self-assessment aligned to NIST AI RMF, OWASP AIMA, ISO/IEC 42001, and the EU AI Act.
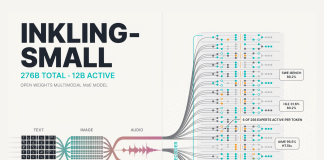
Thinking Machines Lab Releases Inkling-Small: A 276B Total, 12B Active Open...
Inkling-Small matches Inkling at a quarter the size, and its NVFP4 checkpoint runs on one NVIDIA B300 GPU
NVIDIA AI Releases Molt: A PyTorch-Native Agentic Reinforcement Learning Framework
Agentic RL research is constant algorithm modification, and in mainstream frameworks every change threads through trainer, distributed backend, and rollout glue. NVIDIA's Molt targets that cost with about 8.6K lines of RL code, composing Ray, vLLM, and NeMo AutoModel around one asynchronous loop. The agent stays ordinary Python, trajectories stay token-exact, and throughput comes out statistically comparable to a Megatron-based stack.
LingBot-Map Tutorial: GPU-Aware Inference and Point Cloud Export
Discover how to implement a streaming 3D reconstruction pipeline using LingBot-Map. From GPU-aware configuration and preprocessing to GCTStream model inference and point cloud generation, this guide walks you through the steps to convert image or video sequences into consistent 3D scenes with exportable PLY and NPZ artifacts.

Building a Policy-Governed Multi-Agent Financial Research Workflow with Omnigent
In this tutorial, we demonstrate how to build and execute a multi-agent workflow with Omnigent in a secure, isolated Python environment. Learn to integrate live exchange-rate data, implement hierarchical agent delegation for financial text auditing, and apply hard governance policies—such as cost budgets and tool call limits—to your research pipeline directly from Google Colab.

Tencent Open-Sources AngelSpec: A Unified Training Framework for MTP and Block-Parallel...
Tencent has released AngelSpec, an open-source torch-native framework for training speculative-decoding draft models across six architectures. It introduces DFly, a block-diffusion drafter with hybrid target conditioning and a hidden-correction autoregressive head, and integrates D-cut for runtime-adaptive verification budgeting. On HY3-295B-A21B with TP=8, DFly-8 delivers a 1.98–2.40× speedup over autoregressive decoding across concurrency 4 to 64.

Prompt Engineering vs Loop Engineering vs Graph Engineering: What Changes at...
Three terms now compete for the same line in AI engineering job descriptions. Prompt engineering is the established one. Loop engineering entered the AI...

Induction Labs Photon-1 Simulates Desktops, Plays Checkers, and Models Billiard Physics...
Most agents that learn from video need to know what action produced each frame. Induction Labs is arguing that this requirement is the bottleneck....
Poolside Releases Laguna S 2.1, an Open-Weight Agentic Coding Model Punching...
Poolside has released Laguna S 2.1, a 118B open-weight Mixture-of-Experts coding model with 8B active parameters per token and a 1M-token context. It matches or beats models several times its size on agentic coding benchmarks, ships under OpenMDW-1.1, and runs on a single NVIDIA DGX Spark.

Google Releases Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber:...
Google released Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber on July 21, 2026. The Flash tier gets cheaper and more token-efficient, with 3.6 Flash cutting output tokens 17% and dropping its output price to $7.50 per 1M. Flash-Lite runs at 350 tokens/sec, while gated Flash Cyber powers CodeMender for vulnerability finding. The flagship 3.5 Pro remains delayed.

Feyn AI Releases SQRL, a Text-to-SQL Model Family That Inspects the...
Feyn Labs has released SQRL, a family of text-to-SQL models that inspect a database with read-only probes before committing to a query. The flagship SQRL-35B-A3B reports 70.6% execution accuracy on BIRD Dev, edging Claude Opus 4.6, and distills into self-hostable 4B and 9B checkpoints.
Build an Agentic Event Venue Operator with MongoDB Atlas, Voyage, and...
Introduction
This tutorial starts where most agent demos stop: giving the agent persistent memory, operational context, and a place to write back what happened. An...

Moonshot AI Releases Kimi K3: A 2.8 Trillion Parameter Open MoE...
Moonshot AI released Kimi K3 on July 16, 2026. It is a 2.8-trillion-parameter open MoE model built on Kimi Delta Attention and Attention Residuals, activating 16 of 896 experts.

Soofi Consortium Releases Soofi S 30B-A3B: An Open Hybrid Mamba-Transformer MoE...
Soofi S 30B-A3B is an open Mamba-Transformer MoE model activating 3.2B of 31.6B parameters for German and English
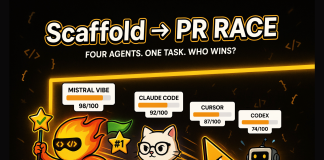
Mistral Vibe for Code vs Claude Code vs Cursor vs Codex:...
See how Vibe, Claude Code, Cursor, and Codex compare on cost, open weights, self-hosting, and async agent surfaces.
Ant Group’s Robbyant Unveils LingBot-VA 2.0: A Causal Video-Action Model Built...
Ant Group's Robbyant has released the LingBot-VA 2.0 technical report — a Physical AI video-action foundation model built from scratch for embodiment rather than fine-tuned from a video generator. It predicts future states ahead of execution through Foresight Reasoning, re-grounds on every real observation, and reaches 225 Hz asynchronous control. We break down the causal DiT, the sparse-MoE video stream, the semantic visual-action tokenizer, and where the paper's own numbers don't line up.

Meta Superintelligence Labs Releases Muse Spark 1.1: A Multimodal Reasoning Model...
Meta Superintelligence Labs released Muse Spark 1.1 on July 9, 2026, alongside a public preview of the Meta Model API. It is a multimodal reasoning model built for agentic tasks, with a 1,000,000-token context window the model actively compacts, zero-shot generalization to new tools and MCP servers, and multi-agent delegation across parallel subagents. Meta's own launch table shows it leading tool use while trailing Opus 4.8 and GPT-5.5 on coding.
Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for...
Ant Group's Robbyant has released LingBot-VLA 2.0, an Apache-2.0 vision-language-action model for cross-embodiment robot manipulation. The 6B checkpoint is pretrained on roughly 60,000 hours of data, spanning 50,000 hours of robot trajectories across 20 robot configurations and 10,000 hours of egocentric human video. It maps every embodiment into a single 55-dimensional canonical action space, covering arms, dexterous hands, waists, heads, and mobile bases. A token-level, auxiliary-loss-free Mixture-of-Experts action expert scales capacity without adding a load-balancing loss. Dual-query distillation from LingBot-Depth and DINO-Video adds geometric and temporal supervision for future-aware control. On the GM-100 generalist benchmark it outperforms π0.5 and LingBot-VLA-1.0 on both evaluated platforms.
SpaceXAI Releases Grok 4.5, a Cursor-Trained Model for Coding, Agentic Tasks,...
SpaceXAI released Grok 4.5, a Cursor-trained model for coding, agentic tasks, and knowledge work. It serves at 80 TPS, costs $2/$6 per million tokens, and ranks #1 on Harvey's Legal Agent Benchmark.
NVIDIA AI Introduces ASPIRE: A Self-Improving Robotics Framework Reaching 31% Zero-Shot...
NVIDIA's ASPIRE writes and refines robot control programs, then distills validated repairs into a reusable skill library. It gains up to 77 points on LIBERO-Pro and transfers zero-shot to unseen long-horizon tasks.
Mistral AI Releases Leanstral 1.5: An Apache-2.0 Lean 4 Code Agent...
Mistral AI released Leanstral 1.5, a free Apache-2.0 code agent model for Lean 4. It saturates miniF2F and solves 587 of 672 PutnamBench problems. The 119B mixture-of-experts activates 6.5B parameters per token. We break down its architecture, benchmarks, real bug-finding case studies, and deployment code.
Meet WebBrain: An Open-Source, Local-First AI Browser Agent That Reads Pages...
WebBrain is a free, MIT-licensed AI browser agent for Chrome and Firefox. It reads pages, extracts data, and automates multi-step tasks through Ask and Act modes. Run it on local models like llama.cpp or Ollama for privacy, or connect any cloud API.

Perplexity Launches Computer for Counsel: A Multi-Model Agentic Layer for Legal...
Perplexity's Computer for Counsel extends Perplexity Computer to legal teams. It routes 20+ models across Midpage, MCP connectors, and Microsoft 365, with cited outputs lawyers can verify.

16 Best Generative AI Coding Tools in 2026 Compared: Features, and...
Generative AI has reshaped how software gets built. What began as line-by-line autocomplete now spans full application generation, multi-agent build pipelines, and natural-language interfaces...
The 7 Types of Agent Memory: A Technical Guide for AI...
LLMs are stateless by default. Agent memory fixes that. This guide breaks down all 7 types — working, semantic, episodic, procedural, retrieval, parametric, and prospective. It covers what each stores, where it lives, and when to build it. Includes a comparison table and working Python code.
VibeThinker-3B: A 3B Dense Reasoning Model Built on Qwen2.5-Coder-3B With the...
VibeThinker-3B, a 3B MIT-licensed reasoning model matching DeepSeek V3.2 and Kimi K2.5 on verifiable benchmarks.
Sakana AI Commercializes AB-MCTS in Sakana Marlin, an Enterprise Agent Generating...
Sakana AI's first commercial product runs autonomously for up to eight hours per task. It returns multi-page reports and slides, built on AB-MCTS and AI Scientist workflows.
Zyphra Release Zamba2-VL: Hybrid Mamba2–Transformer Vision-Language Models That Cut Time-to-First-Token by...
Zyphra has released Zamba2-VL, a family of open vision-language models at 1.2B, 2.7B, and 7B parameters. The models use a hybrid Mamba2 state-space and Transformer backbone, shipping under Apache 2.0. They stay competitive with comparable Transformer VLMs while cutting time-to-first-token by about an order of magnitude.
Google AI Releases DiffusionGemma, a 26B MoE Open Model Using Text...
DiffusionGemma is Google DeepMind's experimental 26B open model using text diffusion for up to 4x faster generation on GPUs.
Top AI Coding Agents and Development Platforms in 2026: Atoms, Devin,...
Software development has changed. Engineers no longer type most code by hand. They describe intent, and AI agents do the work. Modern tools plan...
Anthropic Releases Claude Fable 5 and Claude Mythos 5: Same Underlying...
Claude Fable 5 ships generally available with classifiers; Mythos 5 stays limited, cyber safeguards lifted, through Project Glasswing.
A New Study from Harvard and Perplexity Finds AI Agents Perform...
A new Harvard and Perplexity paper uses matched-pair sessions to compare an autonomous agent with a search assistant. It finds large gains in autonomy, time, and cost, plus broader scope of work attempted.
Xiaomi MiMo and TileRT Push a 1-Trillion-Parameter Model Past 1000 Tokens...
Xiaomi's MiMo team, with TileRT, released MiMo-V2.5-Pro-UltraSpeed, a serving mode for the MiMo-V2.5-Pro model. It decodes over 1000 tokens per second on a 1-trillion-parameter model using a single 8-GPU commodity node.
Best 21 Low-Code and No-Code AI Tools in 2026
Low-code and no-code AI platforms now turn a prompt into a working app, agent, or model. This guide compares 21 tools across app builders, automation, AI agents, and machine learning platforms, each linked to its official site.
Google’s New Colab CLI Lets Developers and AI Agents Run Python...
Google released the Colab CLI, letting developers and AI agents run local code on remote Colab GPU and TPU runtime
Liquid AI Releases LFM2.5-8B-A1B: An On-Device MoE Model With 8.3B Total...
Liquid AI's LFM2.5-8B-A1B activates 1.5B of 8.3B parameters, offering 128K context, reasoning, and tool calling on consumer hardware.
Together AI Open-Sources OSCAR: An Attention-Aware 2-Bit KV Cache Quantization System...
Together AI has released OSCAR (Offline Spectral Covariance-Aware Rotation), an INT2 KV cache quantization method for long-context LLM serving. Unlike prior rotation-based approaches that apply data-oblivious Hadamard transforms, OSCAR derives separate rotations for keys and values from attention-aware covariance structures estimated offline. At 2.28 bits per KV element, OSCAR reduces the BF16 accuracy gap to 3.78 points on Qwen3-4B-Thinking-2507 and 1.42 points on Qwen3-8B, while delivering approximately 8× KV memory reduction and up to 3× decode speedup at 100K context length.
A Step-by-Step Coding Tutorial to Implement GBrain: The Self-Wiring Memory Layer...
AI agents start every session from zero — no memory of meetings, notes, or decisions. GBrain, the open-source memory layer Y Combinator's Garry Tan built to power his own OpenClaw and Hermes deployments, fixes that with a markdown-first knowledge graph that wires itself through regex inference, not LLM calls. This step-by-step coding tutorial walks through installing GBrain v0.38.2.0, building a brain repo, running hybrid search, and connecting it to Claude Code via MCP — about 20 minutes, all terminal output captured live.
One Model, Three Modalities: ByteDance Releases Lance for Image and Video...
ByteDance's Intelligent Creation Lab has released Lance, an open-source native unified multimodal model that handles image and video understanding, generation, and editing — all within a single framework, using only 3B activated parameters.
Meet Turbovec: A Rust Vector Index with Python Bindings, and Built...
turbovec brings Google Research's TurboQuant algorithm to vector search, offering 16x compression and zero codebook training for RAG pipelines.
Cline Releases Cline SDK: An Open-Source Agent Runtime Now Powering Its...
Cline has extracted its internal agent harness into an open-source TypeScript SDK called @cline/sdk, the same runtime now powering its CLI and Kanban, with VS Code and JetBrains extensions being migrated. The SDK is structured as a four-layer stack — @cline/shared, @cline/llms, @cline/agents, and @cline/core — with native support for plugins, subagents, CRON scheduling, checkpointing, and MCP connectors. On Terminal Benchmark 2.0, Cline CLI scored 74.2% on claude-opus-4.7, compared to Anthropic's published 69.4% for Claude Code on the same model. Install via npm install @cline/sdk. Requires Node.js 22+.
A Groq-Powered Agentic Research Assistant with LangGraph, Tool Calling, Sub-Agents, and...
In this tutorial, we build a Groq-powered agentic research workflow that runs directly using Groq’s free OpenAI-compatible inference endpoint
Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose,...
Meta Reality Labs releases a new foundation model family for human-centric vision that pushes pose estimation, segmentation, and 3D geometry to new state-of-the-art levels — all from a single backbone.
DeepSeek AI Releases DeepSeek-V4: Compressed Sparse Attention and Heavily Compressed Attention...
DeepSeek-AI has released a preview version of the DeepSeek-V4 series: two Mixture-of-Experts (MoE) language models built around one core challenge making one-million-token context windows...
Google DeepMind Introduces Decoupled DiLoCo: An Asynchronous Training Architecture Achieving 88%...
Training frontier AI models is, at its core, a coordination problem. Thousands of chips must communicate with each other continuously, synchronizing every gradient update...
Photon Releases Spectrum: An Open-Source TypeScript Framework that Deploys AI Agents...
For all the progress made in AI agent development over the past few years, one fundamental problem has remained largely unsolved: most people never...
Moonshot AI Releases Kimi K2.6 with Long-Horizon Coding, Agent Swarm Scaling...
Moonshot AI, the Chinese AI lab behind the Kimi assistant, today open-sourced Kimi K2.6 — a native multimodal agentic model that pushes the boundaries...
Top 19 AI Red Teaming Tools (2026): Secure Your ML Models
As Generative AI matures, so do the threats against it. AI Red Teaming has evolved from a niche security practice into a regulatory requirement. Our 2026 guide breaks down the top 19 tools—including Mindgard, Garak, and Microsoft’s PyRIT—to help security teams identify vulnerabilities like data leakage and bias before they reach production.
Google DeepMind Releases Gemini Robotics-ER 1.6: Bringing Enhanced Embodied Reasoning and...
Google DeepMind research team introduced Gemini Robotics-ER 1.6, a significant upgrade to its embodied reasoning model designed to serve as the 'cognitive brain' of...
TinyFish AI Releases Full Web Infrastructure Platform for AI Agents: Search,...
AI agents struggle with tasks that require interacting with the live web — fetching a competitor's pricing page, extracting structured data from a JavaScript-heavy...

NVIDIA and the University of Maryland Researchers Released Audio Flamingo Next...
Understanding audio has always been the multimodal frontier that lags behind vision. While image-language models have rapidly scaled toward real-world deployment, building open models...

A Hands-On Coding Tutorial for Microsoft VibeVoice Covering Speaker-Aware ASR, Real-Time...
In this tutorial, we explore Microsoft VibeVoice in Colab and build a complete hands-on workflow for both speech recognition and real-time speech synthesis. We...
Liquid AI Releases LFM2.5-VL-450M: a 450M-Parameter Vision-Language Model with Bounding Box...
Liquid AI just released LFM2.5-VL-450M, an updated version of its earlier LFM2-VL-450M vision-language model. The new release introduces bounding box prediction, improved instruction following,...
Alibaba’s Tongyi Lab Releases VimRAG: a Multimodal RAG Framework that Uses...
Retrieval-Augmented Generation (RAG) has become a standard technique for grounding large language models in external knowledge — but the moment you move beyond plain...
Meta AI Releases EUPE: A Compact Vision Encoder Family Under 100M...
Running powerful AI on your smartphone isn't just a hardware problem — it's a model architecture problem. Most state-of-the-art vision encoders are enormous, and...
Defeating the ‘Token Tax’: How Google Gemma 4, NVIDIA, and OpenClaw...
Run Google’s latest omni-capable open models faster on NVIDIA RTX AI PCs, from NVIDIA Jetson Orin Nano, GeForce RTX desktops to the new DGX...

Microsoft AI Releases Harrier-OSS-v1: A New Family of Multilingual Embedding Models...
Microsoft has announced the release of Harrier-OSS-v1, a family of three multilingual text embedding models designed to provide high-quality semantic representations across a wide...
NVIDIA AI Unveils ProRL Agent: A Decoupled Rollout-as-a-Service Infrastructure for Reinforcement...
NVIDIA researchers introduced ProRL AGENT, a scalable infrastructure designed for reinforcement learning (RL) training of multi-turn LLM agents. By adopting a 'Rollout-as-a-Service' philosophy, the...

Not Just Understanding, But Evolving: The All-New Self-Evolving JiuwenClaw Makes Its...
Over the past year, AI agents have evolved from merely answering questions to attempting to get real tasks done. However, a significant bottleneck has...

Tencent AI Open Sources Covo-Audio: A 7B Speech Language Model and...
Tencent AI Lab has released Covo-Audio, a 7B-parameter end-to-end Large Audio Language Model (LALM). The model is designed to unify speech processing and language...

Meet GitAgent: The Docker for AI Agents that is Finally Solving...
The current state of AI agent development is characterized by significant architectural fragmentation. Software devs building autonomous systems must generally commit to one of...