
Machine Learning
Breaking News
Context Engineering Inside the Harness: 4 Mechanisms That Beat Context Overflow...
A shallow agent is an LLM calling tools in a loop, and on long tasks it fails in 2 ways: context overflow and goal loss. This article opens the harness layer that fixes both, with the actual thresholds shipped by LangChain Deep Agents, Claude Code, Manus, OpenAI Codex and Amazon Bedrock AgentCore, plus an interactive simulator that shows a 200K window filling up.
Cognition Releases SWE-2: A Kimi K3 Post-Trained Coding Model That Matches...
Cognition, the company behind the Devin coding agent, has released SWE-2, its most capable coding model to date. SWE-2 is post-trained with reinforcement learning...
Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into...
The Fly Language Model (FLM) drives all 166,700 retained neurons and 25.6 million edges of the MaleCNS fruit fly connectome with token embeddings, then adds a small learned correction to a frozen LFM2.5-1.2B-Instruct backbone. Only 278,528 parameters train. The accompanying preprint reports a 0.0222 nat per token improvement over the backbone, but a parameter-matched control without the graph does slightly better in every seed. We break down the architecture, the four controls, the 0.6 per token memory bound, and what it takes to run the MIT-licensed code locally.
Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a...
Anthropic has published a new plugin evals workflow for Claude Code. The claude plugin eval command runs a plugin against realistic prompts, grades what...
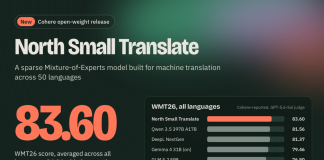
Cohere Releases North Small Translate: A 218B MoE Translation Model That...
Cohere has released North Small Translate, an open-weight Mixture-of-Experts model built for machine translation across 50 languages. It uses 25B of its 218B parameters per token and scores 83.6 on Cohere's WMT26 evaluation. Weights are free for non-commercial use, with commercial access through Cohere Model Vault or RWS Language Weaver.
Sakana AI Launches Fugu Max and Fugu Ultra v2 for Cheaper,...
Sakana AI has released Fugu Max and Fugu Ultra v2, 2 models built on the same learned orchestration architecture. Fugu Max routes tasks to lean open and specialized models, including NVIDIA Nemotron, at $2/$6 per 1M tokens. Fugu Ultra v2 targets peak capability, scoring 48.3 on Chartography and 74.3 on DeepSWE.
Google Research Releases ToolGrad: Answer-First Framework Hits 99.8% Pass Rate for...
Google Research has released ToolGrad, an ACL 2026 Findings framework that inverts tool-use dataset generation: it builds a verified API chain first, then writes the matching user query. Guided by textual "gradients" from a 4-module propose-execute-select-update loop, ToolGrad reaches a 99.8% pass rate on ToolBench versus 63.8% for DFS search. Gemma-3-12B fine-tuned on only 500 samples scores 83.1 on BFCL, next to Gemini 2.5 Pro at 83.2. Code, dataset, and models are public under Apache-2.0.

DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and...
Long-horizon agents have turned LLM serving into an input-heavy workload. Repeated prefills and million-token contexts leave KV caches that strain HBM, SSD capacity, and...
NVIDIA Announces CUDA Rust with cuda-oxide (SIMT) and cutile-rs (Tile) for...
NVIDIA has announced CUDA Rust, a push to make Rust a first-class language for GPU kernels. Two open-source NVlabs projects cover the two CUDA programming models: cuda-oxide compiles SIMT kernels from Rust MIR through Pliron and LLVM to PTX, while cutile-rs JIT-compiles Tile kernels through CUDA Tile IR on stable Rust 1.89+.

Google DeepMind Releases AlphaGenome Atlas With Precomputed Molecular Effect Predictions and...
DeepMind's AlphaGenome Atlas maps every single-letter change in the human genome with 1 impact score per variant.

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts...
We look at r-1, the document parsing model Reducto released on September 1, 2026. We walk through how it folds OCR, layout detection, tables, formatting and grounding into one full page pass, replacing the multi stage agentic pipeline it ships alongside. We break down the two numbers that matter for a migration decision: a reported 20% error reduction and a flat 1 cent per page rate against the legacy 3 to 6 cents.

OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34...
OpenBMB has released MiniCPM5-2B, a dense causal language model with 2,516,756,480 parameters and a native 131,072 token context. It averages 53.9 across the 34 benchmarks in its model card, ahead of Qwen3.5-4B at 51.1, with its clearest leads in tool use, coding agents and long-context retrieval. Post-training pairs 400B tokens of deep-thinking SFT with RL teachers and on-policy distillation that merges 16 expert models into one checkpoint. The weights ship under Apache 2.0 alongside the pre-training, SFT and RL datasets and the intermediate Base, Midtrain and SFT-only checkpoints. GGUF builds start at 1.56 GB, and the standard LlamaForCausalLM architecture loads in vLLM, SGLang, llama.cpp, Ollama and MLX without a model-code fork.
Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot...
Robot datasets have grown far slower than the models trained on them, mostly because collection stays locked to lab hardware. AXIS moves demonstration collection into a web browser and pushes everything expensive to backend GPUs. The result is 207 tasks and 50,129 verified Franka trajectories, and continual pretraining that lifts π0.5 from 83.9 to 88.8 on LIBERO-Plus while a volume-matched RoboCasa365 control reaches only 57.5.

IFM Releases K2 Horizon: Six Apache 2.0 Models From 0.9B to...
Most open model launches release one checkpoint and a benchmark table. The Institute of Foundation Models (IFM) released something wider last week. IFM is...

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower...
We look at NeoMME, a family of 260M and 800M bidirectional encoders from H Company. Unlike ColPali-style retrievers, it processes multilingual text tokens and raw 32×32 image patches in a single Transformer, with no pretrained vision tower and no causal decoder. We cover the masked discrete-diffusion pretraining objective, the dual dense and late-interaction retrieval heads, and the ViDoRe v3 results where the 260M model reaches 0.523 nDCG@10. We also break down the 255× index compression, the 51.3 pages per second indexing throughput on one L40S, and the text-retrieval gaps the authors acknowledge.

Meta FAIR Introduces AI Research Preference Models (RPMs): Ranking ML Experiments...
AI research agents can propose far more experiments than they can afford to run. Meta FAIR, Oxford and UCL introduce AI Research Preference Models — frozen LLM judges that rank 15 unexecuted candidates and execute only one. On AIRS-Bench, the average normalized score rises from 0.684 to 0.729, and the baseline's 24-hour result arrives in roughly 15 hours.
UC Berkeley Researchers Release CUA-Lite, an Open Platform Unifying Sandboxes, Data,...
Training and benchmarking a computer-use agent needs four things — agents, environments, traces, and a framework to evaluate and train them — and all four ship in incompatible formats today. CUA-Lite, from a UC Berkeley led team, puts them behind one action space and one data schema, and replaces OSWorld's per-task virtual machine with a plain Docker container at 0.9 GB instead of 4.1 GB.

Google Launches Agentic Video Understanding for Gemini Flash Models, Cutting Video...
Gemini now navigates video instead of ingesting it at 1 FPS, loading only the segments a prompt needs.

NVIDIA Releases Personal AI Router (PAIR): An Open Source Virtual Inference...
We look at NVIDIA Personal AI Router (PAIR), an open source virtual inference router that spreads local AI requests across the machines already on a home network. We cover how PAIR proxies existing Ollama and LM Studio endpoints so agent harnesses need no changes, and how its scheduler filters nodes on readiness, engine state, exact model presence, job load, and GPU utilization. We walk through NVIDIA's five-subagent demonstration, which averaged 18 minutes on one RTX Spark laptop against 8 minutes 48 seconds on a three-device cluster, and note why NVIDIA labels it unofficial rather than a benchmark. We also cover where PAIR will not help, including its single scheduling policy and its blindness to VRAM and model warmness.
Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver...
WeatherNext 3 ingests live geostationary satellite mosaics, refreshes hourly, and outputs 5 km forecasts across Search, Gemini, Maps.

OpenAI Releases GPT-6 Astra: A 1.05M-Context Computer-Use Model Gated Behind a...
OpenAI released GPT-6 Astra on September 3, 2026, positioning it as a computer-use flagship rather than a chat model. It reports 72.6% on OSWorld V2-Offline, replaces Codex compaction with searchable notes, and ships a 1.05M-token context at $10/$50 per million tokens. It is also the first OpenAI model to cross the Critical cybersecurity threshold, which shapes who can use it and for what.
Meta AI Released Muse Spark 1.3: An Agentic Coding Model That...
Perplexity has shipped hybrid compute for its Mac app, splitting a single Perplexity Computer task between frontier models in the cloud and a compact model running on the user's machine. Tasks start in the cloud for search, planning and reasoning, then hand sensitive steps down to the Mac without restarting or losing context. An on-device privacy gate decides what may cross: keep local, mask, refuse, or ask for consent. Perplexity also open-sourced the 0.6B classifier behind that gate, which records the highest character F1 (0.629) among twelve detectors evaluated. Hybrid compute is live now for Pro, Max and Enterprise on Apple silicon Macs with 24GB of unified memory.

Perplexity Open Sources Lily: A Rust + Metal Inference Engine for...
Perplexity has open sourced Lily, the local inference engine behind Hybrid Compute in Perplexity Computer. Built in Rust with custom Metal kernels for one model on one chip family, it averages 1.23x MLX-LM's prefill throughput and 1.35x its decode throughput on a 40-core, 128 GB M5 Max.
Qwen Developers Open-Sources zg (zvec-grep): A Local-First Search Layer Unifying ripgrep,...
We look at zg (zvec-grep), the local-first search layer that Qwen Developers just open-sourced under Apache 2.0. We explain how it puts ripgrep, BM25, and vector search behind a single interface, so an agent can move from a plain-language description to an exact line span without switching tools. We cover the deliberately small MCP surface, the on-device embedding catalog, and the authorization gate that stands between local content and remote models.
Meet Switchyard: A Rust Proxy and Library That Routes and Translates...
NVIDIA has released Switchyard, an Apache-2.0 Rust proxy and library for LLM traffic. It decodes requests into provider-neutral types, routes them with passthrough, random, LLM-classifier, or stage-router algorithms, and translates responses back into the client's format, so Claude Code or Codex CLI can run against vLLM, NIM, or Ollama unchanged. The project is pre-alpha and not for production.

Google DeepMind Releases Gemini 3.8 Flash and Gemini 3.8 Flash Cyber:...
Google released Gemini 3.8 Flash and Gemini 3.8 Flash Cyber on September 2, 2026. Both variants run on the same foundational intelligence, split by safety mitigations rather than model size. Gemini 3.8 Flash is generally available at $0.75 and $3.75 per 1M tokens, introductory through December 31, 2026. Flash Cyber reaches 47.2% pass@1 on CWE-Bench and is restricted to vetted defenders through the Fairwind Program. This article covers the benchmarks, the token-for-accuracy tradeoff, and what deploying either one actually requires.
Perplexity Releases Hybrid Compute on Mac: Cloud Agents Orchestrate Down to...
Agentic assistants have a structural problem: the context that makes them useful — deal documents, privileged files, client records — is exactly the context...

Researchers from Princeton, Ant Group and Stanford Introduce AQuA: A Two-Part...
Quantitative research agents that write their own experiments can corrupt the evidence they later learn from. A leaky feature that scores well gets stored...
Google AI Releases TimesFM-3: A 330M Parameter Zero-Shot Foundation Model For...
Google Research has released TimesFM-3, a 330 million parameter time series foundation model that forecasts multiple related series in a single forward pass. Unlike every TimesFM checkpoint through 2.5, it is pretrained natively for multivariate forecasting, accepting multiple targets, past covariates, and past-future covariates with no task-specific fine-tuning. It takes the top average rank among pretrained foundation models on GIFT-Eval, fev-bench, and the TIME leaderboard. The weights, however, ship under a non-commercial, non-production license.
OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI...
The OpenClaw Foundation has released v2026.8.1, which the project calls OpenClaw 2.0: 933 contributors, 569 first-timers, and more than 16,000 pull requests, roughly half of every PR ever merged into the repo. Setup now reuses existing subscriptions, API keys and local models. The rebuilt Control UI cut test-harness startup from about 1.6 seconds to 575 ms. Shared cloud sessions add real multiplayer, though the docs are explicit that they are not a security boundary.

Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent...
Google Cloud AI Research, with Washington University in St. Louis and UNC Chapel Hill, has released EnvHarness, an Apache-2.0 layer that turns a static agent benchmark into one that adapts to the policy training on it. It wraps a frozen environment through the standard reset()/step() interface, so tasks and human-built verifiers stay untouched — and an LLM designer, EnvRigger, writes those wrappers automatically against flaws diagnosed in the agent's own rollouts. Across five benchmarks, mined skills gain up to 9.0 points on held-out tasks with 9.8% fewer execution steps.
Anthropic Opens a Research Preview of the Model Hardware Standard (MHS):...
Anthropic has opened a research preview of the Model Hardware Standard (MHS), a shared driver specification that lets AI agents discover and safely operate physical devices. Instrument integration that normally takes weeks or months drops to hours: Carnegie Mellon went from raw equipment to a finished dose-response curve in eight, and QuEra's laser relock improved from 58% to 99.3% across 700 trials. MHS is model-agnostic, reachable over MCP, and enforces safety limits in the driver rather than the prompt.

Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable...
Code-as-World recovers editable MuJoCo scene code from real video, then uses those verified worlds to train physical reasoning.

GLM-5.3-Flash vs Qwen3.8-Flash-Next: Two Chinese AI Labs Independently Converge on the...
Z.ai and Qwen independently shipped near-identical architectures: 3:1 linear hybrids, compressed indexers, gated residuals, and Muon training.
Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent...
Vercel has open-sourced vgpu, the WebGPU library it built to ship the shaders on vercel.com. It treats .wgsl files as importable TypeScript modules, runs the same shader in the browser, in headless Node.js via Dawn, and in a deterministic CI mock, and ships a fullscreen effect in 25 KB gzipped.

From In-Silico to Wet-Lab: Evaluating AI Protein Design Performance
In this tutorial, we analyze Anthropic’s 1,440 AI-designed protein binder dataset to benchmark 10 leading structure predictors. Discover how target identity, expression titers, and consensus scoring impact experimental success and learn best practices for rigorous cross-validation in protein design workflows

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous...
Google Research and UNSW Sydney released GlucoFM, a self-supervised foundation model that splits a CGM trace into a slow physiological stream and a transient event stream instead of encoding it as one sequence. At 0.72M parameters it reached 58.8 task-averaged PR-AUC across 14 cohort–task evaluations, beating a 135M GluFormer and a 385M MOMENT. It remains a research prototype with no regulatory clearance.

Z.ai Releases GLM-5.3-Flash: A 320B-A18B Natively Multimodal MoE With a 1M-Token...
Z.ai has released GLM-5.3-Flash, the first natively multimodal model in the GLM-5 series — a 320B-total / 18B-active MoE with a 1,048,576-token context window, MIT-licensed weights on Hugging Face, and API pricing at $0.15/M input and $0.50/M output. It scores 84.3 on Terminal-Bench 2.1 and 63.4 on DeepSWE v1.1, using hybrid KDA linear plus NoPE sparse MLA attention to cut attention compute ~3× and KV cache 4.4× versus GLM-5.3.

Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B...
We look at Qwen3.8-Flash-Next, Alibaba's open-weight multimodal Mixture-of-Experts model and an early preview of the Qwen4 architecture. We break down where the 180B parameters actually sit: a 125B backbone, a 51B N-gram embedding table, and a 4B multi-token prediction module, with only 6B active per token. We walk through the four architectural changes — the Gated DeltaNet and Qwen Sparse Attention hybrid, Gated Residual, N-gram Embedding, and the Muon optimizer. We also cover the benchmark results, the reported 1/9 training cost against Qwen3.7-Plus, and what self-hosting a 172.78 GiB FP8 checkpoint really demands.

IBM Releases Granite 4.2: Bringing Native Reasoning and Agentic RL to...
IBM has released Granite 4.2, a family of open reasoning language models in 3B, 8B, and 30B sizes, all under Apache 2.0. Every model exposes a thinking / low-effort / non-thinking switch and native tool calling. The 8B and 30B additionally go through an agentic RL block that trains them to edit code, drive a terminal, and run web searches inside real sandboxed environments. The 30B reports 57.00 on SWE-Bench Verified and 29.24 on Terminal-Bench 2.1.

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device...
Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI...

Perplexity Ships Portable Computer on NVIDIA DGX Spark: Local Harness, OS-Enforced...
Perplexity releases Portable Computer, packaging local models, harness, sandbox, and connectors into one system running on NVIDIA DGX Spark.

Fastino Releases GLiNER2.5: A Boundary-Prediction Architecture That Removes Span Enumeration From...
Fastino released GLiNER2.5, replacing span enumeration with boundary prediction so entity width no longer costs compute. Three Apache 2.0 checkpoints ship at 74M, 194M, and 287M parameters, all CPU-runnable. The release adds joint entity-relation decoding, constrained classification, span attributes, and 4,096-word context. Overall macro F1 reaches 56.17 on 16 zero-shot benchmarks.
Scientific Data Analysis with LabPlot in Python: Signal Processing, Spectral Peak...
In this tutorial, we explore a LabPlot-inspired scientific data analysis workflow in Python while preserving the structure and terminology of LabPlot’s aspect tree, analysis...

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks...
Harvey's first post-trained model nearly doubles LAB task completion, but only one benchmark number survives independent verification today

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2...
FreeToken splits MoE cache misses between PCIe fills and CPU execution using measured bandwidths, unlocking frontier models locally

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x...
Three ~300M drafters bring speculative decoding to LFM2.5, delivering up to 3.18x faster decoding with identical greedy output.

Meet SAM (Sovereign Agent Mesh): A Zero-Config, Zero-Trust P2P Network for...
Google has open-sourced SAM (Sovereign Agent Mesh) under Apache-2.0 — and it has nothing to do with Segment Anything. SAM is a zero-config, zero-trust P2P overlay that lets autonomous agents discover and call each other's MCP tools across cloud, on-prem, laptop and edge environments, without exposing a single internal endpoint to the public internet. Identity flows from OIDC into Biscuit capability tokens, so nodes authorize every request offline under a strict default-deny model.

Z.ai Ships GLM-5.3 Without Retraining the Base Model: Better at Complex...
Z.ai released GLM-5.3 on August 14, 2026. The model reuses the 743B GLM-5.2 base unchanged. Every reported gain comes from scaled post-training: more long-horizon task environments, more environment types, longer training. Terminal-Bench 3.0 moves from 4.6 to 28.3, and DeepSWE v1.1 from 46.2 to 66.9. Cybersecurity moved further than Z.ai says it planned, with CyberGym at 84.5% and ExploitBench more than doubling to 54.4%. Weights arrive in about two weeks.
Meet Needle 2: An Open 45M-Parameter Tool-Calling Model That Ships as...
Cactus Compute released Needle 2, an open 45M-parameter model for tool calling, device use, and structured extraction. The full model is a single 14MB binary that runs a session in about 28MB of RAM. It leads both Seal-Tools splits while targeting hardware with no GPU and no NPU.

Google AI Just Released Gemini 3.7 Flash: A Coding and Agent...
Google has released Gemini 3.7 Flash, a refinement of Gemini 3.6 Flash with algorithmic improvements to its reasoning core. It handles text, images, audio, and video across a 1M-token context window with 64K-token output, and supports customizable thinking configurations. Coding results move notably: 43.6% on FrontierCode 1.1 Main versus 34.4%, 65.3% on DeepSWE v1.1, and 1588 Elo on WebDev Arena. Document and workflow evals gain more — GDP.pdf goes from 22.0% to 34.0%, AutomationBench from 17.0% to 30.4%. GPT-5.6 Terra still leads on terminal and computer-use agents. The model is API and enterprise only, with no open weights, at an introductory $0.75/$3.75 per 1M tokens through December 31, 2026.

Dyna Robotics Introduces Dyna-2: A World-Action Model Pre-Trained on 1 Million...
Dyna Robotics has released Dyna-2, a world-action model pre-trained on more than one million hours of egocentric human video. The technical report establishes three results: a scaling law on human data to 1M hours, the first transfer of that law to unseen robot data, and evidence that video co-training drives cross-embodiment generalization.

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with...
NVIDIA's open 30B MoE targets the agent execution layer, with Switchyard routing each step to the cheapest capable model.
The Video Production Stack Now Fits on One Desk: LTX-2.5 Launches...
LTX-2.5 brings frontier video generation to local NVIDIA hardware: 6.8-second clips, native multishot, day-one ComfyUI, open weights.

webAI Releases TwIL-LM: A 1.7B and 3B Formal-Logic Model Family for...
webAI has released TwIL-LM, a family of formal-logic models at 1.7B and 3B parameters that translate English into first-order logic and check whether conclusions follow from premises. The 3B runs on CPU or 4GB of VRAM; the 1.7B downloads at 1.06GB. Both ship under a non-commercial license. The model card also shows that the headline benchmark scores belong to an unreleased checkpoint, not the weights on the Hub.
Implementing a MiniMax-H3 Multimodal Video and Audio Generation Pipeline with ComfyUI...
In this comprehensive guide, we demonstrate how to implement a complete, programmable MiniMax-H3 multimodal generation pipeline. By leveraging ComfyUI as a headless backend, we walk through setting up an automated inference environment that handles hardware profiling, model weight downloading, dynamic graph construction, and joint video-audio decoding.
Meta AI Releases Muse Glimmer: A 30B Open-Weights Agentic Model That...
Meta's Muse Glimmer is a 30B open-weights agentic model under Apache 2.0. It fits 24 GB VRAM and decodes 3.1x faster with DFlash speculation.

ByteDance Seed Introduces SeedRealtime: a Native Audio-Visual Full-Duplex LLM That Watches,...
ByteDance's Seed team has introduced SeedRealtime, a native audio-visual full-duplex LLM. The model fuses audio, video and text in a single unified architecture. It...
NVIDIA Releases NemotronLabs VoiceChat 11B: An Open Full-Duplex Speech-to-Speech Model with...
NVIDIA releases NemotronLabs VoiceChat 11B, an open full-duplex speech-to-speech model with 448 ms latency and live tool calling.
IMDb Sentiment Analysis with DistilBERT LoRA, TF-IDF Baselines, Calibration, Interpretability, Robustness...
This tutorial provides a comprehensive guide to building a robust sentiment analysis workflow. By combining classical TF-IDF baselines with modern parameter-efficient fine-tuning (DistilBERT + LoRA), we explore deep model interpretability, calibration, and semi-supervised techniques to achieve scalable sentiment inference
Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety...
Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that frames content moderation as a single yes/no question instead of a fixed harm taxonomy. Operators supply the policy as a plain-language query at inference time and get back a calibrated safety score from one forward pass — no retraining required to re-target the model. Built on Ministral-3-3B-Base-2512 with a Pixtral vision encoder and trained on roughly 54.1M samples, it reports 84.9% average F1 on text safety (matching GPT-OSS-Safeguard-20B), 83.8% on multimodal safety, and 91.3% on Mistral's adaptability benchmark — while fitting in 16GB of VRAM under an Apache 2.0 license.
NVIDIA AI Releases NOOA: An Object-Oriented Python Framework That Turns an...
NVIDIA Labs has open-sourced NOOA (NVIDIA Object-Oriented Agents), a model-agnostic Python framework for building AI agents. Agent development today is split across prompt templates,...
Meta AI Releases Muse Code (Beta): A Terminal Coding Agent Powered...
Meta Superintelligence Labs has released Muse Code, a terminal coding agent in beta, powered by the new Muse Spark 1.2 model. Muse Code plans changes, writes code, and validates results across large repositories. Async background agents stay active for the whole session instead of spawning per task. A local append-only event log makes the runtime replay-exact and restart-safe after a crash. Muse Spark 1.2 was co-trained with the harness and trained on long-horizon, repository-scale work.
NVIDIA Releases Alpamayo 2 Super: A 34B Open Vision-Language-Action Model for...
NVIDIA released Alpamayo 2 Super, a 34B vision-language-action model for autonomous driving, under OpenMDW-1.1 — a permissive license covering fine-tuning, derivatives and commercial redistribution. It pairs a 32B Cosmos 3 Super Reasoner backbone with a 2.3B diffusion action decoder, scores 79.2 on LingoQA, and emits trajectories, Chain-of-Causation traces, meta-actions, auto-labels and grounded VQA from a single pass.
CopilotKit Open Sources Channels SDK: An MIT Licensed Library That Runs...
CopilotKit has published the Channels SDK, an MIT licensed library that runs an existing AG-UI agent inside Slack and Microsoft Teams. Version 0.5.0 ships five platform adapters and a documented runtime contract. This breakdown covers the verified deployment paths, the baseline requirements, and the one dependency that is easy to miss

Cursor Open-Sources Mixture-of-Kittens (MoK): A Deterministic MoE Training Megakernel for GB300...
Cursor Research has open-sourced Mixture-of-Kittens (MoK), the MoE training megakernel behind its Composer models. MoK fuses all mixture-of-experts communication and computation into a single deterministic kernel, and runs up to 2.37x faster than the strongest public baseline on GB300 NVL72 racks. It requires Blackwell SM100 or SM103 GPUs, which puts it out of reach for anyone without NVL72 capacity.
Reflex Open Sources XY: A Rust-Backed Super-Fast Python Charting Library That...
Reflex has released XY, an Apache-2.0 Python charting library that moves rendering work into a native Rust core and a WebGL2 client. It holds roughly 0.08 seconds render time from 10,000 to 100 million points, exports a 10-million-point interactive scatter at 258 KiB, and keeps exact f64 columns in Python so hover, selection, and zoom drilldown still return original rows. The library is early alpha at version 0.0.1.
Y Combinator Open-Sources QM: An MIT-Licensed Multiplayer Agent Harness That Runs...
Y Combinator has open-sourced QM, the multiplayer agent harness it uses internally across accounting, legal, events, and engineering. Released July 31, 2026 under an MIT license, QM gives each employee an isolated workspace and each Slack room its own scoped memory, files, keychain view, permissions, crons, web apps, and durable sandbox. Pi, OpenCode, Codex, and Claude Code all drive the same headless core, so deployments avoid vendor lock-in.
Genspark Open Sources GenOffice: A Free, Ad-Free AI Office Suite for...
Genspark has open sourced GenOffice under the Apache License 2.0. It is an AI-native office suite for macOS and Windows, covering Docs, Sheets, Slides and PDF as five Electron apps over one shared engine layer. The notable engineering claim is a byte-preserving round trip: only edited paragraphs are regenerated as OOXML and spliced back into the original file, so untouched blocks keep their original bytes and layout survives in Word. Sheets pairs the open-source Univer core with an in-house Rust xlsx sidecar. AI calls route through a signed-in Genspark account and consume credits. The repository labels this an Alpha.

How to Secure AI Agents, MCP Servers, and LLM Apps in...
AI agents, MCP servers, and LLM apps break the core AppSec assumption that applications do what their code says. This guide walks through a practical see-fix-protect framework: a five-layer agentic AI attack surface map, a 12-point misconfiguration checklist, an evidence-based triage matrix, runtime guardrails, and system prompt hardening — plus a maturity self-assessment aligned to NIST AI RMF, OWASP AIMA, ISO/IEC 42001, and the EU AI Act.

Alibaba Qwen Releases Qwen3.8-Max: A 2.4 Trillion Parameter MoE Model and...
Alibaba's Qwen team moved Qwen3.8-Max from preview to general availability, with published per-token pricing and open weights due next week. The 2.4T parameter MoE model accepts text, image and video input across a 1M-token context. No benchmark table has been published.
End-to-End Forecasting with TimesFM 2.5: Backtesting, Covariates, Anomaly Detection, and Scalable...
In this tutorial, we build an advanced end-to-end time-series forecasting workflow with TimesFM 2.5. We begin by configuring the runtime, installing the required dependencies,...
AMD Releases Instella-MoE-16B-A3B: A Fully Open Mixture-of-Experts LLM With 2.8B Active...
AMD released Instella-MoE-16B-A3B, a fully open Mixture-of-Experts language model trained from scratch on Instinct MI300X and MI325X GPUs. It holds 16B total parameters but activates only 2.8B per token, using Gated MLA and FarSkip-Collective. AMD published weights from every training stage, plus data mixtures, configs, and inference code.
Accelerating Transformer Training with NVIDIA Transformer Engine, Fused Kernels, BF16, FP8,...
Discover how to optimize transformer workloads using the NVIDIA Transformer Engine. This tutorial guides you through configuring fused GPU kernels, implementing FP8 delayed scaling, and benchmarking model performance. Learn to build and train efficient GPT-style causal language models in PyTorch with practical code examples and performance analysis.
Supabase Releases Evals: an Open Source Benchmark That Scores Claude Code,...
Supabase has open sourced supabase/evals, an Apache-2.0 benchmark and framework that runs coding agents including Claude Code, Codex and OpenCode against real Supabase tasks — building schemas, debugging Edge Functions, fixing RLS policies — inside containerized stacks, then scores them with deterministic checks and LLM-as-a-judge.

MiniMax Releases MiniMax H3: An Omni-Modal Video Model That Generates 15-Second...
MiniMax releases MiniMax H3, a general-purpose multimodal generation model. MiniMax H3 is not a text-to-video model with add-ons. MiniMax describes it as a general-purpose...

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains
DeepSeek published DeepSeek-V4-Flash-0731 on Hugging Face and moved the official V4-Flash API into public beta on July 31, 2026. The model card is explicit...

Building a Policy-Governed Multi-Agent Financial Research Workflow with Omnigent
In this tutorial, we demonstrate how to build and execute a multi-agent workflow with Omnigent in a secure, isolated Python environment. Learn to integrate live exchange-rate data, implement hierarchical agent delegation for financial text auditing, and apply hard governance policies—such as cost budgets and tool call limits—to your research pipeline directly from Google Colab.
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG...
Marktechpost AI has released Token Saver, an open-source MCP extension for Claude Desktop that uses local Hybrid RAG to slash PDF token consumption by up to 99% while ensuring absolute document privacy.

Prompt Engineering vs Loop Engineering vs Graph Engineering: What Changes at...
Three terms now compete for the same line in AI engineering job descriptions. Prompt engineering is the established one. Loop engineering entered the AI...
Liquid AI Releases LFM2.5-Encoder-230M and LFM2.5-Encoder-350M: Bidirectional Encoders That Stay Fast...
Liquid AI released two open-weight bidirectional encoders, LFM2.5-Encoder-230M and LFM2.5-Encoder-350M. Both carry an 8,192-token context and are built on the LFM2 hybrid backbone. The 350M ranks fourth of 14 models on a 17-task GLUE, SuperGLUE, and multilingual suite, behind only larger models. The 230M clears one 8K-token forward pass on CPU in about 28 seconds.
Kimi AI and kvcache-ai Open Sources ‘AgentENV’: A Distributed System that...
Moonshot AI's Kimi team and kvcache-ai open-sourced AgentENV (AENV) under MIT, as part of Kimi K3 Open Day. It runs agent sandboxes as Firecracker microVMs with millisecond snapshot, resume, and 16-way fork, behind an E2B-compatible API.

KwaiKAT Team Releases KAT-Coder-V2.5: An Agentic Coding Model Trained on 100,000+...
The KwaiKAT Team at Kuaishou has published the KAT-Coder-V2.5 technical report, arguing that agentic coding capability is bottlenecked by training infrastructure rather than model scale. AutoBuilder raised environment construction success from 16.5% to 57.2%, producing over 100,000 verifiable environments across 12 languages, while a sandbox audit cut RL feedback errors from roughly 16% to below 2%.
FAIRChem v2 UMA for Multidomain Atomistic Simulation across Molecules, Catalysts, Materials,...
In this tutorial, we explore FAIRChem v2 and the UMA universal machine-learning interatomic potential as a unified framework for atomistic simulation across molecular chemistry,...

Sakana AI Releases Fugu-Cyber: An Orchestration Model Reporting 86.9% on CyberGym...
Sakana AI has released Fugu-Cyber, a security-tuned endpoint on its Fugu orchestration model. It reports 86.9% on CyberGym and 72.1% on CTI-REALM, edging past GPT-5.5-Cyber and Claude Mythos Preview. Access is gated behind manual approval, a defensive-use policy, and the Token Plan. Here is what the numbers actually mean.

Meet Open Dreamer: A JAX/Flax Reproduction of the Dreamer 4 World...
A small group of AI researchers (Francesco Sacco, Diego Martí, and Edward Hu) have released Open Dreamer, an open implementation of the Dreamer 4...
Datalab Marker v2 vs MinerU, Docling, and Liteparse: Benchmark Breakdown
Datalab rewrote Marker as a three-mode pipeline. Version 2 hits 76.0 on olmOCR-bench and sustains 2.9 pages per second on one B200 — over 5× MinerU's pipeline backend, while beating Docling on both accuracy and speed. Here's how it compares against MinerU, Docling and LiteParse, and which one fits your use case.

Meet the New Claude Opus 5: Frontier-Class Agentic Coding and Computer...
Today, Anthropic released Claude Opus 5. It replaces Claude Opus 4.8 as the Opus-tier flagship. Pricing is unchanged at $5 per million input tokens...
How to Build an End-to-End OCR Pipeline with Baidu’s Unlimited-OCR for...
In this tutorial, we build a complete workflow for running Baidu’s Unlimited-OCR model on document images and multi-page PDFs. From configuring the GPU environment to comparing high-detail tiled Gundam inference and faster Base modes, you'll learn how to process dense layouts, tables, and cross-page content in a reproducible, end-to-end pipeline.

You Didn’t Get the AI Model You Paid For
The line in the response object
You call the API. You pass model: "claude-fable-5". You get back a completion, a token count, and a field...

Meet Gigatoken: A Rust BPE Tokenizer that Encodes Text at 24.53...
Gigatoken is an MIT-licensed Rust BPE tokenizer that encodes text at gigabytes per second. On a 144-core AMD EPYC 9565, it runs GPT-2 tokenization at 24.53 GB/s. That is 989x HuggingFace tokenizers and 681x tiktoken, against baselines already written in multithreaded Rust. The gains come from a hand-written SWAR pretokenizer and pretoken caching, not a faster BPE merge loop.

Unsloth vs Axolotl vs TRL vs LLaMA-Factory: A Fine-Tuning Framework Comparison...
Four open source projects dominate LLM fine-tuning today. Unsloth, Axolotl, TRL, and LLaMA-Factory all wrap the same underlying PyTorch and Hugging Face stack. They...
Cisco Foundation AI Releases Antares: 350M and 1B Open-Weight Models That...
Cisco Foundation AI has released Antares, a family of small language models trained to pinpoint where known vulnerabilities live inside a codebase. Antares-1B reaches 0.209 File F1 on the new Vulnerability Localization Benchmark, above GLM-5.2 at 753B parameters and Gemini 3 Pro. The untrained Granite 4.0 checkpoints score near zero under the same protocol, so post-training supplies almost all of the capability. A full 500-task sweep runs in roughly 13 minutes on a single H100 for under a dollar, against $141 for GPT-5.5.

Google Releases Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber:...
Google released Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber on July 21, 2026. The Flash tier gets cheaper and more token-efficient, with 3.6 Flash cutting output tokens 17% and dropping its output price to $7.50 per 1M. Flash-Lite runs at 350 tokens/sec, while gated Flash Cyber powers CodeMender for vulnerability finding. The flagship 3.5 Pro remains delayed.

Someone Fine-Tuned OpenBMB’s MiniCPM5-1B on Claude Fable 5 Traces to Ship...
A community developer fine-tuned OpenBMB's MiniCPM5-1B on Claude Fable 5 traces into a 1B model that runs fully local — a 657MB smallest build, 128K context, and visible reasoning. We verify every spec against the Hugging Face cards, separate what a fine-tune actually inherits from real capability, and flag the licensing question the model card leaves open.

Best Local LLMs You Can Run on a Single 24GB GPU...
A single 24GB GPU is the practical floor for serious local inference. This guide compares six open-weight models that fit one card at Q4_K_M. It covers Qwen3.6, Gemma 4, Mistral Small, gpt-oss-20b, and DeepSeek-R1-Distill. Each entry lists VRAM fit, licensing, and the job it does best.
Google Cloud’s Always-On Memory Agent Replaces RAG and Embeddings With Continuous...
Google Cloud's generative-ai repository ships the Always-On Memory Agent, a reference implementation that treats memory as a running process. Built on Google ADK and Gemini 3.1 Flash-Lite, it uses no vector database and no embeddings. Instead, an orchestrator routes to Ingest, Consolidate, and Query sub-agents that read, connect, and write structured memory into SQLite 24/7.

Sakana AI’s Error Diffusion Trains Dale-Compliant Dual-Stream Networks, Reaching 96.7% MNIST...
Backpropagation relies on weight transport, which biological circuits likely cannot implement. Sakana AI's Error Diffusion sidesteps that constraint, training dual-stream excitatory/inhibitory networks that obey Dale's principle. This piece breaks down how modulo error routing scales the rule from MNIST to CIFAR-10 and reinforcement learning, and what its task-dependent ablations reveal.
Zyphra Releases ZUNA1.1: An Apache 2.0 EEG Foundation Model With Variable-Length...
Zyphra released ZUNA1.1 on July 16, 2026, under the Apache 2.0 license. The 380M masked diffusion autoencoder reconstructs, denoises, and upsamples scalp-EEG across arbitrary channel layouts. It accepts variable-length inputs from 0.5 to 30 seconds, against ZUNA1's fixed five seconds. Reported NMSE holds or improves while the input range widens.
NVIDIA AI Releases Nemotron 3 Embed: An Open Embedding Collection Whose...
NVIDIA released Nemotron 3 Embed on July 15 and 16, 2026. The collection has three open checkpoints: Nemotron-3-Embed-8B-BF16, Nemotron-3-Embed-1B-BF16, and Nemotron-3-Embed-1B-NVFP4. The 8B ranks #1 on RTEB at 78.46 average NDCG@10. The 1B came from ModelOpt NAS pruning plus COS+MSE distillation from the 8B teacher. NVFP4 retains 99%+ of BF16 retrieval accuracy at up to 2x Blackwell throughput. All three run 32,768-token inputs under OpenMDW-1.1.