

OCR
Breaking News

Reducto Releases r-1: A Single Pass Document Parsing Model That Cuts...
We look at r-1, the document parsing model Reducto released on September 1, 2026. We walk through how it folds OCR, layout detection, tables, formatting and grounding into one full page pass, replacing the multi stage agentic pipeline it ships alongside. We break down the two numbers that matter for a migration decision: a reported 20% error reduction and a flat 1 cent per page rate against the legacy 3 to 6 cents.
Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That...
Cohere has released Parse (parse-v5.0), a 2.3B-parameter vision language model that converts PDFs, slides and images into Markdown with HTML tables, bounding boxes and image descriptions. It runs at $1.50 per 1,000 pages through the API, or on dedicated Model Vault instances from $2,500 a month. Cohere reports a ParseBench score of 79.2, ahead of Mistral OCR 4, Azure Document Intelligence and Databricks AI Parse — but that figure averages three of the benchmark's five dimensions and drops charts and visual grounding entirely.

Harvey Introduces Harvey Tenet: A Kimi K3 Base Post-Trained with Fireworks...
Harvey's first post-trained model nearly doubles LAB task completion, but only one benchmark number survives independent verification today

Building an End-to-End Document Intelligence Pipeline with deepDoctection
Build an end-to-end document intelligence pipeline with deepDoctection. This tutorial covers configuring layout analysis, DocTR OCR, and table extraction, while demonstrating how to implement custom services for entity recognition and generate structured JSONL data for your RAG workflows.

Building Agentic Document Intelligence Pipelines: Creating Scientific Figures with AutoFigure
This tutorial explores AutoFigure, a practical toolkit for generating professional scientific figures directly from text descriptions and research papers. We walk through setting up the environment, configuring an API-backed generation workflow, and converting complex document intelligence pipelines into publication-style diagrams, complete with custom reference styling and gallery exports.
Liquid AI Releases LFM2.5-VL-3B: A 3B Vision-Language Model That Reads Screens,...
Liquid AI released LFM2.5-VL-3B, a 3.1B-parameter vision-language model built for on-device deployment. It averages 80.7 on ScreenSpot-v2 and lifts RefCOCO grounding from 57.1 to 87.9. Function calling is new to the VL line, with ToolSandbox moving from 26.4 to 59.5. The model fits in roughly 3 GB and decodes 228 tokens/s on an Apple M5 Max.
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG...
Marktechpost AI has released Token Saver, an open-source MCP extension for Claude Desktop that uses local Hybrid RAG to slash PDF token consumption by up to 99% while ensuring absolute document privacy.
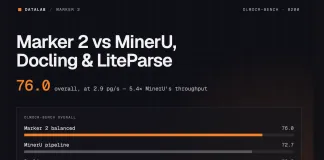
Datalab Marker v2 vs MinerU, Docling, and Liteparse: Benchmark Breakdown
Datalab rewrote Marker as a three-mode pipeline. Version 2 hits 76.0 on olmOCR-bench and sustains 2.9 pages per second on one B200 — over 5× MinerU's pipeline backend, while beating Docling on both accuracy and speed. Here's how it compares against MinerU, Docling and LiteParse, and which one fits your use case.
How to Build an End-to-End OCR Pipeline with Baidu’s Unlimited-OCR for...
In this tutorial, we build a complete workflow for running Baidu’s Unlimited-OCR model on document images and multi-page PDFs. From configuring the GPU environment to comparing high-detail tiled Gundam inference and faster Base modes, you'll learn how to process dense layouts, tables, and cross-page content in a reproducible, end-to-end pipeline.

Datalab Lift vs the Field: How a 9B Schema-First Extractor Compares...
Datalab's Lift is a focused document extraction tool with a specific promise: give it a PDF or image plus a JSON Schema, and it...

Structured PDF-to-JSON: A Guide to Open-Source Extraction Models in 2026
Most enterprise data still sits inside PDFs, scans, and slide decks. Large language models and agents cannot use that data until it becomes structured...
Designing a Schema-Guided Invoice Intelligence Pipeline with lift-pdf for Accounts-Payable Extraction,...
In this tutorial, we build an end-to-end accounts-payable extraction pipeline with lift-pdf, using synthetic invoice PDFs as controlled test documents and a structured JSON...
Using Lift to Turn Research PDFs into Structured JSON with Controlled,...
In this tutorial, we build a full PDF-to-structured-data workflow around Lift, built for controlled evaluation rather than a one-off demo. We prepare a Colab GPU environment, load Lift in 4-bit NF4, and generate synthetic research reports with deliberate distractors. We then run schema-guided extraction, score every field against ground truth, and assemble the results into a queryable knowledge base. The result is a repeatable extraction benchmark, not just raw model outputs.

OCRmyPDF Tutorial: Convert Scanned Documents into Searchable PDF/A Files with Sidecar...
In this tutorial, we build a complete, self-contained OCRmyPDF pipeline in Python. We generate synthetic image-only PDFs so we can test OCR without external files, then convert them into searchable PDFs and PDF/A outputs. We extract sidecar text, validate results, measure word-recall, and compare file sizes. We also tune Tesseract, clean noisy scans, correct orientation, run OCR in memory, and batch-process whole folders.
Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV...
Baidu open-sourced Unlimited OCR, a 3B-parameter MoE model that parses dozens of document pages in a single forward pass. Its Reference Sliding Window Attention (R-SWA) holds the KV cache constant, so memory and latency stay flat as output grows. It scores 93.23 on OmniDocBench v1.5, beating the DeepSeek OCR baseline by 6.22 points, under an MIT license.

Mistral OCR 4 Brings Citation-Ready Structured Output to RAG, Agentic, and...
Mistral AI released OCR 4 on June 23, 2026, moving from clean text extraction to structured document output. Each block returns a bounding box, a typed classification, and per-page and per-word confidence scores. The model supports 170 languages, runs in a single self-hosted container, and feeds citation-ready inputs into RAG, agentic, and enterprise search pipelines through one API endpoint.

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured...
Datalab released lift, a 9B open-weights vision model that turns PDFs and images into schema-matching JSON. It uses schema-constrained decoding for valid structure and trained abstention to return null instead of hallucinating absent fields, scoring 90.2% field accuracy on a 225-document benchmark.

A Coding Guide to Build Advanced Document Intelligence Pipelines with Google...
In this tutorial, we explore how to use Google’s LangExtract library to transform unstructured text into structured, machine-readable information. We begin by installing the...
TII Releases Falcon Perception: A 0.6B-Parameter Early-Fusion Transformer for Open-Vocabulary Grounding and Segmentation from...
In the current landscape of computer vision, the standard operating procedure involves a modular 'Lego-brick' approach: a pre-trained vision encoder for feature extraction paired...
IBM Releases Granite 4.0 3B Vision: A New Vision Language Model...
IBM has announced the release of Granite 4.0 3B Vision, a vision-language model (VLM) engineered specifically for enterprise-grade document data extraction. Departing from the...

Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for...
The landscape of multimodal large language models (MLLMs) has shifted from experimental 'wrappers'—where separate vision or audio encoders are stitched onto a text-based backbone—to...

LlamaIndex Releases LiteParse: A CLI and TypeScript-Native Library for Spatial PDF...
In the current landscape of Retrieval-Augmented Generation (RAG), the primary bottleneck for developers is no longer the large language model (LLM) itself, but the...

Baidu Qianfan Team Releases Qianfan-OCR: A 4B-Parameter Unified Document Intelligence Model
The Baidu Qianfan Team introduced Qianfan-OCR, a 4B-parameter end-to-end model designed to unify document parsing, layout analysis, and document understanding within a single vision-language...

Zhipu AI Introduces GLM-OCR: A 0.9B Multimodal OCR Model for Document...
Why Document OCR Still Remains a Hard Engineering Problem? What does it take to make OCR useful for real documents instead of clean demo...

FireRedTeam Releases FireRed-OCR-2B Utilizing GRPO to Solve Structural Hallucinations in Tables...
Document digitization has long been a multi-stage problem: first detect the layout, then extract the text, and finally try to reconstruct the structure. For...

DeepSeek AI Releases DeepSeek-OCR 2 with Causal Visual Flow Encoder for...
DeepSeek AI released DeepSeek-OCR 2, an open source document OCR and understanding system that restructures its vision encoder to read pages in a causal...

Mistral AI Releases OCR 3: A Smaller Optical Character Recognition (OCR)...
Mistral AI has released Mistral OCR 3, its latest optical character recognition service that powers the company’s Document AI stack. The model, named as...
Tencent Hunyuan Releases HunyuanOCR: a 1B Parameter End to End OCR...
Tencent Hunyuan has released HunyuanOCR, a 1B parameter vision language model that is specialized for OCR and document understanding. The model is built on...
Baidu Releases ERNIE-4.5-VL-28B-A3B-Thinking: An Open-Source and Compact Multimodal Reasoning Model Under...
How can we get large model level multimodal reasoning for documents, charts and videos while running only a 3B class model in production? Baidu...

Comparing the Top 6 OCR (Optical Character Recognition) Models/Systems in 2025
Optical character recognition has moved from plain text extraction to document intelligence. Modern systems must read scanned and digital PDFs in one pass, preserve...

DeepSeek Just Released a 3B OCR Model: A 3B VLM Designed...
DeepSeek-AI released 3B DeepSeek-OCR, an end to end OCR and document parsing Vision-Language Model (VLM) system that compresses long text into a small set...
IBM AI Releases Granite-Docling-258M: An Open-Source, Enterprise-Ready Document AI Model
IBM has released Granite-Docling-258M, an open-source (Apache-2.0) vision-language model designed specifically for end-to-end document conversion. The model targets layout-faithful extraction—tables, code, equations, lists, captions,...

How to Build a Multilingual OCR AI Agent in Python with...
In this tutorial, we build an Advanced OCR AI Agent in Google Colab using EasyOCR, OpenCV, and Pillow, running fully offline with GPU acceleration....

What are Optical Character Recognition (OCR) Models? Top Open-Source OCR Models
Optical Character Recognition (OCR) is the process of turning images that contain text—such as scanned pages, receipts, or photographs—into machine-readable text. What began as...

Meet dots.ocr: A New 1.7B Vision-Language Model that Achieves SOTA Performance...
dots.ocr is an open-source vision-language transformer model developed for multilingual document layout parsing and optical character recognition (OCR). It performs both layout detection and...

NuMind AI Releases NuMarkdown-8B-Thinking: A Reasoning Breakthrough in OCR and Document-to-Markdown...
NuMind AI has officially released NuMarkdown-8B-Thinking, an open-source (MIT License) reasoning OCR Vision-Language Model (VLM) that redefines how complex documents are digitized and structured....