

Computer Vision
Breaking News
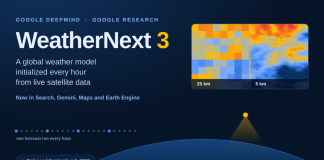
Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver...
WeatherNext 3 ingests live geostationary satellite mosaics, refreshes hourly, and outputs 5 km forecasts across Search, Gemini, Maps.
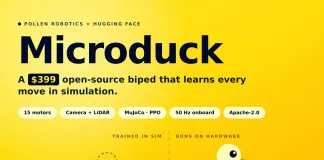
Hugging Face Unveils Microduck: A $399 Open-Source 25 cm Biped You...
Pollen Robotics, the Bordeaux robotics team at Hugging Face, opened pre-orders for Microduck — a 25 cm bipedal robot where every movement is a neural policy trained in MuJoCo and exported to ONNX. At $399, it puts the full sim-to-real loop on a desk: 15 motors, camera, LiDAR, two IMUs, and an Apache-2.0 training stack you can retrain yourself.
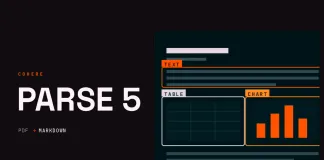
Cohere Releases Parse 5 (parse-v5.0): A 2.3B Vision Language Model That...
Cohere has released Parse (parse-v5.0), a 2.3B-parameter vision language model that converts PDFs, slides and images into Markdown with HTML tables, bounding boxes and image descriptions. It runs at $1.50 per 1,000 pages through the API, or on dedicated Model Vault instances from $2,500 a month. Cohere reports a ParseBench score of 79.2, ahead of Mistral OCR 4, Azure Document Intelligence and Databricks AI Parse — but that figure averages three of the benchmark's five dimensions and drops charts and visual grounding entirely.
Developing an End-to-End Document Intelligence Pipeline with docTR for OCR, Layout...
Develop a complete document intelligence pipeline with docTR, integrating OCR, layout analysis, and KIE for production-oriented extraction and searchable PDF creation.
Liquid AI Releases LFM2.5-VL-3B: A 3B Vision-Language Model That Reads Screens,...
Liquid AI released LFM2.5-VL-3B, a 3.1B-parameter vision-language model built for on-device deployment. It averages 80.7 on ScreenSpot-v2 and lifts RefCOCO grounding from 57.1 to 87.9. Function calling is new to the VL line, with ToolSandbox moving from 26.4 to 59.5. The model fits in roughly 3 GB and decodes 228 tokens/s on an Apple M5 Max.

Xiaomi’s MiLM Plus Releases PROVE: Perception-Aligned Object Removal Metrics RC-S and...
Object removal models have improved faster than the metrics used to judge them. Diffusion erasers now reconstruct shadows, reflections and occluded structure convincingly, yet...
Adaptive Experimentation with Meta’s Ax: A Practical Coding Guide
In this tutorial, we explore adaptive experimentation using Meta’s Ax with the modern Client API. We work through a complete workflow where we tune...

Onton Releases Ontology 1: A Neurosymbolic Search Model That is 2.7x...
Onton, a San Francisco-based search and discovery company, has released Ontology 1, a neurosymbolic model for complex, conversational, multimodal product search. On a 90-query...
A Tutorial on GeoAI: Designing Footprint Extraction from NAIP Imagery Using...
In this tutorial, we design a complete GeoAI workflow for extracting building footprints from high-resolution NAIP aerial imagery. We begin by configuring the geospatial...
LingBot-Map Tutorial: GPU-Aware Inference and Point Cloud Export
Discover how to implement a streaming 3D reconstruction pipeline using LingBot-Map. From GPU-aware configuration and preprocessing to GCTStream model inference and point cloud generation, this guide walks you through the steps to convert image or video sequences into consistent 3D scenes with exportable PLY and NPZ artifacts.
Meet Token Saver: An Open-Source MCP Extension Using Local Hybrid RAG...
Marktechpost AI has released Token Saver, an open-source MCP extension for Claude Desktop that uses local Hybrid RAG to slash PDF token consumption by up to 99% while ensuring absolute document privacy.

Black Forest Labs Releases FLUX 3: A Multimodal Flow Model for...
Black Forest Labs (BFL) has released FLUX 3, a multimodal foundation model that learns from images, videos and audio inside a single architecture. It...

Induction Labs Photon-1 Simulates Desktops, Plays Checkers, and Models Billiard Physics...
Most agents that learn from video need to know what action produced each frame. Induction Labs is arguing that this requirement is the bottleneck....
NVIDIA Released DeepStream 9.1: Bringing Agentic AI to Vision AI With...
NVIDIA DeepStream 9.1 introduces 13 agentic skills that let coding agents like Claude Code and Codex build multi-camera video analytics pipelines from natural-language prompts. Multi-View 3D Tracking (MV3DT) fuses per-camera detections into one shared 3D world with a globally consistent object ID, while AutoMagicCalib (AMC) removes manual camera calibration. The release also adds JetPack 7.2 support and a unified open-source GitHub monorepo.
NVIDIA’s Cosmos-Framework Tutorial: Designing a Colab-Friendly Miniature of Cosmos 3 World...
In this tutorial, we explore NVIDIA's cosmos-framework from a practical Colab angle while staying honest about the hardware needed for real Cosmos 3 checkpoints. We probe the runtime, then use the framework's real structure, CLI surface, and input schema as a foundation. We build and train a compact omnimodal Mixture-of-Transformers that shares cross-modal attention while routing each modality to its own expert. Using synthetic physical-world data and an autoregressive rollout, we show how the model predicts future latent states across text, vision, and action.

OCRmyPDF Tutorial: Convert Scanned Documents into Searchable PDF/A Files with Sidecar...
In this tutorial, we build a complete, self-contained OCRmyPDF pipeline in Python. We generate synthetic image-only PDFs so we can test OCR without external files, then convert them into searchable PDFs and PDF/A outputs. We extract sidecar text, validate results, measure word-recall, and compare file sizes. We also tune Tesseract, clean noisy scans, correct orientation, run OCR in memory, and batch-process whole folders.

Datalab Releases lift: A 9B Open-Weights Vision Model That Extracts Structured...
Datalab released lift, a 9B open-weights vision model that turns PDFs and images into schema-matching JSON. It uses schema-constrained decoding for valid structure and trained abstention to return null instead of hallucinating absent fields, scoring 90.2% field accuracy on a 225-document benchmark.
Zyphra Release Zamba2-VL: Hybrid Mamba2–Transformer Vision-Language Models That Cut Time-to-First-Token by...
Zyphra has released Zamba2-VL, a family of open vision-language models at 1.2B, 2.7B, and 7B parameters. The models use a hybrid Mamba2 state-space and Transformer backbone, shipping under Apache 2.0. They stay competitive with comparable Transformer VLMs while cutting time-to-first-token by about an order of magnitude.
A Hands-On Coding Tutorial on Qualcomm AI Hub Models for Classification,...
Set up Qualcomm AI Hub Models to run MobileNet-V2 inference, YOLOv7 detection, and compile models on real devices.
Microsoft Research’s World-R1 Uses Flow-GRPO and 3D-Aware Rewards to Inject Geometric...
Microsoft Research's World-R1 Uses Reinforcement Learning to Force 3D Consistency Into Text-to-Video Models

How to Build a Lightweight Vision-Language-Action-Inspired Embodied Agent with Latent World...
In this tutorial, we build an embodied simulation vision agent that learns to perceive, plan, predict, and replan directly from pixel observations. We create...
Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose,...
Meta Reality Labs releases a new foundation model family for human-centric vision that pushes pose estimation, segmentation, and 3D geometry to new state-of-the-art levels — all from a single backbone.

Google DeepMind Introduces Vision Banana: An Instruction-Tuned Image Generator That Beats...
A new Google paper argues that image generation pretraining is to computer vision what GPT-style pretraining is to NLP — and the benchmark numbers back that up.
Qwen Team Open-Sources Qwen3.6-35B-A3B: A Sparse MoE Vision-Language Model with 3B...
Qwen Team Open-Sources Qwen3.6-35B-A3B: A Sparse MoE Vision-Language Model with 3B Active Parameters and Agentic Coding Capabilities
Google DeepMind Releases Gemini Robotics-ER 1.6: Bringing Enhanced Embodied Reasoning and...
Google DeepMind research team introduced Gemini Robotics-ER 1.6, a significant upgrade to its embodied reasoning model designed to serve as the 'cognitive brain' of...

A Coding Implementation of MolmoAct for Depth-Aware Spatial Reasoning, Visual Trajectory...
In this tutorial, we walk through MolmoAct step by step and build a practical understanding of how action-reasoning models can reason in space from...
Liquid AI Releases LFM2.5-VL-450M: a 450M-Parameter Vision-Language Model with Bounding Box...
Liquid AI just released LFM2.5-VL-450M, an updated version of its earlier LFM2-VL-450M vision-language model. The new release introduces bounding box prediction, improved instruction following,...
A Coding Guide to Markerless 3D Human Kinematics with Pose2Sim, RTMPose,...
In this tutorial, we build and run a complete Pose2Sim pipeline on Colab to understand how markerless 3D kinematics works in practice. We begin...
Meta Superintelligence Lab Releases Muse Spark: A Multimodal Reasoning Model With...
Meta Superintelligence Labs recently made a significant move by unveiling 'Muse Spark' — the first model in the Muse family. Muse Spark is a...
Meta AI Releases EUPE: A Compact Vision Encoder Family Under 100M...
Running powerful AI on your smartphone isn't just a hardware problem — it's a model architecture problem. Most state-of-the-art vision encoders are enormous, and...

How to Build a Netflix VOID Video Object Removal and Inpainting...
In this tutorial, we build and run an advanced pipeline for Netflix’s VOID model. We set up the environment, install all required dependencies, clone...
Netflix AI Team Just Open-Sourced VOID: an AI Model That Erases...
Video editing has always had a dirty secret: removing an object from footage is easy; making the scene look like it was never there...
TII Releases Falcon Perception: A 0.6B-Parameter Early-Fusion Transformer for Open-Vocabulary Grounding and Segmentation from...
In the current landscape of computer vision, the standard operating procedure involves a modular 'Lego-brick' approach: a pre-trained vision encoder for feature extraction paired...

A Coding Guide to Build a Scalable End-to-End Machine Learning Data...
In this tutorial, we explore how we use Daft as a high-performance, Python-native data engine to build an end-to-end analytical pipeline. We start by...
Physical Intelligence Team Unveils MEM for Robots: A Multi-Scale Memory System...
Current end-to-end robotic policies, specifically Vision-Language-Action (VLA) models, typically operate on a single observation or a very short history. This 'lack of memory' makes...

[Tutorial] Building a Visual Document Retrieval Pipeline with ColPali and Late...
In this tutorial, we build an end-to-end visual document retrieval pipeline using ColPali. We focus on making the setup robust by resolving common dependency...

NVIDIA AI releases C-RADIOv4 vision backbone unifying SigLIP2, DINOv3, SAM3 for...
How do you combine SigLIP2, DINOv3, and SAM3 into a single vision backbone without sacrificing dense or segmentation performance? NVIDIA’s C-RADIOv4 is a new...

Waymo Introduces the Waymo World Model: A New Frontier Simulator Model...
Waymo is introducing the Waymo World Model, a frontier generative model that drives its next generation of autonomous driving simulation. The system is built...
Google Introduces Agentic Vision in Gemini 3 Flash for Active Image...
Frontier multimodal models usually process an image in a single pass. If they miss a serial number on a chip or a small symbol...

Salesforce AI Introduces FOFPred: A Language-Driven Future Optical Flow Prediction Framework...
Salesforce AI research team present FOFPred, a language driven future optical flow prediction framework that connects large vision language models with diffusion transformers for...

Black Forest Labs Releases FLUX.2 [klein]: Compact Flow Models for Interactive...
Black Forest Labs releases FLUX.2 , a compact image model family that targets interactive visual intelligence on consumer hardware. FLUX.2 extends the FLUX.2...

Thinking Machines Lab Makes Tinker Generally Available: Adds Kimi K2 Thinking...
Thinking Machines Lab has moved its Tinker training API into general availability and added 3 major capabilities, support for the Kimi K2 Thinking reasoning...
Zhipu AI Releases GLM-4.6V: A 128K Context Vision Language Model with...
Zhipu AI has open sourced the GLM-4.6V series as a pair of vision language models that treat images, video and tools as first class...

Black Forest Labs Releases FLUX.2: A 32B Flow Matching Transformer for...
Black Forest Labs has released FLUX.2, its second generation image generation and editing system. FLUX.2 targets real world creative workflows such as marketing assets,...

Meta AI Releases Segment Anything Model 3 (SAM 3) for Promptable...
How do you reliably find, segment and track every instance of any concept across large image and video collections using simple prompts? Meta AI...

A Coding Guide to Implement Advanced Hyperparameter Optimization with Optuna using...
In this tutorial, we implement an advanced Optuna workflow that systematically explores pruning, multi-objective optimization, custom callbacks, and rich visualization. Through each snippet, we...
Baidu Releases ERNIE-4.5-VL-28B-A3B-Thinking: An Open-Source and Compact Multimodal Reasoning Model Under...
How can we get large model level multimodal reasoning for documents, charts and videos while running only a 3B class model in production? Baidu...

Why Spatial Supersensing is Emerging as the Core Capability for Multimodal...
Even strong 'long-context' AI models fail badly when they must track objects and counts over long, messy video streams, so the next competitive edge...

Zhipu AI Releases ‘Glyph’: An AI Framework for Scaling the Context...
Can we render long texts as images and use a VLM to achieve 3–4× token compression, preserving accuracy while scaling a 128K context toward...

Salesforce AI Research Introduces WALT (Web Agents that Learn Tools): Enabling...
A team of Salesforce AI researchers introduced WALT (Web Agents that Learn Tools), a framework that reverse-engineers latent website functionality into reusable invocable tools....

UltraCUA: A Foundation Computer-Use Agents Model that Bridges the Gap between...
Computer-use agents have been limited to primitives. They click, they type, they scroll. Long action chains amplify grounding errors and waste steps. Apple Researchers...

Google AI Introduces VISTA: A Test Time Self Improving Agent for...
TLDR: VISTA is a multi agent framework that improves text to video generation during inference, it plans structured prompts as scenes, runs a pairwise...

How to Master Advanced TorchVision v2 Transforms, MixUp, CutMix, and Modern...
In this tutorial, we explore advanced computer vision techniques using TorchVision’s v2 transforms, modern augmentation strategies, and powerful training enhancements. We walk through the...

Top Computer Vision CV Blogs & News Websites (2025)
Computer vision moved fast in 2025: new multimodal backbones, larger open datasets, and tighter model–systems integration. Practitioners need sources that publish rigorously, link code...
IBM AI Releases Granite-Docling-258M: An Open-Source, Enterprise-Ready Document AI Model
IBM has released Granite-Docling-258M, an open-source (Apache-2.0) vision-language model designed specifically for end-to-end document conversion. The model targets layout-faithful extraction—tables, code, equations, lists, captions,...

Meta AI Researchers Release MapAnything: An End-to-End Transformer Architecture that Directly...
A team of researchers from Meta Reality Labs and Carnegie Mellon University has introduced MapAnything, an end-to-end transformer architecture that directly regresses factored metric...

NVIDIA AI Open-Sources ViPE (Video Pose Engine): A Powerful and Versatile...
How do you create 3D datasets to train AI for Robotics without expensive traditional approaches? A team of researchers from NVIDIA released "ViPE: Video...

What are Optical Character Recognition (OCR) Models? Top Open-Source OCR Models
Optical Character Recognition (OCR) is the process of turning images that contain text—such as scanned pages, receipts, or photographs—into machine-readable text. What began as...

AI and the Brain: How DINOv3 Models Reveal Insights into Human...
Introduction
Understanding how the brain builds internal representations of the visual world is one of the most fascinating challenges in neuroscience. Over the past decade,...

Apple Released FastVLM: A Novel Hybrid Vision Encoder which is 85x...
Table of contentsIntroductionExisting VLM ArchitecturesApple’s FastVLMBenchmark ComparisonsConclusion
Introduction
Vision Language Models (VLMs) allow both text inputs and visual understanding. However, image resolution is crucial for VLM...
Qwen Team Introduces Qwen-Image-Edit: The Image Editing Version of Qwen-Image with...
In the domain of multimodal AI, instruction-based image editing models are transforming how users interact with visual content. Just released in August 2025 by...

Meta AI Just Released DINOv3: A State-of-the-Art Computer Vision Model Trained...
Meta AI has just released DINOv3, a breakthrough self-supervised computer vision model that sets new standards for versatility and accuracy across dense prediction tasks,...

VL-Cogito: Advancing Multimodal Reasoning with Progressive Curriculum Reinforcement Learning
Multimodal reasoning, where models integrate and interpret information from multiple sources such as text, images, and diagrams, is a frontier challenge in AI. VL-Cogito...

Meta CLIP 2: The First Contrastive Language-Image Pre-training (CLIP) Trained with...
Contrastive Language-Image Pre-training (CLIP) has become important for modern vision and multimodal models, enabling applications such as zero-shot image classification and serving as vision...

NASA Releases Galileo: The Open-Source Multimodal Model Advancing Earth Observation and...
Introduction
Galileo is an open-source, highly multimodal foundation model developed to process, analyze, and understand diverse Earth observation (EO) data streams—including optical, radar, elevation, climate,...

NVIDIA AI Presents ThinkAct: Vision-Language-Action Reasoning via Reinforced Visual Latent Planning
Estimated reading time: 5 minutes
Table of contentsIntroductionThe ThinkAct FrameworkExperimental ResultsAblation Studies and Model AnalysisImplementation DetailsConclusion
Introduction
Embodied AI agents are increasingly being called upon to interpret...

VLM2Vec-V2: A Unified Computer Vision Framework for Multimodal Embedding Learning Across...
Embedding models act as bridges between different data modalities by encoding diverse multimodal information into a shared dense representation space. There have been advancements...

RoboBrain 2.0: The Next-Generation Vision-Language Model Unifying Embodied AI for Advanced...
Advancements in artificial intelligence are rapidly closing the gap between digital reasoning and real-world interaction. At the forefront of this progress is embodied AI—the...

GPT-4o Understands Text, But Does It See Clearly? A Benchmarking Study...
Multimodal foundation models (MFMs) like GPT-4o, Gemini, and Claude have shown rapid progress recently, especially in public demos. While their language skills are well...

This AI Paper from Alibaba Introduces Lumos-1: A Unified Autoregressive Video...
Autoregressive video generation is a rapidly evolving research domain. It focuses on the synthesis of videos frame-by-frame using learned patterns of both spatial arrangements...

GLM-4.1V-Thinking: Advancing General-Purpose Multimodal Understanding and Reasoning
Vision-language models (VLMs) play a crucial role in today’s intelligent systems by enabling a detailed understanding of visual content. The complexity of multimodal intelligence...

Mirage: Multimodal Reasoning in VLMs Without Rendering Images
While VLMs are strong at understanding both text and images, they often rely solely on text when reasoning, limiting their ability to solve tasks...

JarvisArt: A Human-in-the-Loop Multimodal Agent for Region-Specific and Global Photo Editing
Bridging the Gap Between Artistic Intent and Technical Execution
Photo retouching is a core aspect of digital photography, enabling users to manipulate image elements such...

This AI Paper Introduces MMSearch-R1: A Reinforcement Learning Framework for Efficient...
Large multimodal models (LMMs) enable systems to interpret images, answer visual questions, and retrieve factual information by combining multiple modalities. Their development has significantly...

This AI Paper Introduces PEVA: A Whole-Body Conditioned Diffusion Model for...
Understanding the Link Between Body Movement and Visual Perception
The study of human visual perception through egocentric views is crucial in developing intelligent systems capable...

NVIDIA AI Released DiffusionRenderer: An AI Model for Editable, Photorealistic 3D...
AI-powered video generation is improving at a breathtaking pace. In a short time, we've gone from blurry, incoherent clips to generated videos with stunning...

How Radial Attention Cuts Costs in Video Diffusion by 4.4× Without...
Introduction to Video Diffusion Models and Computational Challenges
Diffusion models have made impressive progress in generating high-quality, coherent videos, building on their success in image...

ByteDance Researchers Introduce VGR: A Novel Reasoning Multimodal Large Language Model...
Why Multimodal Reasoning Matters for Vision-Language Tasks
Multimodal reasoning enables models to make informed decisions and answer questions by combining both visual and textual information....

BAAI Launches OmniGen2: A Unified Diffusion and Transformer Model for Multimodal...
Beijing Academy of Artificial Intelligence (BAAI) introduces OmniGen2, a next-generation, open-source multimodal generative model. Expanding on its predecessor OmniGen, the new architecture unifies text-to-image...

EPFL Researchers Unveil FG2 at CVPR: A New AI Model That...
Navigating the dense urban canyons of cities like San Francisco or New York can be a nightmare for GPS systems. The towering skyscrapers block...

Highlighted at CVPR 2025: Google DeepMind’s ‘Motion Prompting’ Paper Unlocks Granular...
Key Takeaways:
Researchers from Google DeepMind, the University of Michigan & Brown university have developed "Motion Prompting," a new method for controlling video generation using...

This AI Paper Introduces VLM-R³: A Multimodal Framework for Region Recognition,...
Multimodal reasoning ability helps machines perform tasks such as solving math problems embedded in diagrams, reading signs from photographs, or interpreting scientific charts. The...

VeBrain: A Unified Multimodal AI Framework for Visual Reasoning and Real-World...
Bridging Perception and Action in Robotics
Multimodal Large Language Models (MLLMs) hold promise for enabling machines, such as robotic arms and legged robots, to perceive...

Yandex Releases Alchemist: A Compact Supervised Fine-Tuning Dataset for Enhancing Text-to-Image...
Despite the substantial progress in text-to-image (T2I) generation brought about by models such as DALL-E 3, Imagen 3, and Stable Diffusion 3, achieving consistent...

ByteDance Researchers Introduce DetailFlow: A 1D Coarse-to-Fine Autoregressive Framework for Faster,...
Autoregressive image generation has been shaped by advances in sequential modeling, originally seen in natural language processing. This field focuses on generating images one...

Samsung Researchers Introduced ANSE (Active Noise Selection for Generation): A Model-Aware...
Video generation models have become a core technology for creating dynamic content by transforming text prompts into high-quality video sequences. Diffusion models, in particular,...

National University of Singapore Researchers Introduce Dimple: A Discrete Diffusion Multimodal...
In recent months, there has been growing interest in applying diffusion models—originally designed for continuous data, such as images—to natural language processing tasks. This...

This AI Paper Introduces MMaDA: A Unified Multimodal Diffusion Model for...
Diffusion models, known for their success in generating high-quality images, are now being explored as a foundation for handling diverse data types. These models...

Meta AI Introduces Multi-SpatialMLLM: A Multi-Frame Spatial Understanding with Multi-modal Large...
Multi-modal large language models (MLLMs) have shown great progress as versatile AI assistants capable of handling diverse visual tasks. However, their deployment as isolated...

This AI Paper Introduces GRIT: A Method for Teaching MLLMs to...
The core idea of Multimodal Large Language Models (MLLMs) is to create models that can combine the richness of visual content with the logic...

Researchers Introduce MMLONGBENCH: A Comprehensive Benchmark for Long-Context Vision-Language Models
Recent advances in long-context (LC) modeling have unlocked new capabilities for LLMs and large vision-language models (LVLMs). Long-context vision–language models (LCVLMs) show an important...

Google Researchers Introduce LightLab: A Diffusion-Based AI Method for Physically Plausible,...
Manipulating lighting conditions in images post-capture is challenging. Traditional approaches rely on 3D graphics methods that reconstruct scene geometry and properties from multiple captures...

Salesforce AI Releases BLIP3-o: A Fully Open-Source Unified Multimodal Model Built...
Multimodal modeling focuses on building systems to understand and generate content across visual and textual formats. These models are designed to interpret visual scenes...

DanceGRPO: A Unified Framework for Reinforcement Learning in Visual Generation Across...
Recent advances in generative models, especially diffusion models and rectified flows, have revolutionized visual content creation with enhanced output quality and versatility. Human feedback...

ByteDance Introduces Seed1.5-VL: A Vision-Language Foundation Model Designed to Advance General-Purpose...
VLMs have become central to building general-purpose AI systems capable of understanding and interacting in digital and real-world settings. By integrating visual and textual...

Multimodal AI Needs More Than Modality Support: Researchers Propose General-Level and...
Artificial intelligence has grown beyond language-focused systems, evolving into models capable of processing multiple input types, such as text, images, audio, and video. This...

Offline Video-LLMs Can Now Understand Real-Time Streams: Apple Researchers Introduce StreamBridge...
Video-LLMs process whole pre-recorded videos at once. However, applications like robotics and autonomous driving need causal perception and interpretation of visual information online. This...

Multimodal LLMs Without Compromise: Researchers from UCLA, UW–Madison, and Adobe Introduce...
LLMs have made significant strides in language-related tasks such as conversational AI, reasoning, and code generation. However, human communication extends beyond text, often incorporating...
Subject-Driven Image Evaluation Gets Simpler: Google Researchers Introduce REFVNLI to Jointly...
Text-to-image (T2I) generation has evolved to include subject-driven approaches, which enhance standard T2I models by incorporating reference images alongside text prompts. This advancement allows...

UniME: A Two-Stage Framework for Enhancing Multimodal Representation Learning with MLLMs
The CLIP framework has become foundational in multimodal representation learning, particularly for tasks such as image-text retrieval. However, it faces several limitations: a strict...