

AI Infrastructure
Breaking News
Context Engineering Inside the Harness: 4 Mechanisms That Beat Context Overflow...
A shallow agent is an LLM calling tools in a loop, and on long tasks it fails in 2 ways: context overflow and goal loss. This article opens the harness layer that fixes both, with the actual thresholds shipped by LangChain Deep Agents, Claude Code, Manus, OpenAI Codex and Amazon Bedrock AgentCore, plus an interactive simulator that shows a 200K window filling up.
Implementation of Machine Learning Workflows with NVIDIA cuML, RAPIDS, GPU Benchmarking,...
This practical tutorial demonstrates how to build and accelerate machine learning workflows using NVIDIA cuML and RAPIDS. It covers GPU environment setup, zero-code scikit-learn acceleration with cuml.accel, performance benchmarking across key ML algorithms, manifold learning with UMAP and HDBSCAN, tree-model inference with FIL, and model explainability using GPU-accelerated SHAP
Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into...
The Fly Language Model (FLM) drives all 166,700 retained neurons and 25.6 million edges of the MaleCNS fruit fly connectome with token embeddings, then adds a small learned correction to a frozen LFM2.5-1.2B-Instruct backbone. Only 278,528 parameters train. The accompanying preprint reports a 0.0222 nat per token improvement over the backbone, but a parameter-matched control without the graph does slightly better in every seed. We break down the architecture, the four controls, the 0.6 per token memory bound, and what it takes to run the MIT-licensed code locally.
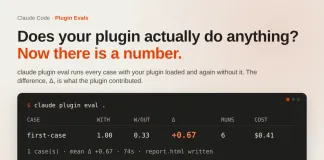
Anthropic Adds Plugin Evals to Claude Code: 6 Grader Types, a...
Anthropic has published a new plugin evals workflow for Claude Code. The claude plugin eval command runs a plugin against realistic prompts, grades what...
Sakana AI Launches Fugu Max and Fugu Ultra v2 for Cheaper,...
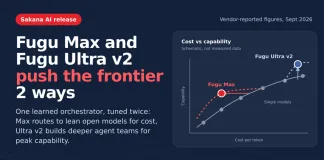
Sakana AI has released Fugu Max and Fugu Ultra v2, 2 models built on the same learned orchestration architecture. Fugu Max routes tasks to lean open and specialized models, including NVIDIA Nemotron, at $2/$6 per 1M tokens. Fugu Ultra v2 targets peak capability, scoring 48.3 on Chartography and 74.3 on DeepSWE.
Meet Redis LangCache: A Managed Semantic Cache That Cuts LLM API...
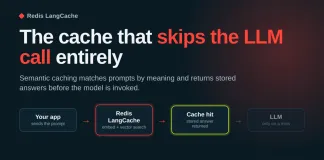
Production LLM applications rarely receive a question nobody has asked before. Support assistants and RAG pipelines field the same intents thousands of times a...
NVIDIA Details BioNeMo Inference Runtime (BioIR): 2.90x Higher Boltz-2 Folding Throughput...
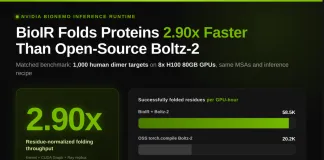
NVIDIA has detailed BioNeMo Inference Runtime (BioIR), a Python library that accelerates biomolecular structure-prediction models on NVIDIA GPUs while staying in plain PyTorch. In a matched benchmark on 1,000 human dimer targets across 8xH100 GPUs, BioIR-accelerated Boltz-2 delivered 58.5K successfully folded residues per GPU-hour versus 20.2K for a torch-compiled open-source implementation, a 2.90x gain. The runtime optimizes at 3 layers: custom kernel selection, CUDA Graph capture, and Ray-based replica scaling that places 1 full model copy per GPU. BioIR already powered the AlphaFold Database expansion, generating about 31 million candidate protein complexes across 4,777 proteomes.

DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and...
Long-horizon agents have turned LLM serving into an input-heavy workload. Repeated prefills and million-token contexts leave KV caches that strain HBM, SSD capacity, and...
NVIDIA Announces CUDA Rust with cuda-oxide (SIMT) and cutile-rs (Tile) for...
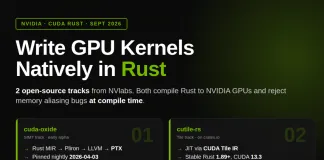
NVIDIA has announced CUDA Rust, a push to make Rust a first-class language for GPU kernels. Two open-source NVlabs projects cover the two CUDA programming models: cuda-oxide compiles SIMT kernels from Rust MIR through Pliron and LLVM to PTX, while cutile-rs JIT-compiles Tile kernels through CUDA Tile IR on stable Rust 1.89+.
Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot...
Robot datasets have grown far slower than the models trained on them, mostly because collection stays locked to lab hardware. AXIS moves demonstration collection into a web browser and pushes everything expensive to backend GPUs. The result is 207 tasks and 50,129 verified Franka trajectories, and continual pretraining that lifts π0.5 from 83.9 to 88.8 on LIBERO-Plus while a volume-matched RoboCasa365 control reaches only 57.5.

IFM Releases K2 Horizon: Six Apache 2.0 Models From 0.9B to...
Most open model launches release one checkpoint and a benchmark table. The Institute of Foundation Models (IFM) released something wider last week. IFM is...

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower...
We look at NeoMME, a family of 260M and 800M bidirectional encoders from H Company. Unlike ColPali-style retrievers, it processes multilingual text tokens and raw 32×32 image patches in a single Transformer, with no pretrained vision tower and no causal decoder. We cover the masked discrete-diffusion pretraining objective, the dual dense and late-interaction retrieval heads, and the ViDoRe v3 results where the 260M model reaches 0.523 nDCG@10. We also break down the 255× index compression, the 51.3 pages per second indexing throughput on one L40S, and the text-retrieval gaps the authors acknowledge.

Meta FAIR Introduces AI Research Preference Models (RPMs): Ranking ML Experiments...
AI research agents can propose far more experiments than they can afford to run. Meta FAIR, Oxford and UCL introduce AI Research Preference Models — frozen LLM judges that rank 15 unexecuted candidates and execute only one. On AIRS-Bench, the average normalized score rises from 0.684 to 0.729, and the baseline's 24-hour result arrives in roughly 15 hours.
UC Berkeley Researchers Release CUA-Lite, an Open Platform Unifying Sandboxes, Data,...
Training and benchmarking a computer-use agent needs four things — agents, environments, traces, and a framework to evaluate and train them — and all four ship in incompatible formats today. CUA-Lite, from a UC Berkeley led team, puts them behind one action space and one data schema, and replaces OSWorld's per-task virtual machine with a plain Docker container at 0.9 GB instead of 4.1 GB.
Perplexity Details Its GPU Embedding Stack: How Ivy, Tulip and ROSE...
Retrieval quality in an AI search product is bounded by two things: how good the embedding model is, and how cheaply you can run...

NVIDIA Releases Personal AI Router (PAIR): An Open Source Virtual Inference...
We look at NVIDIA Personal AI Router (PAIR), an open source virtual inference router that spreads local AI requests across the machines already on a home network. We cover how PAIR proxies existing Ollama and LM Studio endpoints so agent harnesses need no changes, and how its scheduler filters nodes on readiness, engine state, exact model presence, job load, and GPU utilization. We walk through NVIDIA's five-subagent demonstration, which averaged 18 minutes on one RTX Spark laptop against 8 minutes 48 seconds on a three-device cluster, and note why NVIDIA labels it unofficial rather than a benchmark. We also cover where PAIR will not help, including its single scheduling policy and its blindness to VRAM and model warmness.

OpenAI Releases GPT-6 Astra: A 1.05M-Context Computer-Use Model Gated Behind a...
OpenAI released GPT-6 Astra on September 3, 2026, positioning it as a computer-use flagship rather than a chat model. It reports 72.6% on OSWorld V2-Offline, replaces Codex compaction with searchable notes, and ships a 1.05M-token context at $10/$50 per million tokens. It is also the first OpenAI model to cross the Critical cybersecurity threshold, which shapes who can use it and for what.

Perplexity Open Sources Lily: A Rust + Metal Inference Engine for...
Perplexity has open sourced Lily, the local inference engine behind Hybrid Compute in Perplexity Computer. Built in Rust with custom Metal kernels for one model on one chip family, it averages 1.23x MLX-LM's prefill throughput and 1.35x its decode throughput on a 40-core, 128 GB M5 Max.
Qwen Developers Open-Sources zg (zvec-grep): A Local-First Search Layer Unifying ripgrep,...
We look at zg (zvec-grep), the local-first search layer that Qwen Developers just open-sourced under Apache 2.0. We explain how it puts ripgrep, BM25, and vector search behind a single interface, so an agent can move from a plain-language description to an exact line span without switching tools. We cover the deliberately small MCP surface, the on-device embedding catalog, and the authorization gate that stands between local content and remote models.
Meet Switchyard: A Rust Proxy and Library That Routes and Translates...
NVIDIA has released Switchyard, an Apache-2.0 Rust proxy and library for LLM traffic. It decodes requests into provider-neutral types, routes them with passthrough, random, LLM-classifier, or stage-router algorithms, and translates responses back into the client's format, so Claude Code or Codex CLI can run against vLLM, NIM, or Ollama unchanged. The project is pre-alpha and not for production.
Anthropic Introduces Enterprise Frontier Safeguards (EFS): Zero-Data-Retention Privacy Plus Cross-Session Misuse...
Anthropic announced Enterprise Frontier Safeguards on September 1, 2026, an architecture that stores monitoring data in the customer's own cloud account rather than Anthropic's. Detection stays automated and Anthropic-run; custody, encryption keys, and flag review stay with the customer. Built with more than 100 enterprises and rolling out in phases this fall.
Perplexity Releases Hybrid Compute on Mac: Cloud Agents Orchestrate Down to...
Agentic assistants have a structural problem: the context that makes them useful — deal documents, privileged files, client records — is exactly the context...
OpenClaw Releases OpenClaw 2.0: Guided Model Setup, 575 ms Control UI...
The OpenClaw Foundation has released v2026.8.1, which the project calls OpenClaw 2.0: 933 contributors, 569 first-timers, and more than 16,000 pull requests, roughly half of every PR ever merged into the repo. Setup now reuses existing subscriptions, API keys and local models. The rebuilt Control UI cut test-harness startup from about 1.6 seconds to 575 ms. Shared cloud sessions add real multiplayer, though the docs are explicit that they are not a security boundary.

Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent...
Google Cloud AI Research, with Washington University in St. Louis and UNC Chapel Hill, has released EnvHarness, an Apache-2.0 layer that turns a static agent benchmark into one that adapts to the policy training on it. It wraps a frozen environment through the standard reset()/step() interface, so tasks and human-built verifiers stay untouched — and an LLM designer, EnvRigger, writes those wrappers automatically against flaws diagnosed in the agent's own rollouts. Across five benchmarks, mined skills gain up to 9.0 points on held-out tasks with 9.8% fewer execution steps.

Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable...
Code-as-World recovers editable MuJoCo scene code from real video, then uses those verified worlds to train physical reasoning.
Vercel AI Open-Sources vgpu: A TypeScript WebGPU Library for AI Agent...
Vercel has open-sourced vgpu, the WebGPU library it built to ship the shaders on vercel.com. It treats .wgsl files as importable TypeScript modules, runs the same shader in the browser, in headless Node.js via Dawn, and in a deterministic CI mock, and ships a fullscreen effect in 25 KB gzipped.

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous...
Google Research and UNSW Sydney released GlucoFM, a self-supervised foundation model that splits a CGM trace into a slow physiological stream and a transient event stream instead of encoding it as one sequence. At 0.72M parameters it reached 58.8 task-averaged PR-AUC across 14 cohort–task evaluations, beating a 135M GluFormer and a 385M MOMENT. It remains a research prototype with no regulatory clearance.

Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B...
We look at Qwen3.8-Flash-Next, Alibaba's open-weight multimodal Mixture-of-Experts model and an early preview of the Qwen4 architecture. We break down where the 180B parameters actually sit: a 125B backbone, a 51B N-gram embedding table, and a 4B multi-token prediction module, with only 6B active per token. We walk through the four architectural changes — the Gated DeltaNet and Qwen Sparse Attention hybrid, Gated Residual, N-gram Embedding, and the Muon optimizer. We also cover the benchmark results, the reported 1/9 training cost against Qwen3.7-Plus, and what self-hosting a 172.78 GiB FP8 checkpoint really demands.

IBM Releases Granite 4.2: Bringing Native Reasoning and Agentic RL to...
IBM has released Granite 4.2, a family of open reasoning language models in 3B, 8B, and 30B sizes, all under Apache 2.0. Every model exposes a thinking / low-effort / non-thinking switch and native tool calling. The 8B and 30B additionally go through an agentic RL block that trains them to edit code, drive a terminal, and run web searches inside real sandboxed environments. The 30B reports 57.00 on SWE-Bench Verified and 29.24 on Terminal-Bench 2.1.

Liquid AI Open-Sources Pipette: A Reproducible Benchmarking Suite That Measures On-Device...
Model cards report quality under server-class, full-precision conditions. Those numbers rarely predict how the same model behaves on a phone. This week, Liquid AI...

Perplexity Ships Portable Computer on NVIDIA DGX Spark: Local Harness, OS-Enforced...
Perplexity releases Portable Computer, packaging local models, harness, sandbox, and connectors into one system running on NVIDIA DGX Spark.

Meta AI Introduces MetaRoCE: A Clean-Sheet RDMA Transport Built for AI-Scale...
Training and serving frontier models is now a networking problem as much as a compute problem. Collective operations like all-reduce and all-to-all synchronize thousands...

Fastino Releases GLiNER2.5: A Boundary-Prediction Architecture That Removes Span Enumeration From...
Fastino released GLiNER2.5, replacing span enumeration with boundary prediction so entity width no longer costs compute. Three Apache 2.0 checkpoints ship at 74M, 194M, and 287M parameters, all CPU-runnable. The release adds joint entity-relation decoding, constrained classification, span attributes, and 4,096-word context. Overall macro F1 reaches 56.17 on 16 zero-shot benchmarks.

Google Research Introduces ME-POIs: A Mobility-Informed Framework that Adds “How a...
framework that folds aggregate human movement into text-based place embeddings. Language models describe what a place is; they miss how it is used. ME-POIs encodes each visit as a contextualized vector and aligns it with one learnable prototype per POI through contrastive learning, then transfers visit distributions from data-rich anchors to the long tail across three spatial scales. Across five map-enrichment tasks on Los Angeles and Houston mobility data, adding ME-POIs improved 34 of 35 model-task pairings in Los Angeles — up to 81.9% relative F1 on visit intent and a 24.7% MAE reduction on busyness. A mobility-only variant beat Gemini text embeddings on price-level classification.
Best GPU Neoclouds 2026: CoreWeave, Nebius, Lambda, Crusoe, and Groq Ranked...
The five largest GPU neoclouds now run on very different models. CoreWeave and Nebius report to the SEC; Lambda and Crusoe are private and heading toward IPOs; Groq rebuilt itself as an inference cloud after licensing its LPU technology to NVIDIA. This comparison checks each provider's live rate card, Q2 2026 financials, active and contracted gigawatts, anchor contracts, and SemiAnalysis ClusterMAX tier. Nebius posts the lowest H100 rate and the only published B300 price, Lambda has the cheapest B200, Crusoe is the only one with AMD on its card, and CoreWeave commands a 10–15% premium as the sole Platinum-rated provider. Figures verified August 21, 2026.

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2...
FreeToken splits MoE cache misses between PCIe fills and CPU execution using measured bandwidths, unlocking frontier models locally
The Developer’s Guide to NeMo Guardrails for Enterprise AI Safety
In this tutorial, we explore how to design production-grade safety for LLM-based applications using the NeMo Guardrails framework. We move beyond simple prompt filtering to implement a layered architecture, featuring deterministic PII redaction, retrieval filtering, output masking, and policy-based tool gating. By integrating stateful multi-turn evaluation and detailed activation tracing, we demonstrate how to build an auditable, secure, and cost-effective AI assistant capable of managing sensitive financial interactions while maintaining strict compliance standards
Decoding AI’s Open-Source Course Maps Three Ways to Run an Agent...
Most teams treat 'which model' as the important decision. The harness engineering literature keeps pointing somewhere else. In LangChain's Terminal-Bench experiment, changing only the...

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x...
Three ~300M drafters bring speculative decoding to LFM2.5, delivering up to 3.18x faster decoding with identical greedy output.

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint...
NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an Apache-2.0 project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference in two commands, with no intermediate ONNX export. The build emits a versioned .bundle artifact that runs through native C++ task APIs, so inference executes without PyTorch in the runtime path. NVIDIA's July 29, 2026 GB300 snapshot covers 105 release profiles across 76 model families.

Meet SAM (Sovereign Agent Mesh): A Zero-Config, Zero-Trust P2P Network for...
Google has open-sourced SAM (Sovereign Agent Mesh) under Apache-2.0 — and it has nothing to do with Segment Anything. SAM is a zero-config, zero-trust P2P overlay that lets autonomous agents discover and call each other's MCP tools across cloud, on-prem, laptop and edge environments, without exposing a single internal endpoint to the public internet. Identity flows from OIDC into Biscuit capability tokens, so nodes authorize every request offline under a strict default-deny model.

ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic...
ByteDance Seed and Tsinghua AIR have released CUDA Agent, an agentic reinforcement learning system that trains a large language model to write GPU kernels...
Meet Needle 2: An Open 45M-Parameter Tool-Calling Model That Ships as...
Cactus Compute released Needle 2, an open 45M-parameter model for tool calling, device use, and structured extraction. The full model is a single 14MB binary that runs a session in about 28MB of RAM. It leads both Seal-Tools splits while targeting hardware with no GPU and no NPU.

Google AI Just Released Gemini 3.7 Flash: A Coding and Agent...
Google has released Gemini 3.7 Flash, a refinement of Gemini 3.6 Flash with algorithmic improvements to its reasoning core. It handles text, images, audio, and video across a 1M-token context window with 64K-token output, and supports customizable thinking configurations. Coding results move notably: 43.6% on FrontierCode 1.1 Main versus 34.4%, 65.3% on DeepSWE v1.1, and 1588 Elo on WebDev Arena. Document and workflow evals gain more — GDP.pdf goes from 22.0% to 34.0%, AutomationBench from 17.0% to 30.4%. GPT-5.6 Terra still leads on terminal and computer-use agents. The model is API and enterprise only, with no open weights, at an introductory $0.75/$3.75 per 1M tokens through December 31, 2026.

NVIDIA AI Releases Nemotron 3.5 Lightning: A 30B Open MoE with...
NVIDIA's open 30B MoE targets the agent execution layer, with Switchyard routing each step to the cheapest capable model.

webAI Releases TwIL-LM: A 1.7B and 3B Formal-Logic Model Family for...
webAI has released TwIL-LM, a family of formal-logic models at 1.7B and 3B parameters that translate English into first-order logic and check whether conclusions follow from premises. The 3B runs on CPU or 4GB of VRAM; the 1.7B downloads at 1.06GB. Both ship under a non-commercial license. The model card also shows that the headline benchmark scores belong to an unreleased checkpoint, not the weights on the Hub.

Top LLM Observability and Evaluation Platforms in 2026: Langfuse, LangSmith, Braintrust,...
A verified 2026 comparison of LLM observability platforms covering tracing depth, evaluation capability, production monitoring, and pricing.

Pokee AI Releases Pokee-Isaac 28B: A 10M-Token Context Agentic Model Built...
Pokee AI released Pokee-Isaac 28B, a 28B text-only foundation model with a 10M-token context window built to run inside the customer boundary. It scores 93.3% on RULER at 10M tokens, where every baseline in its comparison panel returns 0.0 beyond 2M, and leads BFCL v4 at 70.94 while placing second on Terminal-Bench 2.1. Prefill reaches 137,200 tokens/s at full context on a single B200, with decode flat near 335 tokens/s. Weights are not published; deployment is licensed into VPC, on-premises, or on-device, with list pricing at $0.15/$1.00 per million tokens.
Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety...
Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that frames content moderation as a single yes/no question instead of a fixed harm taxonomy. Operators supply the policy as a plain-language query at inference time and get back a calibrated safety score from one forward pass — no retraining required to re-target the model. Built on Ministral-3-3B-Base-2512 with a Pixtral vision encoder and trained on roughly 54.1M samples, it reports 84.9% average F1 on text safety (matching GPT-OSS-Safeguard-20B), 83.8% on multimodal safety, and 91.3% on Mistral's adaptability benchmark — while fitting in 16GB of VRAM under an Apache 2.0 license.
Tencent Cloud Open-Sources TencentDB Agent Memory v2.0: A Team-Level Memory Hub...
Tencent Cloud has open-sourced TencentDB Agent Memory v2.0, a team-level memory hub that turns conversations, documents and code into four governed, reusable assets — Chat Memory, Skill, LLM-Wiki and Code-Graph. It is MIT-licensed, self-hosted via Docker, and integrates with Claude Code, OpenClaw, Hermes and CodeBuddy. The differentiator is not retrieval but governance: ACL-based visibility decides which agent gets which asset, and which version is valid.
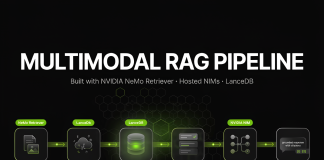
Building a Multimodal RAG Pipeline with NVIDIA NeMo Retriever, Hosted NIMs,...
In this tutorial, we build an advanced multimodal retrieval-augmented generation pipeline with NVIDIA NeMo Retriever. We begin by configuring a Python 3.12 environment, installing...
NVIDIA AI Releases NOOA: An Object-Oriented Python Framework That Turns an...
NVIDIA Labs has open-sourced NOOA (NVIDIA Object-Oriented Agents), a model-agnostic Python framework for building AI agents. Agent development today is split across prompt templates,...

Cloudflare Introduces Kitesurf: An Agent-First Web Browser That Runs Entirely in...
Cloudflare has released Kitesurf, a stateless web browser built specifically for AI agents that runs entirely in V8 isolates on Cloudflare Workers, with no Chromium underneath. The browser drops human-facing features like tabs and extensions in favor of what agents need: machine-readable content, scalability, and isolation. Built in 12 weeks using Rust components like Blitz, Stylo, and Boa JS, it already passes 215,000+ Web Platform Tests. Benchmarks show 3.1–3.8× less CPU and 4.7–7.0× less memory than Chromium on screenshots and HTML extraction. Existing Puppeteer, Playwright, and MCP clients work by adding a single browser=kitesurf parameter, free while in beta.
Prime Intellect Releases Prime Agent: An Open-Source RLM Harness Where Sub-Agents...
Prime Intellect has open-sourced Prime Agent, a coding and research harness built on two abstractions: the Recursive Language Model, which turns sub-agent calls into functions inside a persistent IPython kernel, and the Continual Harness, which lets the agent edit its own prompts, skills, memory, and sub-agent specs mid-run. With Opus 5 it reports 95.5% RHAE Best@1 on ARC-AGI-3, above the reported human expert baseline of 95.4%.
End-to-End Bayesian Marketing Mix Modeling with Google Meridian: Media Measurement, ROI...
In this tutorial, we build a complete Bayesian marketing mix modeling workflow using Google Meridian. We begin by installing the required libraries, verifying GPU...
Meta AI Releases Muse Code (Beta): A Terminal Coding Agent Powered...
Meta Superintelligence Labs has released Muse Code, a terminal coding agent in beta, powered by the new Muse Spark 1.2 model. Muse Code plans changes, writes code, and validates results across large repositories. Async background agents stay active for the whole session instead of spawning per task. A local append-only event log makes the runtime replay-exact and restart-safe after a crash. Muse Spark 1.2 was co-trained with the harness and trained on long-horizon, repository-scale work.
NVIDIA Releases Alpamayo 2 Super: A 34B Open Vision-Language-Action Model for...
NVIDIA released Alpamayo 2 Super, a 34B vision-language-action model for autonomous driving, under OpenMDW-1.1 — a permissive license covering fine-tuning, derivatives and commercial redistribution. It pairs a 32B Cosmos 3 Super Reasoner backbone with a 2.3B diffusion action decoder, scores 79.2 on LingoQA, and emits trajectories, Chain-of-Causation traces, meta-actions, auto-labels and grounded VQA from a single pass.
CopilotKit Open Sources Channels SDK: An MIT Licensed Library That Runs...
CopilotKit has published the Channels SDK, an MIT licensed library that runs an existing AG-UI agent inside Slack and Microsoft Teams. Version 0.5.0 ships five platform adapters and a documented runtime contract. This breakdown covers the verified deployment paths, the baseline requirements, and the one dependency that is easy to miss

Cursor Open-Sources Mixture-of-Kittens (MoK): A Deterministic MoE Training Megakernel for GB300...
Cursor Research has open-sourced Mixture-of-Kittens (MoK), the MoE training megakernel behind its Composer models. MoK fuses all mixture-of-experts communication and computation into a single deterministic kernel, and runs up to 2.37x faster than the strongest public baseline on GB300 NVL72 racks. It requires Blackwell SM100 or SM103 GPUs, which puts it out of reach for anyone without NVL72 capacity.
Y Combinator Open-Sources QM: An MIT-Licensed Multiplayer Agent Harness That Runs...
Y Combinator has open-sourced QM, the multiplayer agent harness it uses internally across accounting, legal, events, and engineering. Released July 31, 2026 under an MIT license, QM gives each employee an isolated workspace and each Slack room its own scoped memory, files, keychain view, permissions, crons, web apps, and durable sandbox. Pi, OpenCode, Codex, and Claude Code all drive the same headless core, so deployments avoid vendor lock-in.
Evaluating Multimodal Vision Models with Moonshot PerceptionBench Using Robust Data Loading...
In this tutorial, we design an end-to-end evaluation workflow for PerceptionBench. This multimodal benchmark measures fine-grained visual perception capabilities across tasks such as OCR,...

How to Secure AI Agents, MCP Servers, and LLM Apps in...
AI agents, MCP servers, and LLM apps break the core AppSec assumption that applications do what their code says. This guide walks through a practical see-fix-protect framework: a five-layer agentic AI attack surface map, a 12-point misconfiguration checklist, an evidence-based triage matrix, runtime guardrails, and system prompt hardening — plus a maturity self-assessment aligned to NIST AI RMF, OWASP AIMA, ISO/IEC 42001, and the EU AI Act.
AMD Releases Instella-MoE-16B-A3B: A Fully Open Mixture-of-Experts LLM With 2.8B Active...
AMD released Instella-MoE-16B-A3B, a fully open Mixture-of-Experts language model trained from scratch on Instinct MI300X and MI325X GPUs. It holds 16B total parameters but activates only 2.8B per token, using Gated MLA and FarSkip-Collective. AMD published weights from every training stage, plus data mixtures, configs, and inference code.
Accelerating Transformer Training with NVIDIA Transformer Engine, Fused Kernels, BF16, FP8,...
Discover how to optimize transformer workloads using the NVIDIA Transformer Engine. This tutorial guides you through configuring fused GPU kernels, implementing FP8 delayed scaling, and benchmarking model performance. Learn to build and train efficient GPT-style causal language models in PyTorch with practical code examples and performance analysis.

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains
DeepSeek published DeepSeek-V4-Flash-0731 on Hugging Face and moved the official V4-Flash API into public beta on July 31, 2026. The model card is explicit...
JetBrains Open-Sources KotlinLLM: Smart Macros That Generate Kotlin Source Code at...
JetBrains Research has open-sourced KotlinLLM under the Apache License 2.0. The IntelliJ IDEA plugin prototype adds Smart macros, asLlm and mockLlm, whose bodies are generated Kotlin source rather than live model calls. The plugin captures runtime values through JDI, asks an LLM agent for a narrow code update, compiles it, and redefines the loaded class. Covered scenarios then run as plain Kotlin with no further inference call. On an adapted Spring Petclinic project, 24 of 24 scenarios completed with a 100% hot-reload success rate and roughly 1% runtime overhead.

Google DeepMind Ships Three Physical AI Models For Whole Body Control,...
Google DeepMind has released Gemini Robotics 2, the intelligence layer for its next generation of robots. The release ships three models: a vision-language-action model for whole body humanoid control, Gemini Robotics ER 2 for embodied reasoning and task orchestration, and an on-device VLA that adapts to new robot bodies in hours. One checkpoint drives Apptronik Apollo 2 and a Franka Duo. Only ER 2 is publicly available.

Tencent Open-Sources AngelSpec: A Unified Training Framework for MTP and Block-Parallel...
Tencent has released AngelSpec, an open-source torch-native framework for training speculative-decoding draft models across six architectures. It introduces DFly, a block-diffusion drafter with hybrid target conditioning and a hidden-correction autoregressive head, and integrates D-cut for runtime-adaptive verification budgeting. On HY3-295B-A21B with TP=8, DFly-8 delivers a 1.98–2.40× speedup over autoregressive decoding across concurrency 4 to 64.
Moonshot AI Open-Sources MoonEP: A Perfectly Balanced Expert Parallelism Library for...
Moonshot AI has open-sourced MoonEP, an Expert Parallelism (EP) communication library for distributed Mixture-of-Experts (MoE) workloads. The team announced the release as a library...
Liquid AI Releases LFM2.5-Encoder-230M and LFM2.5-Encoder-350M: Bidirectional Encoders That Stay Fast...
Liquid AI released two open-weight bidirectional encoders, LFM2.5-Encoder-230M and LFM2.5-Encoder-350M. Both carry an 8,192-token context and are built on the LFM2 hybrid backbone. The 350M ranks fourth of 14 models on a 17-task GLUE, SuperGLUE, and multilingual suite, behind only larger models. The 230M clears one 8K-token forward pass on CPU in about 28 seconds.

Fireworks AI Releases Fireworks Nexus: A Drop-In Routing and Cost-Control Layer...
Fireworks AI has released Fireworks Nexus, an AI management and routing platform aimed at engineering organizations. It connects the coding tools developers already use...
Deploying a 1-Bit Bonsai-27B Model with PrismML llama.cpp and OpenAI-Compatible Local...
In this tutorial, we deploy the 1-bit Bonsai-27B language model using the PrismML fork of llama.cpp, which provides the specialized CUDA kernels required to decode the model’s Q1_0_g128 GGUF quantization format
Kimi AI and kvcache-ai Open Sources ‘AgentENV’: A Distributed System that...
Moonshot AI's Kimi team and kvcache-ai open-sourced AgentENV (AENV) under MIT, as part of Kimi K3 Open Day. It runs agent sandboxes as Firecracker microVMs with millisecond snapshot, resume, and 16-way fork, behind an E2B-compatible API.

Meet Open Dreamer: A JAX/Flax Reproduction of the Dreamer 4 World...
A small group of AI researchers (Francesco Sacco, Diego Martí, and Edward Hu) have released Open Dreamer, an open implementation of the Dreamer 4...
Designing High-Performance GPU Kernels with TileLang: Tensor-Core GEMM, Fused Softmax, FlashAttention,...
Explore TileLang, a high-level Python domain-specific language that simplifies the design of high-performance GPU kernels. This tutorial provides a step-by-step approach to implementing complex workloads—including tiled tensor-core GEMM, fused softmax, and FlashAttention—while letting the compiler handle intricate thread mapping, memory layouts, and low-level CUDA instruction generation.
How to Build an End-to-End OCR Pipeline with Baidu’s Unlimited-OCR for...
In this tutorial, we build a complete workflow for running Baidu’s Unlimited-OCR model on document images and multi-page PDFs. From configuring the GPU environment to comparing high-detail tiled Gundam inference and faster Base modes, you'll learn how to process dense layouts, tables, and cross-page content in a reproducible, end-to-end pipeline.

Meet Gigatoken: A Rust BPE Tokenizer that Encodes Text at 24.53...
Gigatoken is an MIT-licensed Rust BPE tokenizer that encodes text at gigabytes per second. On a 144-core AMD EPYC 9565, it runs GPT-2 tokenization at 24.53 GB/s. That is 989x HuggingFace tokenizers and 681x tiktoken, against baselines already written in multithreaded Rust. The gains come from a hand-written SWAR pretokenizer and pretoken caching, not a faster BPE merge loop.

Unsloth vs Axolotl vs TRL vs LLaMA-Factory: A Fine-Tuning Framework Comparison...
Four open source projects dominate LLM fine-tuning today. Unsloth, Axolotl, TRL, and LLaMA-Factory all wrap the same underlying PyTorch and Hugging Face stack. They...
Poolside Releases Laguna S 2.1, an Open-Weight Agentic Coding Model Punching...
Poolside has released Laguna S 2.1, a 118B open-weight Mixture-of-Experts coding model with 8B active parameters per token and a 1M-token context. It matches or beats models several times its size on agentic coding benchmarks, ships under OpenMDW-1.1, and runs on a single NVIDIA DGX Spark.
Validating Distributed LLM Serving Benchmarks with NVIDIA srt-slurm, SLURM Recipes, Parameter...
In this tutorial, we explore NVIDIA’s srt-slurm framework and learn how we use srtctl to convert declarative YAML configurations into reproducible SLURM benchmark workflows...

NVIDIA Releases Cosmos 3 Edge: A 4B-Parameter Open World Model That...
NVIDIA has released Cosmos 3 Edge, a 4-billion-parameter open world model built to run on-device. It helps robots and vision AI agents understand surroundings,...

Best Local LLMs You Can Run on a Single 24GB GPU...
A single 24GB GPU is the practical floor for serious local inference. This guide compares six open-weight models that fit one card at Q4_K_M. It covers Qwen3.6, Gemma 4, Mistral Small, gpt-oss-20b, and DeepSeek-R1-Distill. Each entry lists VRAM fit, licensing, and the job it does best.
Fine-Tuning Qwen3 with LoRA Using NVIDIA NeMo AutoModel: A Complete Single-GPU...
We build an end-to-end NVIDIA NeMo AutoModel workflow in Google Colab using a single GPU. We verify CUDA hardware and precision support, install NeMo AutoModel from source, and load an official Qwen3-0.6B LoRA recipe. We then adapt its precision, batch size, checkpointing, and scheduler settings for a constrained runtime. We launch fine-tuning through the automodel CLI, reload the LoRA checkpoint, and compare base versus fine-tuned outputs. We finish with the NeMoAutoModelForCausalLM Python API.

Sakana AI’s Error Diffusion Trains Dale-Compliant Dual-Stream Networks, Reaching 96.7% MNIST...
Backpropagation relies on weight transport, which biological circuits likely cannot implement. Sakana AI's Error Diffusion sidesteps that constraint, training dual-stream excitatory/inhibitory networks that obey Dale's principle. This piece breaks down how modulo error routing scales the rule from MNIST to CIFAR-10 and reinforcement learning, and what its task-dependent ablations reveal.

Thinking Machines Lab Releases Inkling: A 975B-Parameter Open-Weights Multimodal MoE With...
Thinking Machines Lab released Inkling on July 15, 2026, its first model trained from scratch. The full weights ship under Apache 2.0. It is a 975B-parameter Mixture-of-Experts transformer with 41B active parameters, a 1M-token context window, and native text, image, and audio input. The lab states plainly that Inkling is not the strongest model available, open or closed. It is positioned instead as a customization base, with controllable thinking effort as the practical differentiator.

Soofi Consortium Releases Soofi S 30B-A3B: An Open Hybrid Mamba-Transformer MoE...
Soofi S 30B-A3B is an open Mamba-Transformer MoE model activating 3.2B of 31.6B parameters for German and English

Stanford Researchers Introduce TRACE: A Capability-Targeted Agentic Training System That Turns...
Agentic LLMs keep failing the same way because they lack specific, reusable capabilities. Stanford's TRACE diagnoses those gaps from an agent's own trajectories, synthesizes one verifiable training environment per capability, trains a LoRA adapter for each, and routes tokens across experts—improving τ²-Bench by +15.3 points and reaching 73.2% Pass@1 on SWE-bench Verified.

Guide to Loop Engineering: How ‘autoresearch’ and ‘Bilevel Autoresearch’ Turn AI...
Most people still use AI like a 2015 search box. You type, you read, you type again. A newer pattern replaces that manual back-and-forth...

A Coding Guide to NVIDIA’s Tile-Based GPU Programming: From cuTile and...
In this tutorial, we explore NVIDIA tile-based GPU programming with TileGym, building a Colab workflow that runs across different hardware. We probe the CUDA environment, try the real cuTile backend, and fall back to Triton when standard Colab GPUs lack the cuTile stack. We learn the core tile idea: operate on whole data tiles instead of single threads, then load, compute, and store them. We implement vector addition, fused GELU, row-wise softmax, tiled matrix multiplication, and flash attention, checking each against PyTorch.
Ant Group’s Robbyant Unveils LingBot-VA 2.0: A Causal Video-Action Model Built...
Ant Group's Robbyant has released the LingBot-VA 2.0 technical report — a Physical AI video-action foundation model built from scratch for embodiment rather than fine-tuned from a video generator. It predicts future states ahead of execution through Foresight Reasoning, re-grounds on every real observation, and reaches 225 Hz asynchronous control. We break down the causal DiT, the sparse-MoE video stream, the semantic visual-action tokenizer, and where the paper's own numbers don't line up.

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness
Robbyant, Ant Group's embodied-intelligence unit, has released LingBot-World-Infinity (LingBot-World 2.0). It is a 14B causal video generation model that behaves as an interactive world simulator. The core idea is the Mixture of Bidirectional and Autoregressive (MoBA) attention mask, paired with distribution matching distillation applied over long self-rollout trajectories. Together they target long-horizon drift, the failure mode that smears textures and warps geometry in most interactive world models. A Director-Pilot agentic harness wraps the generator, where a VLM proposes events and the Diffusion Transformer renders them. The report shows a single 60-minute uninterrupted session covering 20 scenarios. But the release is thinner than the paper: one checkpoint, a 480P reference script, no deployment code, no quantitative benchmarks, and a non-commercial CC BY-NC-SA 4.0 license.

Meta Superintelligence Labs Releases Muse Spark 1.1: A Multimodal Reasoning Model...
Meta Superintelligence Labs released Muse Spark 1.1 on July 9, 2026, alongside a public preview of the Meta Model API. It is a multimodal reasoning model built for agentic tasks, with a 1,000,000-token context window the model actively compacts, zero-shot generalization to new tools and MCP servers, and multi-agent delegation across parallel subagents. Meta's own launch table shows it leading tool use while trailing Opus 4.8 and GPT-5.5 on coding.
Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for...
Ant Group's Robbyant has released LingBot-VLA 2.0, an Apache-2.0 vision-language-action model for cross-embodiment robot manipulation. The 6B checkpoint is pretrained on roughly 60,000 hours of data, spanning 50,000 hours of robot trajectories across 20 robot configurations and 10,000 hours of egocentric human video. It maps every embodiment into a single 55-dimensional canonical action space, covering arms, dexterous hands, waists, heads, and mobile bases. A token-level, auxiliary-loss-free Mixture-of-Experts action expert scales capacity without adding a load-balancing loss. Dual-query distillation from LingBot-Depth and DINO-Video adds geometric and temporal supervision for future-aware control. On the GM-100 generalist benchmark it outperforms π0.5 and LingBot-VLA-1.0 on both evaluated platforms.

Netflix AI Team Cuts Wide-Partition Read Latency from Seconds to Milliseconds...
Netflix engineers detailed how they handle wide partitions in Apache Cassandra for the TimeSeries Abstraction. Two approaches work together: Time Slice re-partitioning tunes future partitions at the table level, while dynamic partitioning detects and splits oversized partitions per TimeSeries ID on the read path. Detection runs via byte counting and Kafka, splits are checksum-validated, and Bloom filters route reads to parallel child partitions. Average read latency dropped from seconds to low double-digit milliseconds, with 500MB+ partitions staying available.

Ant Group’s Robbyant Open-Sources LingBot-Vision: A 1B Boundary-Centric Vision Foundation Model...
Ant Group's Robbyant open-sourced LingBot-Vision, a self-supervised ViT family for dense spatial perception. Masked boundary modeling makes image boundaries a native training signal. The 1B backbone matches or surpasses larger models, and initializes LingBot-Depth 2.0.
Liquid AI Open-Sources Antidoom: A Final Token Preference Optimization (FTPO) Method...
Liquid AI released Antidoom, an open-source method that targets doom loops in reasoning models. A doom loop repeats a span until the context window is exhausted. Antidoom finds the token that starts the loop and retrains only that position using Final Token Preference Optimization (FTPO). On LFM2.5-2.6B, doom-loop rates fell from 10.2% to 1.4%; on Qwen3.5-4B, from 22.9% to 1%. Generation, detection, and the FTPO trainer are open source.
Synthetic Sciences Releases OpenScience: An Open-Source, Model-Agnostic AI Workbench for Machine...
Synthetic Sciences has released OpenScience, an Apache-2.0 AI workbench for scientific research. It works with any frontier or open-weight model, using your own API keys. It runs the full loop across machine learning, biology, physics, and chemistry. It ships 250+ editable skills and queryable scientific databases, and it runs on your own infrastructure.

Meituan Releases LongCat-2.0: A 1.6T-Parameter Open MoE Model with Native 1M...
Meituan has released LongCat-2.0, a 1.6 trillion-parameter Mixture-of-Experts model that activates about 48 billion parameters per token. It pairs a native 1-million-token context, built on LongCat Sparse Attention, with training and serving run end-to-end on domestic AI ASIC superpods. Here is the architecture, the vendor-reported benchmarks, the API access path, and what remains unverified.
NVIDIA HORIZON: A Hands-Free Agent that Evolves Git Worktrees and Hits...
A hands-free NVIDIA agent framework hosts each RTL problem as a versioned repository, reaching 100% completion across benchmarks.
CUP (Common Useful Python): Building Reliable Python Workflows with Baidu’s Utility...
In this tutorial, we explore CUP, Baidu's Common Useful Python library, as a practical utility toolkit for stronger Python workflows. We install it in a Colab-friendly environment and walk its subsystems step by step. We cover logging, decorators, nested configuration, caching, ID generation, thread pools, scheduling, and Linux resource monitoring. Along the way, we connect each module to real tasks like automation, concurrency, and reliability checks.