

AI Paper Summary
Breaking News
Fly Language Model (FLM) Wires the Full Fruit Fly Connectome Into...
The Fly Language Model (FLM) drives all 166,700 retained neurons and 25.6 million edges of the MaleCNS fruit fly connectome with token embeddings, then adds a small learned correction to a frozen LFM2.5-1.2B-Instruct backbone. Only 278,528 parameters train. The accompanying preprint reports a 0.0222 nat per token improvement over the backbone, but a parameter-matched control without the graph does slightly better in every seed. We break down the architecture, the four controls, the 0.6 per token memory bound, and what it takes to run the MIT-licensed code locally.
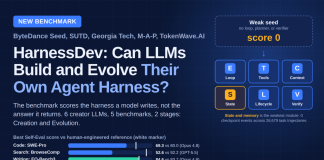
Can LLMs Engineer Their Own Agent Harness? ByteDance Seed’s HarnessDev Says...
ByteDance Seed, SUTD, Georgia Tech, M-A-P, and TokenWave.AI introduce HarnessDev, a benchmark that scores the runnable harness a model builds rather than the answer it returns. Starting from a seed that scores 0, 6 creator LLMs construct harnesses across 5 benchmarks and 2,207 tasks, then evolve them from execution feedback. Self-built harnesses match human references on writing and ML experimentation but trail on code and search, and only 34 of 64 evolution changes move the same direction on held-out tasks.
Google Research Releases ToolGrad: Answer-First Framework Hits 99.8% Pass Rate for...
Google Research has released ToolGrad, an ACL 2026 Findings framework that inverts tool-use dataset generation: it builds a verified API chain first, then writes the matching user query. Guided by textual "gradients" from a 4-module propose-execute-select-update loop, ToolGrad reaches a 99.8% pass rate on ToolBench versus 63.8% for DFS search. Gemma-3-12B fine-tuned on only 500 samples scores 83.1 on BFCL, next to Gemini 2.5 Pro at 83.2. Code, dataset, and models are public under Apache-2.0.

DeepSeek AI Released DeepSeek-V4.1-Flash with 1M Context, FP4 KV Cache, and...
Long-horizon agents have turned LLM serving into an input-heavy workload. Repeated prefills and million-token contexts leave KV caches that strain HBM, SSD capacity, and...

Google DeepMind Releases AlphaGenome Atlas With Precomputed Molecular Effect Predictions and...
DeepMind's AlphaGenome Atlas maps every single-letter change in the human genome with 1 impact score per variant.

OpenBMB Releases MiniCPM5-2B: A 2.52B Dense Model Averaging 53.9 Across 34...
OpenBMB has released MiniCPM5-2B, a dense causal language model with 2,516,756,480 parameters and a native 131,072 token context. It averages 53.9 across the 34 benchmarks in its model card, ahead of Qwen3.5-4B at 51.1, with its clearest leads in tool use, coding agents and long-context retrieval. Post-training pairs 400B tokens of deep-thinking SFT with RL teachers and on-policy distillation that merges 16 expert models into one checkpoint. The weights ship under Apache 2.0 alongside the pre-training, SFT and RL datasets and the intermediate Base, Midtrain and SFT-only checkpoints. GGUF builds start at 1.56 GB, and the standard LlamaForCausalLM architecture loads in vLLM, SGLang, llama.cpp, Ollama and MLX without a model-code fork.
Axis Robotics Releases AXIS: A Browser-Based Data Engine With 207 Robot...
Robot datasets have grown far slower than the models trained on them, mostly because collection stays locked to lab hardware. AXIS moves demonstration collection into a web browser and pushes everything expensive to backend GPUs. The result is 207 tasks and 50,129 verified Franka trajectories, and continual pretraining that lifts π0.5 from 83.9 to 88.8 on LIBERO-Plus while a volume-matched RoboCasa365 control reaches only 57.5.

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower...
We look at NeoMME, a family of 260M and 800M bidirectional encoders from H Company. Unlike ColPali-style retrievers, it processes multilingual text tokens and raw 32×32 image patches in a single Transformer, with no pretrained vision tower and no causal decoder. We cover the masked discrete-diffusion pretraining objective, the dual dense and late-interaction retrieval heads, and the ViDoRe v3 results where the 260M model reaches 0.523 nDCG@10. We also break down the 255× index compression, the 51.3 pages per second indexing throughput on one L40S, and the text-retrieval gaps the authors acknowledge.

Meta FAIR Introduces AI Research Preference Models (RPMs): Ranking ML Experiments...
AI research agents can propose far more experiments than they can afford to run. Meta FAIR, Oxford and UCL introduce AI Research Preference Models — frozen LLM judges that rank 15 unexecuted candidates and execute only one. On AIRS-Bench, the average normalized score rises from 0.684 to 0.729, and the baseline's 24-hour result arrives in roughly 15 hours.
Google DeepMind’s WeatherNext 3 Trains on Weather Station Observations to Deliver...
WeatherNext 3 ingests live geostationary satellite mosaics, refreshes hourly, and outputs 5 km forecasts across Search, Gemini, Maps.

Researchers from Princeton, Ant Group and Stanford Introduce AQuA: A Two-Part...
Quantitative research agents that write their own experiments can corrupt the evidence they later learn from. A leaky feature that scores well gets stored...

Google AI Introduces EnvHarness: A Programmable Layer That Turns Static Agent...
Google Cloud AI Research, with Washington University in St. Louis and UNC Chapel Hill, has released EnvHarness, an Apache-2.0 layer that turns a static agent benchmark into one that adapts to the policy training on it. It wraps a frozen environment through the standard reset()/step() interface, so tasks and human-built verifiers stay untouched — and an LLM designer, EnvRigger, writes those wrappers automatically against flaws diagnosed in the agent's own rollouts. Across five benchmarks, mined skills gain up to 9.0 points on held-out tasks with 9.8% fewer execution steps.

Meet ‘Code-as-World’: An Agentic Loop That Rewrites Real Videos Into Executable...
Code-as-World recovers editable MuJoCo scene code from real video, then uses those verified worlds to train physical reasoning.

Google Research Introduces GlucoFM: A 0.72M-Parameter Dual-Stream Foundation Model for Continuous...
Google Research and UNSW Sydney released GlucoFM, a self-supervised foundation model that splits a CGM trace into a slow physiological stream and a transient event stream instead of encoding it as one sequence. At 0.72M parameters it reached 58.8 task-averaged PR-AUC across 14 cohort–task evaluations, beating a 135M GluFormer and a 385M MOMENT. It remains a research prototype with no regulatory clearance.

Google Research Introduces ME-POIs: A Mobility-Informed Framework that Adds “How a...
framework that folds aggregate human movement into text-based place embeddings. Language models describe what a place is; they miss how it is used. ME-POIs encodes each visit as a contextualized vector and aligns it with one learnable prototype per POI through contrastive learning, then transfers visit distributions from data-rich anchors to the long tail across three spatial scales. Across five map-enrichment tasks on Los Angeles and Houston mobility data, adding ME-POIs improved 34 of 35 model-task pairings in Los Angeles — up to 81.9% relative F1 on visit intent and a 24.7% MAE reduction on busyness. A mobility-only variant beat Gemini text embeddings on price-level classification.

Meet FreeToken: An Edge-Native MoE Serving Engine that Runs 753B GLM-5.2...
FreeToken splits MoE cache misses between PCIe fills and CPU execution using measured bandwidths, unlocking frontier models locally

ByteDance Seed and Tsinghua AIR Introduces CUDA Agent: A Large-Scale Agentic...
ByteDance Seed and Tsinghua AIR have released CUDA Agent, an agentic reinforcement learning system that trains a large language model to write GPU kernels...

Xiaomi’s MiLM Plus Releases PROVE: Perception-Aligned Object Removal Metrics RC-S and...
Object removal models have improved faster than the metrics used to judge them. Diffusion erasers now reconstruct shadows, reflections and occluded structure convincingly, yet...
Mistral AI Releases Shieldstral 1.0 3B: An Open-Weights Policy-Adaptive Multimodal Safety...
Mistral AI has released Shieldstral 1.0 3B, an open-weights, policy-adaptive multimodal safety classifier that frames content moderation as a single yes/no question instead of a fixed harm taxonomy. Operators supply the policy as a plain-language query at inference time and get back a calibrated safety score from one forward pass — no retraining required to re-target the model. Built on Ministral-3-3B-Base-2512 with a Pixtral vision encoder and trained on roughly 54.1M samples, it reports 84.9% average F1 on text safety (matching GPT-OSS-Safeguard-20B), 83.8% on multimodal safety, and 91.3% on Mistral's adaptability benchmark — while fitting in 16GB of VRAM under an Apache 2.0 license.
NVIDIA AI Releases NOOA: An Object-Oriented Python Framework That Turns an...
NVIDIA Labs has open-sourced NOOA (NVIDIA Object-Oriented Agents), a model-agnostic Python framework for building AI agents. Agent development today is split across prompt templates,...

Microsoft’s SkillOpt Shows Optimized Agent Skill Artifacts Transfer Across Model Scales...
Most coverage of Microsoft's SkillOpt centers on its 52/52 result. The more consequential finding is in Section 4.3: the exported best_skill.md keeps working in environments it was never trained on. A Codex-trained SpreadsheetBench skill lifted Claude Code from 22.1 to 81.8, slightly above the 80.4 that harness reached training its own skill. Retention varies sharply by task type — 102% on spreadsheets, 10% on math — which is what makes the result worth reading closely.

DeepSeek Upgrades DeepSeek-V4-Flash-0731 with Major Agentic and Coding Gains
DeepSeek published DeepSeek-V4-Flash-0731 on Hugging Face and moved the official V4-Flash API into public beta on July 31, 2026. The model card is explicit...

Tencent Open-Sources AngelSpec: A Unified Training Framework for MTP and Block-Parallel...
Tencent has released AngelSpec, an open-source torch-native framework for training speculative-decoding draft models across six architectures. It introduces DFly, a block-diffusion drafter with hybrid target conditioning and a hidden-correction autoregressive head, and integrates D-cut for runtime-adaptive verification budgeting. On HY3-295B-A21B with TP=8, DFly-8 delivers a 1.98–2.40× speedup over autoregressive decoding across concurrency 4 to 64.

Sakana AI’s Error Diffusion Trains Dale-Compliant Dual-Stream Networks, Reaching 96.7% MNIST...
Backpropagation relies on weight transport, which biological circuits likely cannot implement. Sakana AI's Error Diffusion sidesteps that constraint, training dual-stream excitatory/inhibitory networks that obey Dale's principle. This piece breaks down how modulo error routing scales the rule from MNIST to CIFAR-10 and reinforcement learning, and what its task-dependent ablations reveal.

Soofi Consortium Releases Soofi S 30B-A3B: An Open Hybrid Mamba-Transformer MoE...
Soofi S 30B-A3B is an open Mamba-Transformer MoE model activating 3.2B of 31.6B parameters for German and English

Skyfall AI Releases MORPHEUS: A Persistent Enterprise Simulation Benchmark That Makes...
MORPHEUS from Skyfall AI is a persistent enterprise simulation platform for continual reinforcement learning. It runs worlds that never reset, using parameterisable regime shifts and a six-metric evaluation protocol. Across the platform, PPO, HER, EWC, and LCM all remain far below the theoretical upper bound.

Stanford Researchers Introduce TRACE: A Capability-Targeted Agentic Training System That Turns...
Agentic LLMs keep failing the same way because they lack specific, reusable capabilities. Stanford's TRACE diagnoses those gaps from an agent's own trajectories, synthesizes one verifiable training environment per capability, trains a LoRA adapter for each, and routes tokens across experts—improving τ²-Bench by +15.3 points and reaching 73.2% Pass@1 on SWE-bench Verified.

Meet NeuroVFM: A New Neuroimaging Foundation Model Trained With Vol-JEPA on...
NeuroVFM is a generalist neuroimaging foundation model from the University of Michigan, trained on 5.24M clinical MRI and CT volumes. Its Vol-JEPA base extends I-JEPA and V-JEPA to volumetric medical imaging, learning brain anatomy and pathology without radiology-report labels.
Ant Group’s Robbyant Unveils LingBot-VA 2.0: A Causal Video-Action Model Built...
Ant Group's Robbyant has released the LingBot-VA 2.0 technical report — a Physical AI video-action foundation model built from scratch for embodiment rather than fine-tuned from a video generator. It predicts future states ahead of execution through Foresight Reasoning, re-grounds on every real observation, and reaches 225 Hz asynchronous control. We break down the causal DiT, the sparse-MoE video stream, the semantic visual-action tokenizer, and where the paper's own numbers don't line up.

Kyutai Releases MuScriptor: An Open-Weight Decoder-Only Transformer for Multi-Instrument Music Transcription...
MuScriptor is an open-weight, decoder-only Transformer from Kyutai and Mirelo. Trained on 170k real recordings plus 1.45M synthetic MIDIs, it transcribes full multi-instrument mixes into MIDI. The article covers its three-stage pipeline, benchmarks against YourMT3+, instrument conditioning, and setup, with an interactive explainer demo.
Google Research Introduces SensorFM: A Wearable Health Foundation Model Pretrained on...
SensorFM, a wearable health foundation model from Google Research, Google DeepMind, and university collaborators. We walk through its ViT-1D masked-autoencoder backbone, pretrained on more than one trillion minutes of unlabeled sensor signals from 5,000,000 consented participants. We examine the co-scaling results across four model sizes and four data volumes, including the case where capacity outruns data. We show how frozen embeddings plus a PCA-50 linear probe beat feature-engineered baselines on 34 of 35 tasks. We also review the agentic classroom that searched 30,516 prediction heads, and the clinician evaluation grounding a Personal Health Agent.

Meet LingBot-World-Infinity: An Open Causal World Model With An Agentic Harness
Robbyant, Ant Group's embodied-intelligence unit, has released LingBot-World-Infinity (LingBot-World 2.0). It is a 14B causal video generation model that behaves as an interactive world simulator. The core idea is the Mixture of Bidirectional and Autoregressive (MoBA) attention mask, paired with distribution matching distillation applied over long self-rollout trajectories. Together they target long-horizon drift, the failure mode that smears textures and warps geometry in most interactive world models. A Director-Pilot agentic harness wraps the generator, where a VLM proposes events and the Diffusion Transformer renders them. The report shows a single 60-minute uninterrupted session covering 20 scenarios. But the release is thinner than the paper: one checkpoint, a 480P reference script, no deployment code, no quantitative benchmarks, and a non-commercial CC BY-NC-SA 4.0 license.
Meet Nemotron Labs 3 Puzzle 75B A9B: A Compressed Hybrid MoE...
NVIDIA has released Nemotron-Labs-3-Puzzle-75B-A9B, a compressed variant of Nemotron-3-Super. Iterative Puzzle alternates hardware-aware structural compression with short knowledge distillation recovery phases. The model drops from 120.7B total / 12.8B active parameters to 75.3B / 9.3B. On a single 8xB200 node it delivers 2.03x Super's total throughput at 100 tok/s per user. On one H100, 1M-token concurrency rises from 1 request to 8.
Robbyant Releases LingBot-VLA 2.0: An Open-Source 6B Vision-Language-Action (VLA) Model for...
Ant Group's Robbyant has released LingBot-VLA 2.0, an Apache-2.0 vision-language-action model for cross-embodiment robot manipulation. The 6B checkpoint is pretrained on roughly 60,000 hours of data, spanning 50,000 hours of robot trajectories across 20 robot configurations and 10,000 hours of egocentric human video. It maps every embodiment into a single 55-dimensional canonical action space, covering arms, dexterous hands, waists, heads, and mobile bases. A token-level, auxiliary-loss-free Mixture-of-Experts action expert scales capacity without adding a load-balancing loss. Dual-query distillation from LingBot-Depth and DINO-Video adds geometric and temporal supervision for future-aware control. On the GM-100 generalist benchmark it outperforms π0.5 and LingBot-VLA-1.0 on both evaluated platforms.

Ant Group’s Robbyant Open-Sources LingBot-Vision: A 1B Boundary-Centric Vision Foundation Model...
Ant Group's Robbyant open-sourced LingBot-Vision, a self-supervised ViT family for dense spatial perception. Masked boundary modeling makes image boundaries a native training signal. The 1B backbone matches or surpasses larger models, and initializes LingBot-Depth 2.0.
NVIDIA HORIZON: A Hands-Free Agent that Evolves Git Worktrees and Hits...
A hands-free NVIDIA agent framework hosts each RTL problem as a versioned repository, reaching 100% completion across benchmarks.
NVIDIA Releases Nemotron-Labs-TwoTower: an Open-Weight Diffusion Language Model Built on a...
NVIDIA has released Nemotron-Labs-TwoTower, a diffusion language model built on a pretrained autoregressive backbone. It ships as open weights under the NVIDIA Nemotron Open...
Meta AI Releases Brain2Qwerty v2: A Non-Invasive MEG Brain-to-Text Pipeline Decoding...
Meta AI releases Brain2Qwerty v2, a non-invasive MEG brain-to-text pipeline reaching 61% word accuracy with open training code.

DeepSeek Releases DSpark, a Speculative Decoding Framework That Accelerates DeepSeek-V4 Per-User...
DeepSeek open-sourced DSpark, a speculative decoding framework that attaches a draft module to existing DeepSeek-V4 weights. It pairs a parallel draft backbone with a lightweight Markov head to cut suffix decay, then adds confidence-scheduled verification that tailors how many tokens get checked to real-time GPU load. Offline, accepted length rises 16–31% over DFlash and Eagle3; in production it speeds per-user generation 57–85% over the MTP-1 baseline, losslessly. The training repo, DeepSpec, ships under MIT.
Baidu Releases Unlimited OCR, a 3B Model That Keeps the KV...
Baidu open-sourced Unlimited OCR, a 3B-parameter MoE model that parses dozens of document pages in a single forward pass. Its Reference Sliding Window Attention (R-SWA) holds the KV cache constant, so memory and latency stay flat as output grows. It scores 93.23 on OmniDocBench v1.5, beating the DeepSeek OCR baseline by 6.22 points, under an MIT license.
NVIDIA AI Introduce SpatialClaw: A Training-Free Agent That Treats Code as...
SpatialClaw is a training-free agent that writes Python in a persistent kernel, composing perception tools for 3D spatial reasoning
VibeThinker-3B: A 3B Dense Reasoning Model Built on Qwen2.5-Coder-3B With the...
VibeThinker-3B, a 3B MIT-licensed reasoning model matching DeepSeek V3.2 and Kimi K2.5 on verifiable benchmarks.
OpenAI Releases LifeSciBench, a 750-Task Benchmark Grading AI Models on Real...
OpenAI's LifeSciBench evaluates whether frontier AI can handle real life-science research across 750 expert-authored tasks, seven workflows, and seven biological domains. Built by 173 PhD scientists with 19,020 rubric criteria, it grades reasoning and decisions, not just recall. The best model, GPT-Rosalind, passes 36.1%, leaving large headroom on artifacts, exact outputs, and operational calls.
MiniMax Sparse Attention (MSA): a Two-Branch Block-Sparse Attention Trained on a...
MiniMax released MSA, a sparse attention built on Grouped Query Attention. A lightweight Index Branch selects Top-k key-value blocks per query and GQA group; the Main Branch attends only to those blocks. It matches GQA on downstream benchmarks while reducing per-token attention compute 28.4× at 1M context.
Meet Flash-KMeans: An IO-Aware, Exact K-Means That Runs Over 200× Faster...
Flash-KMeans is an open-source, IO-aware implementation of standard Lloyd's k-means in Triton GPU kernels. It does not change the math or approximate. FlashAssign removes distance-matrix materialization; Sort-Inverse Update eliminates atomic contention. On an NVIDIA H200, it reports 17.9× end-to-end, 33× over cuML, and over 200× over FAISS.
A New Study from Harvard and Perplexity Finds AI Agents Perform...
A new Harvard and Perplexity paper uses matched-pair sessions to compare an autonomous agent with a search assistant. It finds large gains in autonomy, time, and cost, plus broader scope of work attempted.
Meet Harness-1: A 20B Retrieval Subagent Trained With Reinforcement Learning Inside...
UIUC and Chroma's Harness-1 is a 20B retrieval subagent trained with reinforcement learning inside a stateful search harness. The harness maintains the bookkeeping — candidate pool, importance-tagged curated set, evidence graph, verification records — while the policy decides what to search, curate, verify, and when to stop. It reaches 0.730 average curated recall across eight benchmarks, beating the next open subagent by 11.4 points and trailing only Opus-4.6. Weights and harness code are public.
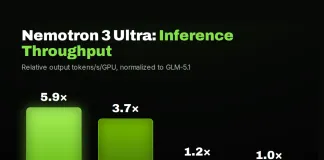
NVIDIA AI Releases Nemotron 3 Ultra: An Open 550B Mixture-of-Experts Hybrid...
NVIDIA has released Nemotron 3 Ultra, a 550B total (55B active) open Mixture-of-Experts hybrid Mamba-Transformer for long-running agents. It pairs a 1M-token context with up to ~6x higher inference throughput than comparable open LLMs at on-par accuracy, and ships with open weights, training data, and recipes under OpenMDW-1.1.
Meet OpenJarvis: A Local-First Framework for On-Device Personal AI Agents with...
Stanford researchers released OpenJarvis, an open-source framework that runs inference, agents, memory, and learning entirely on-device. It decomposes a personal AI system into five composable primitives — Intelligence, Engine, Agents, Tools & Memory, and Learning — and lands within 3.2 points of the best cloud model at roughly 800× lower marginal API cost.
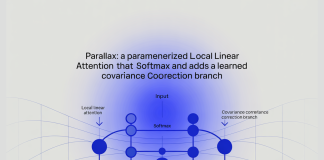
Parallax: A Parameterized Local Linear Attention That Keeps Softmax and Adds...
Parallax replaces LLA's per-query solver with a learned projector, doubling arithmetic intensity and improving perplexity at 0.6B and 1.7B.
NVIDIA Introduces X-Token: Projection-Guided Cross-Tokenizer KD That Outperforms GOLD by +3.82...
NVIDIA's X-Token fixes two structural failures in GOLD and improves GSM8k accuracy from 2.56 to 15.54
Sakana AI Proposes DiffusionBlocks: a Block-wise Training Framework That Converts Residual...
DiffusionBlocks converts residual networks into independently trainable blocks by interpreting layer updates as reverse diffusion denoising steps.
NVIDIA Releases Polar, a Token-Faithful Rollout Framework for GRPO Training Across...
NVIDIA researchers have introduced Polar, a rollout framework that trains language agents using reinforcement learning without modifying their agent harnesses. Polar places a model API proxy between the harness and the inference server, capturing token-level interactions and reconstructing trainer-ready trajectories. Using GRPO on a Qwen3.5-4B base model, Polar improves SWE-Bench Verified pass@1 by 22.6 points under the Codex harness, 4.8 points under Claude Code, and 6.2 points under Pi. The framework is registered as a NeMo Gym environment and released under the ProRL Agent Server repository.
MEMO: A Modular Framework for Training a Dedicated Memory Model on...
Researchers from NUS, MIT, and A*STAR propose MEMO, a modular framework that encodes corpus knowledge into a separate trainable MEMORY model.
NVIDIA AI Releases Gated DeltaNet-2: A Linear Attention Layer That Decouples...
Linear attention squeezes the unbounded KV cache into a fixed-size recurrent state, but editing that memory without scrambling existing associations is hard. Prior delta-rule models like Gated DeltaNet and KDA use one scalar gate to control both erasing old content and writing new content. NVIDIA's Gated DeltaNet-2 decouples these into a channel-wise erase gate b_t on the key axis and a channel-wise write gate w_t on the value axis. At 1.3B parameters trained on 100B FineWeb-Edu tokens, it outperforms Mamba-2, Gated DeltaNet, KDA, and Mamba-3 across language modeling, commonsense reasoning, and long-context retrieval — with the largest gains on RULER S-NIAH and multi-key needle retrieval.
Nous Research Releases Contrastive Neuron Attribution (CNA): Sparse MLP Circuit Steering...
Nous Research releases Contrastive Neuron Attribution (CNA), a method that identifies and ablates sparse MLP neuron circuits to steer LLM behavior — no sparse autoencoder training, no weight modification, and no degradation of general capability benchmarks.
NVIDIA AI Releases Nemotron-Labs-Diffusion: A Tri-Mode Language Model with 6× Tokens...
NVIDIA researchers have released Nemotron-Labs-Diffusion, a language model family that unifies three decoding modes in one architecture. The model supports autoregressive (AR) decoding, diffusion-based...
Meet MemPrivacy: An Edge-Cloud Framework that Uses Local Reversible Pseudonymization to...
As LLM-powered agents move from research to production, one design tension is becoming harder to ignore: the more useful cloud-hosted memory becomes, the more...
NVIDIA Introduces a 4-Bit Pretraining Methodology Using NVFP4, Validated on a...
NVIDIA introduces a 4-bit pretraining methodology built around the NVFP4 microscaling format — combining selective BF16 layers, 16×16 Random Hadamard Transforms on Wgrad inputs, 2D weight scaling, and stochastic rounding on gradients — validated on a 12B hybrid Mamba-Transformer trained on 10 trillion tokens, the longest publicly documented 4-bit pretraining run, with downstream accuracy closely tracking the FP8 baseline (62.58% vs 62.62% on MMLU-Pro).
Nous Research Proposes Lighthouse Attention: A Training-Only Selection-Based Hierarchical Attention That...
Nous Research has published Lighthouse Attention, a selection-based hierarchical attention mechanism that wraps around standard scaled dot-product attention during pretraining and is removed afterward. Unlike prior methods such as NSA and HISA that pool only keys and values, Lighthouse pools Q, K, and V symmetrically across a multi-resolution pyramid, reducing the attention call from O(N·S·d) to O(S²·d) and running stock FlashAttention on a small dense sub-sequence. Tested on a 530M Llama-3-style model at 98K context, it achieves a 1.40–1.69× end-to-end wall-clock speedup against a cuDNN SDPA baseline with matching or lower final training loss.
NVIDIA Introduces SANA-WM: A 2.6B-Parameter Open-Source World Model That Generates Minute-Scale...
Researchers from NVIDIA introduce SANA-WM, an open-source camera-controlled world model that generates 60-second, 720p videos with precise 6-DoF camera control — trained on 64 H100 GPUs and deployable on a single RTX 5090.
Nous Research Releases Token Superposition Training to Speed Up LLM Pre-Training...
Nous Research releases Token Superposition Training (TST), a two-phase pre-training method that cuts wall-clock training time by up to 2.5x at matched FLOPs by averaging contiguous token embeddings into bags during Phase 1 and reverting to standard next-token prediction in Phase 2 — without changing the model architecture, tokenizer, optimizer, or inference-time behavior. Validated at 270M, 600M, 3B dense, and 10B-A1B MoE scales.
Fastino Labs Open-Sources GLiGuard: A 300M Parameter Safety Moderation Model That...
Fastino Labs has released GLiGuard, a 300M parameter open-source safety moderation model that evaluates four safety tasks — prompt safety, jailbreak strategy detection, harm category classification, and refusal detection — in a single forward pass. Built on an encoder architecture rather than the decoder-only design used by most guardrail models, GLiGuard achieves up to 16x higher throughput and 16.6x lower latency than current state-of-the-art models, while matching or exceeding the accuracy of models 23 to 90 times its size across nine safety benchmarks. Model weights are available under the Apache 2.0 license on Hugging Face.
Tilde Research Introduces Aurora: A Leverage-Aware Optimizer That Fixes a Hidden...
Researchers at Tilde Research have released Aurora, a new optimizer for training neural networks that addresses a structural flaw in the widely-used Muon optimizer....
Meta and Stanford Researchers Propose Fast Byte Latent Transformer That Reduces...
Researchers from Meta FAIR and Stanford propose three inference methods for the Byte Latent Transformer that reduce memory-bandwidth cost by over 50% without subword tokenization.
Sakana AI and NVIDIA Introduce TwELL with CUDA Kernels for 20.5%...
Sakana AI and NVIDIA Researchers demonstrate that simple L1 regularization can induce over 99% sparsity in feedforward layers with negligible downstream performance impact, and translate that sparsity into real GPU throughput gains using new sparse data formats and fused CUDA kernels.
NVIDIA AI Releases Star Elastic: One Checkpoint that Contains 30B, 23B,...
NVIDIA researchers have introduced Star Elastic, a post-training method that embeds multiple nested reasoning models — at 30B, 23B, and 12B parameter scales — inside a single checkpoint, eliminating the need for separate training runs or stored model weights per variant. Built on the Nemotron Elastic framework and applied to Nemotron Nano v3, the method trains all three variants in a single 160B-token run, achieving a 360× token reduction compared to pretraining each model from scratch. Beyond training efficiency, Star Elastic introduces elastic budget control — a novel inference scheme that uses a smaller submodel for the thinking phase and the full model for the final answer — delivering up to 16% higher accuracy and 1.9× lower latency compared to standard budget control, while nested FP8 and NVFP4 checkpoints bring the full model family within reach of RTX-class GPUs.
Anthropic Introduces Natural Language Autoencoders That Convert Claude’s Internal Activations Directly...
When you type a message to Claude, something invisible happens in the middle. The words you send get converted into long lists of numbers...
Meta AI Releases NeuralBench: A Unified Open-Source Framework to Benchmark NeuroAI...
Meta AI team has released NeuralBench, a unified open-source framework for benchmarking NeuroAI models, alongside NeuralBench-EEG v1.0 — the largest open EEG benchmark to date, covering 36 tasks, 94 datasets, and 14 deep learning architectures evaluated under a single standardized interface across 9,478 subjects and 13,603 hours of brain recordings.
OpenAI Introduces MRC (Multipath Reliable Connection): A New Open Networking Protocol...
MRC (Multipath Reliable Connection) is a new open networking protocol developed by OpenAI in partnership with AMD, Broadcom, Intel, Microsoft, and NVIDIA that improves GPU networking performance and resilience in large-scale AI training clusters by spreading packets across hundreds of paths simultaneously, recovering from network failures in microseconds, and enabling supercomputers with over 100,000 GPUs to be built using only two tiers of Ethernet switches.
Zyphra Releases ZAYA1-8B: A Reasoning MoE Trained on AMD Hardware That...
Zyphra releases ZAYA1-8B, a reasoning Mixture of Experts model with only 760M active parameters that outperforms open-weight models many times its size on math and coding benchmarks — closing in on DeepSeek-V3.2 and surpassing Claude 4.5 Sonnet on HMMT'25 with its novel Markovian RSA test-time compute method. Trained end-to-end on AMD Instinct MI300 hardware and released under Apache 2.0, it sets a new standard for intelligence density in the small language model weight class.
Zyphra Introduces Tensor and Sequence Parallelism (TSP): A Hardware-Aware Training and...
Zyphra Introduces Tensor and Sequence Parallelism (TSP): A Folded Parallelism Strategy That Reduces Both Parameter and Activation Memory Across the Same GPU Axis

Sakana AI Introduces KAME: A Tandem Speech-to-Speech Architecture That Injects LLM...
Sakana AI Introduces KAME: A Tandem Architecture That Injects Real-Time LLM Knowledge Into Speech-to-Speech Conversational AI Without Adding Latency
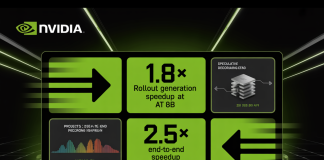
A New NVIDIA Research Shows Speculative Decoding in NeMo RL Achieves...
A new paper from NVIDIA Research integrates speculative decoding directly into NeMo RL with a vLLM backend, delivering lossless rollout acceleration at both 8B and projected 235B model scales.
Microsoft Research’s World-R1 Uses Flow-GRPO and 3D-Aware Rewards to Inject Geometric...
Microsoft Research's World-R1 Uses Reinforcement Learning to Force 3D Consistency Into Text-to-Video Models
Meta AI Releases Sapiens2: A High-Resolution Human-Centric Vision Model for Pose,...
Meta Reality Labs releases a new foundation model family for human-centric vision that pushes pose estimation, segmentation, and 3D geometry to new state-of-the-art levels — all from a single backbone.
DeepSeek AI Releases DeepSeek-V4: Compressed Sparse Attention and Heavily Compressed Attention...
DeepSeek-AI has released a preview version of the DeepSeek-V4 series: two Mixture-of-Experts (MoE) language models built around one core challenge making one-million-token context windows...
Google Cloud AI Research Introduces ReasoningBank: A Memory Framework that Distills...
A new memory framework from Google Cloud AI Research and UIUC gives LLM agents the ability to distill generalizable reasoning strategies from both successful and failed experiences — and combines that with test-time scaling to create agents that genuinely improve over time.
Google Introduces Simula: A Reasoning-First Framework for Generating Controllable, Scalable Synthetic...
Training powerful AI models depends on one resource that is quietly running out: specialized data. While the internet provided a seemingly infinite supply of...
Moonshot AI and Tsinghua Researchers Propose PrfaaS: A Cross-Datacenter KVCache Architecture...
For years, the way large language models handle inference has been stuck inside a box — literally. The high-bandwidth RDMA networks that make modern...
Google AI Releases Auto-Diagnose: An Large Language Model LLM-Based System to...
If you have ever stared at thousands of lines of integration test logs wondering which of the sixteen log files actually contains your bug,...
UCSD and Together AI Research Introduces Parcae: A Stable Architecture for Looped...
The dominant recipe for building better language models has not changed much since the Chinchilla era: spend more FLOPs, add more parameters, train on...

NVIDIA and the University of Maryland Researchers Released Audio Flamingo Next...
Understanding audio has always been the multimodal frontier that lags behind vision. While image-language models have rapidly scaled toward real-world deployment, building open models...
Meta AI and KAUST Researchers Propose Neural Computers That Fold Computation,...
Researchers from Meta AI and the King Abdullah University of Science and Technology (KAUST) have introduced Neural Computers (NCs) — a proposed machine form...
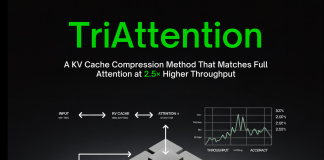
Researchers from MIT, NVIDIA, and Zhejiang University Propose TriAttention: A KV...
Long-chain reasoning is one of the most compute-intensive tasks in modern large language models. When a model like DeepSeek-R1 or Qwen3 works through a...
Alibaba’s Tongyi Lab Releases VimRAG: a Multimodal RAG Framework that Uses...
Retrieval-Augmented Generation (RAG) has become a standard technique for grounding large language models in external knowledge — but the moment you move beyond plain...
Meta Superintelligence Lab Releases Muse Spark: A Multimodal Reasoning Model With...
Meta Superintelligence Labs recently made a significant move by unveiling 'Muse Spark' — the first model in the Muse family. Muse Spark is a...
Google AI Research Introduces PaperOrchestra: A Multi-Agent Framework for Automated AI...
Writing a research paper is brutal. Even after the experiments are done, a researcher still faces weeks of translating messy lab notes, scattered results...

Meet OSGym: A New OS Infrastructure Framework That Manages 1,000+ Replicas...
Training AI agents that can actually use a computer — opening apps, clicking buttons, browsing the web, writing code — is one of the...
Z.AI Introduces GLM-5.1: An Open-Weight 754B Agentic Model That Achieves SOTA...
Z.AI, the AI platform developed by the team behind the GLM model family, has released GLM-5.1 — its next-generation flagship model developed specifically for...
Meta AI Releases EUPE: A Compact Vision Encoder Family Under 100M...
Running powerful AI on your smartphone isn't just a hardware problem — it's a model architecture problem. Most state-of-the-art vision encoders are enormous, and...
Meet MaxToki: The AI That Predicts How Your Cells Age —...
Most foundation models in biology have a fundamental blind spot: they see cells as frozen snapshots. Give a model a single-cell transcriptome — a...
Netflix AI Team Just Open-Sourced VOID: an AI Model That Erases...
Video editing has always had a dirty secret: removing an object from footage is easy; making the scene look like it was never there...
Google DeepMind’s Research Lets an LLM Rewrite Its Own Game Theory...
Designing algorithms for Multi-Agent Reinforcement Learning (MARL) in imperfect-information games — scenarios where players act sequentially and cannot see each other's private information, like...
TII Releases Falcon Perception: A 0.6B-Parameter Early-Fusion Transformer for Open-Vocabulary Grounding and Segmentation from...
In the current landscape of computer vision, the standard operating procedure involves a modular 'Lego-brick' approach: a pre-trained vision encoder for feature extraction paired...

Salesforce AI Research Releases VoiceAgentRAG: A Dual-Agent Memory Router that Cuts...
In the world of voice AI, the difference between a helpful assistant and an awkward interaction is measured in milliseconds. While text-based Retrieval-Augmented Generation...
NVIDIA AI Unveils ProRL Agent: A Decoupled Rollout-as-a-Service Infrastructure for Reinforcement...
NVIDIA researchers introduced ProRL AGENT, a scalable infrastructure designed for reinforcement learning (RL) training of multi-turn LLM agents. By adopting a 'Rollout-as-a-Service' philosophy, the...
Meta Releases TRIBE v2: A Brain Encoding Model That Predicts fMRI...
Neuroscience has long been a field of divide and conquer. Researchers typically map specific cognitive functions to isolated brain regions—like motion to area V5...

NVIDIA AI Introduces PivotRL: A New AI Framework Achieving High Agentic...
Post-training Large Language Models (LLMs) for long-horizon agentic tasks—such as software engineering, web browsing, and complex tool use—presents a persistent trade-off between computational efficiency...

Google Introduces TurboQuant: A New Compression Algorithm that Reduces LLM Key-Value...
The scaling of Large Language Models (LLMs) is increasingly constrained by memory communication overhead between High-Bandwidth Memory (HBM) and SRAM. Specifically, the Key-Value (KV)...