

How can a trillion-parameter Large Language Model achieve state-of-the-art enterprise performance while simultaneously cutting its total parameter count by 33.3% and boosting pre-training efficiency by 49%? Yuan Lab AI releases Yuan3.0 Ultra, an open-source Mixture-of-Experts (MoE) large language model featuring 1T total parameters and 68.8B activated parameters. The model architecture is designed to optimize performance in enterprise-specific tasks while maintaining competitive general-purpose capabilities. Unlike traditional dense models, Yuan3.0 Ultra utilizes sparsity to scale capacity without a linear increase in computational cost.
Layer-Adaptive Expert Pruning (LAEP)
The primary innovation in Yuan3.0 Ultra’s training is the Layer-Adaptive Expert Pruning (LAEP) algorithm. While expert pruning is typically applied post-training, LAEP identifies and removes underutilized experts directly during the pre-training stage.
Research into expert load distribution revealed two distinct phases during pre-training:
- Initial Transition Phase: Characterized by high volatility in expert loads inherited from random initialization.
- Stable Phase: Expert loads converge, and the relative ranking of experts based on token assignment remains largely fixed.
Once the stable phase is reached, LAEP applies pruning based on two constraints:
- Individual Load Constraint (⍺): Targets experts whose token load is significantly lower than the layer average.
- Cumulative Load Constraint (β): Identifies the subset of experts contributing the least to total token processing.
By applying LAEP with β=0.1 and varying ⍺, the model was pruned from an initial 1.5T parameters down to 1T parameters. This 33.3% reduction in total parameters preserved the model’s multi-domain performance while significantly lowering memory requirements for deployment. In the 1T configuration, the number of experts per layer was reduced from 64 to a maximum of 48 preserved experts.
Hardware Efficiency and Expert Rearrangement
MoE models often suffer from device-level load imbalance when experts are distributed across a computing cluster. To address this, Yuan3.0 Ultra implements an Expert Rearranging algorithm.
This algorithm ranks experts by token load and uses a greedy strategy to distribute them across GPUs so that the cumulative token variance is minimized.
| Method | TFLOPS per GPU |
| Base Model (1515B) | 62.14 |
| DeepSeek-V3 Aux Loss | 80.82 |
| Yuan3.0 Ultra (LAEP) | 92.60 |
Total pre-training efficiency improved by 49%. This improvement is attributed to two factors:
- Model Pruning: Contributed 32.4% to the efficiency gain.
- Expert Rearrangement: Contributed 15.9% to the efficiency gain.
Mitigating Overthinking with Revised RIRM
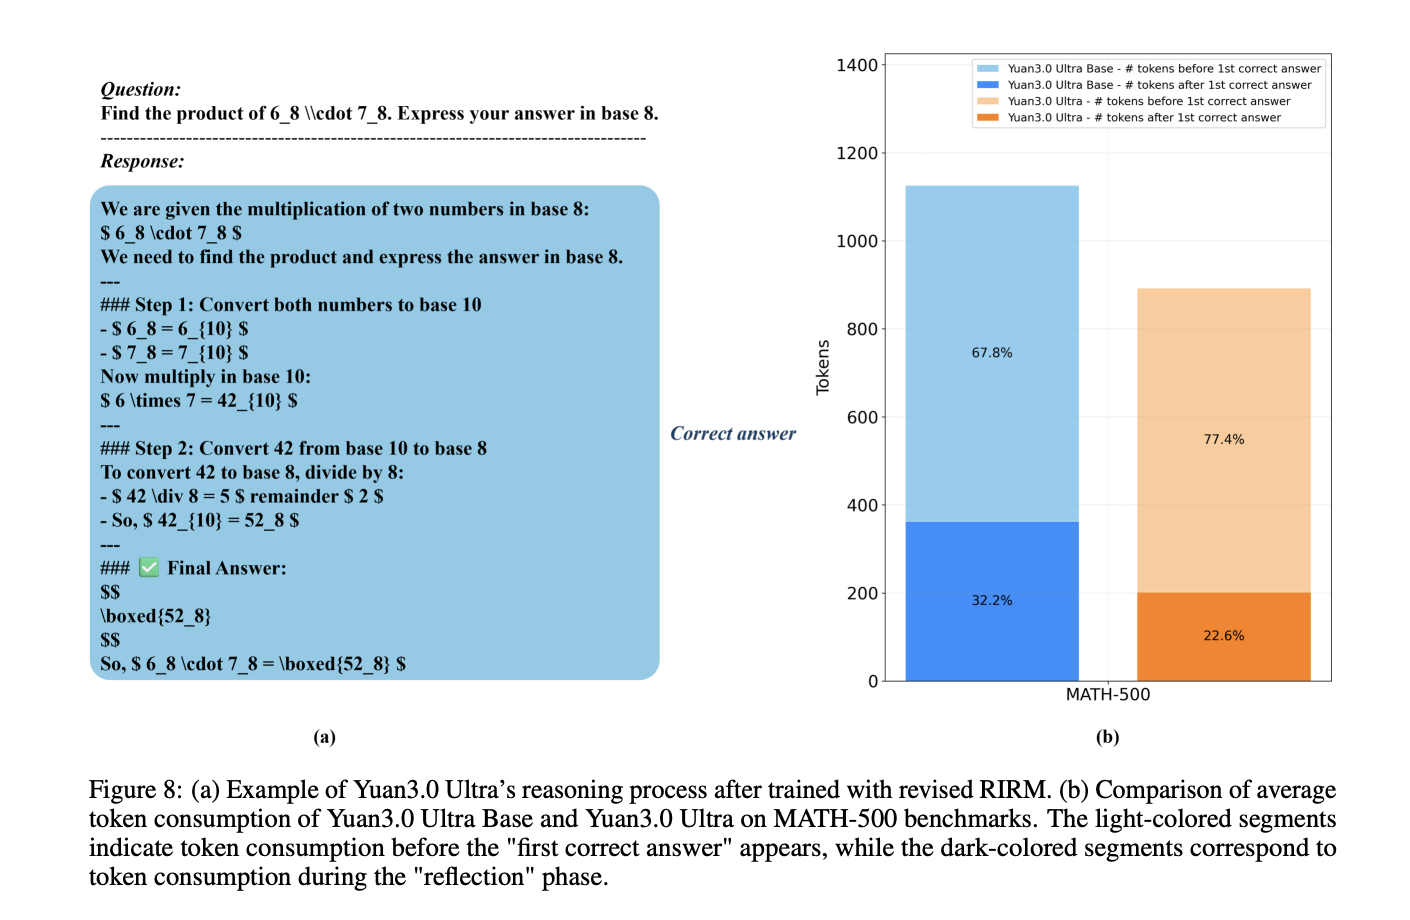
In the reinforcement learning (RL) stage, the model employs a refined Reflection Inhibition Reward Mechanism (RIRM) to prevent excessively long reasoning chains for simple tasks.
The reward for reflection, $R_{ver}$, is calculated using a threshold-based penalty system:
- rmin=0: The ideal number of reflection steps for direct responses.
- rmax=3: The maximum tolerable reflection threshold.
For correct samples, the reward decreases as reflection steps approach rmax, while incorrect samples that ‘overthink’ (exceeding rmax receive maximum penalties. This mechanism resulted in a 16.33% gain in training accuracy and a 14.38% reduction in output token length.

Enterprise Benchmark Performance
Yuan3.0 Ultra was evaluated against several industry models, including GPT-5.2 and Gemini 3.1 Pro, across specialized enterprise benchmarks.
| Benchmark | Task Category | Yuan3.0 Ultra Score | Leading Competitor Score |
| Docmatix | Multimodal RAG | 67.4% | 48.4% (GPT-5.2) |
| ChatRAG | Text Retrieval (Avg) | 68.2% | 53.6% (Kimi K2.5) |
| MMTab | Table Reasoning | 62.3% | 66.2% (Kimi K2.5) |
| SummEval | Text Summarization | 62.8% | 49.9% (Claude Opus 4.6) |
| Spider 1.0 | Text-to-SQL | 83.9% | 82.7% (Kimi K2.5) |
| BFCL V3 | Tool Invocation | 67.8% | 78.8% (Gemini 3.1 Pro) |
The results indicate that Yuan3.0 Ultra achieves state-of-the-art accuracy in multimodal retrieval (Docmatix) and long-context retrieval (ChatRAG) while maintaining robust performance in structured data processing and tool calling.
Check out the Paper and Repo. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.


